Tencent Hy4 Review: Specs, Pricing and Benchmarks
Tencent Hy4 is an AI model built for agents and long real-world tasks. Tencent released it on November 4, 2026.
You can run Hy4 through AI/ML API with the model ID tencent/hy4. It has a 1M-token context and costs $0.882 per million input tokens and $2.646 per million output tokens.
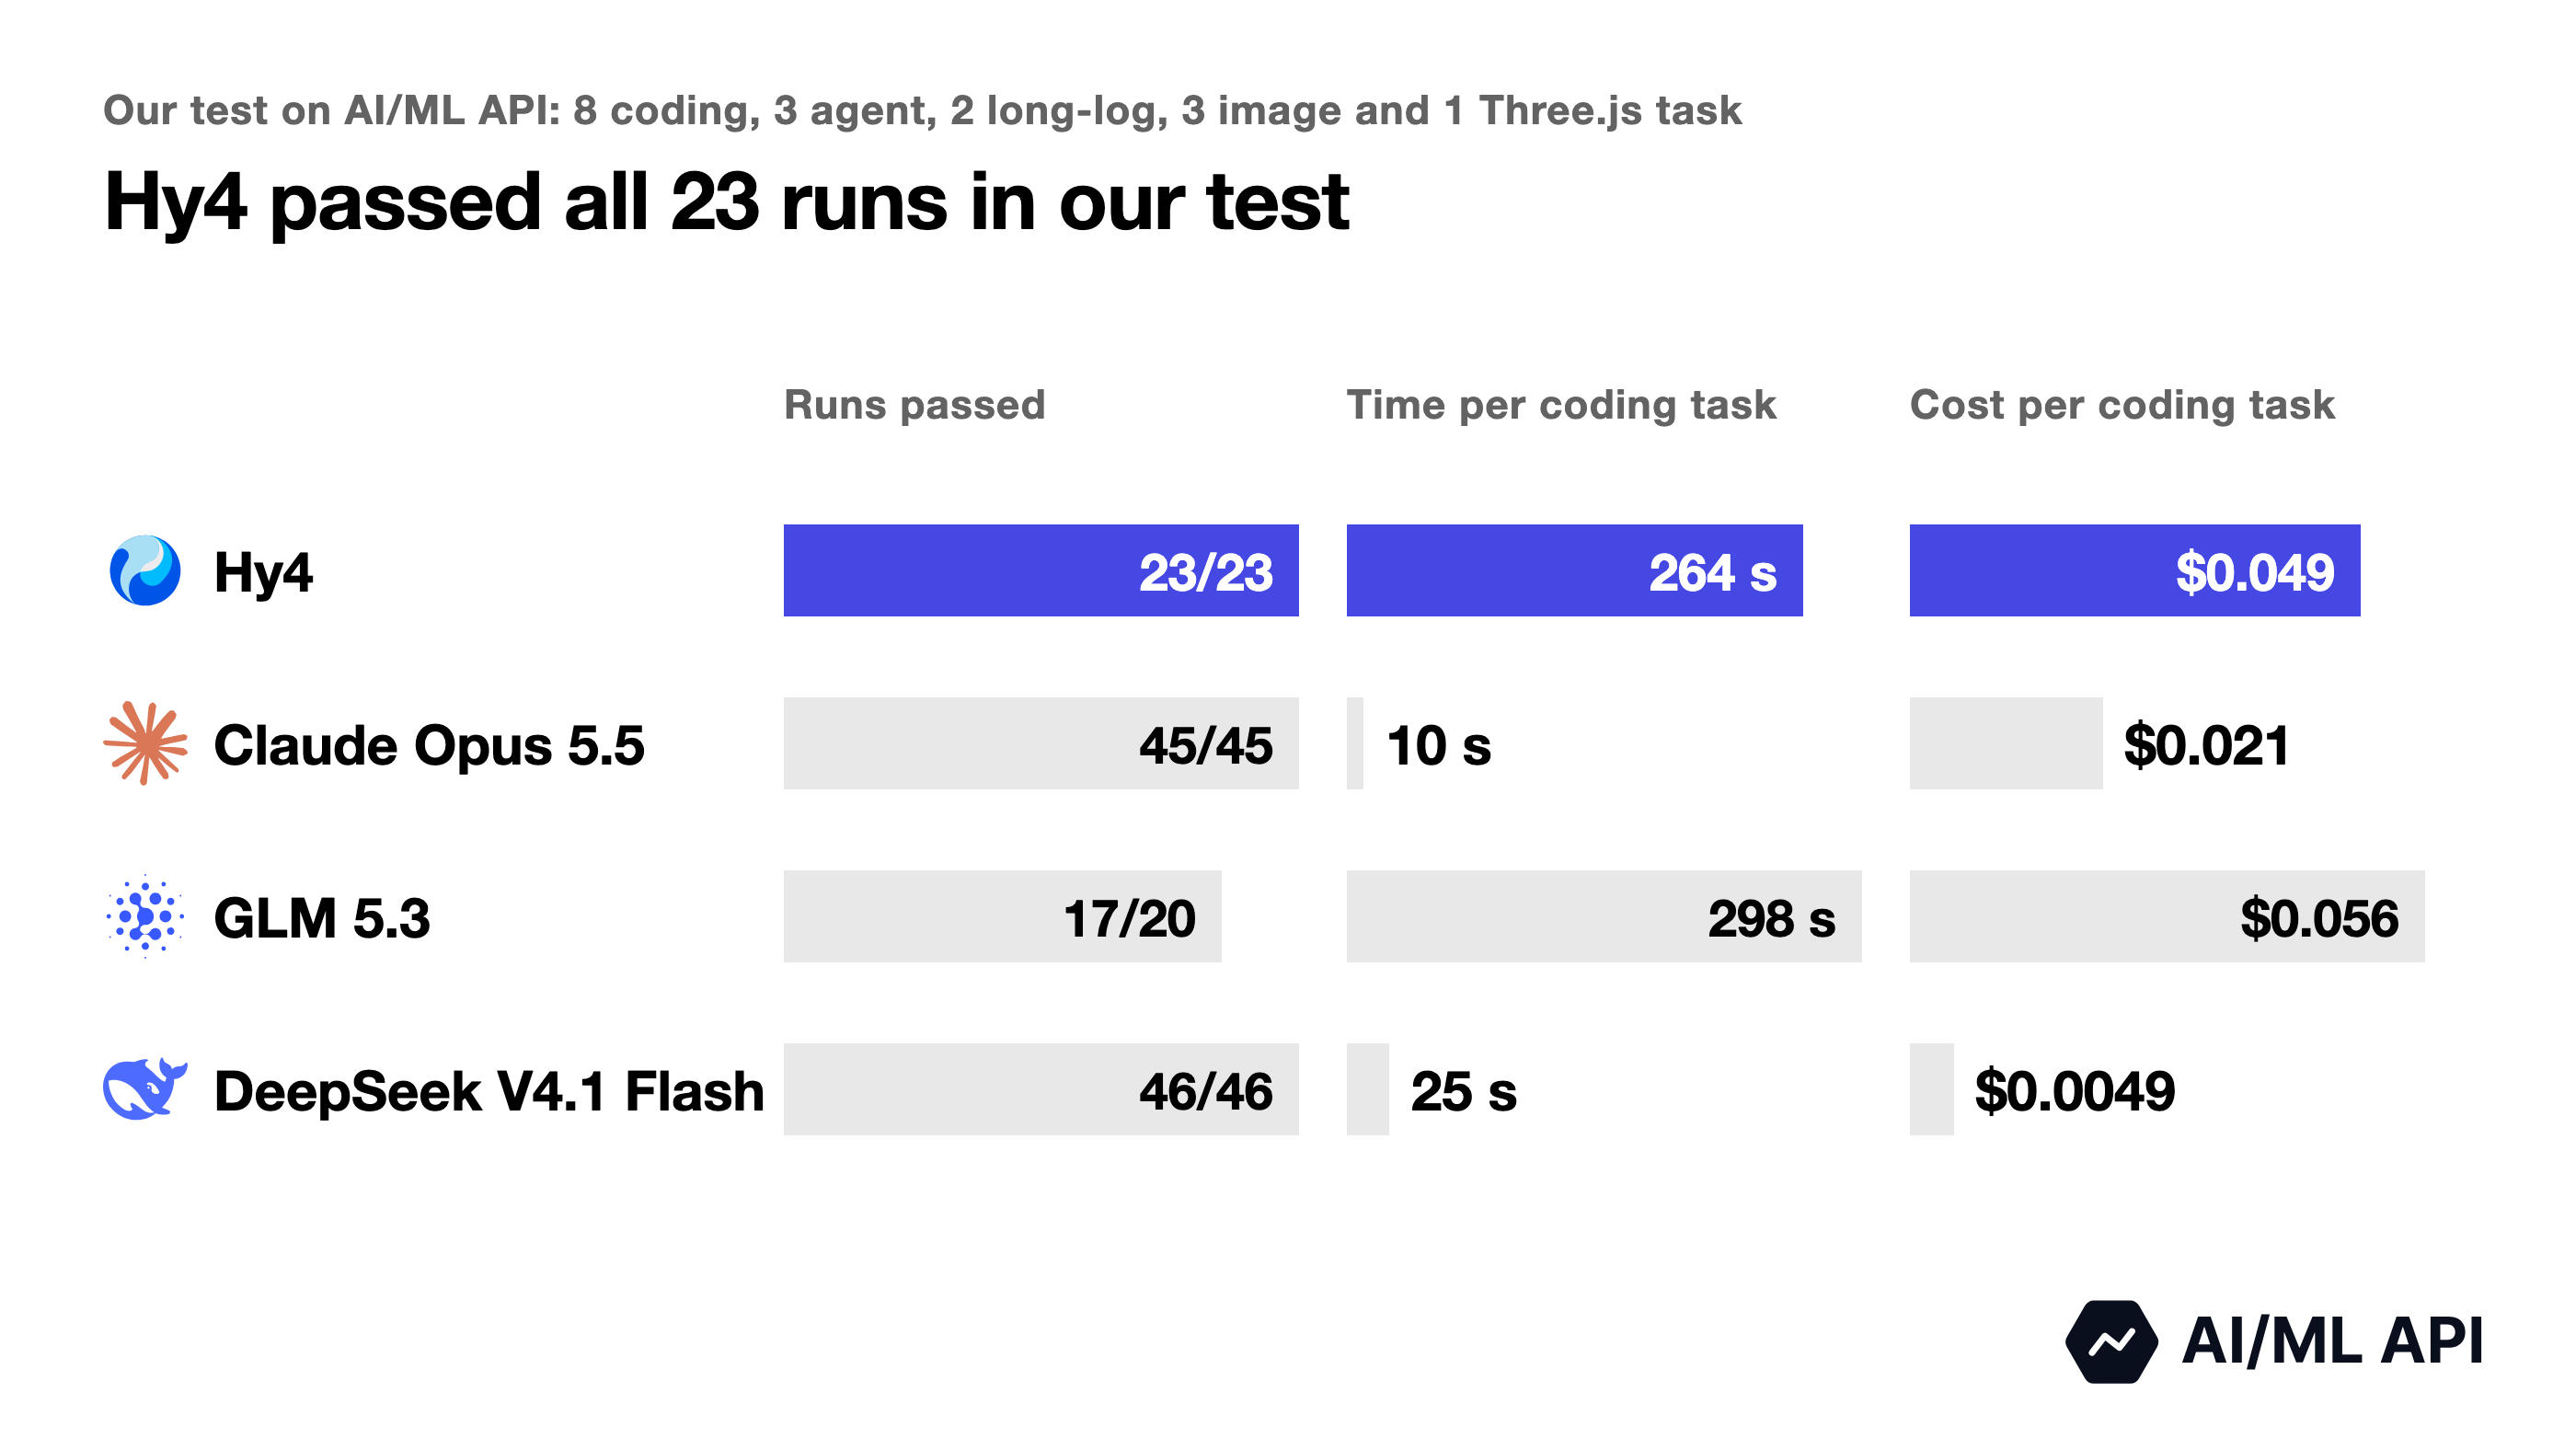
In our test, Hy4 passed all 23 of its runs. A median task cost less on Hy4 than on Claude Opus 5.5 and GLM 5.3.
We checked all prices, benchmark scores and test results on November 4, 2026.
What is the Tencent Hy4 model?
Hy4 is the newest model in the Tencent Hy family (formerly Tencent Hunyuan).
Tencent first released an early version, Hy4 Preview, on August 27, 2026. Hy4 is the final version. Next, Tencent plans Hy4 Flash, which will be cheaper and faster.
Tencent built Hy4 for five kinds of work:
- frontend and game development
- finance and office documents
- scientific research
- operating a computer
- personal assistant tasks across chats, email and calendars
For game development, Tencent worked with developers from its Interactive Entertainment Group on the training data. It also adapted Hy4 for Unreal Engine, Unity and Godot.
For finance, Tencent tested Hy4 with 213 finance professionals on 579 real tasks. Hy4 averaged 3.04 points on Tencent's scale, ahead of DeepSeek V4.1 Flash (2.97), Kimi K3.1 Pro (2.68) and GLM 5.3 (2.68).
Hy4 specs
| Specification | Value | Note |
|---|---|---|
| Context window | 1,048,576 tokens | Hy4 answered every question over a 200,000-token log in our test |
| Parameters | Not published | Hy4 Preview has 770B in total, 49B active |
| Maximum output | 65,536 tokens | Thinking tokens are part of this limit |
| Input | Text and images | Hy4 answered all 3 image questions in our test |
| Output | Text only | - |
| Reasoning | On by default | Levels: none, low, medium, high; none turns it off |
| Tool calling | Supported | All 3 agent tasks with tools passed in our test |
| JSON output | json_object and json_schema | - |
| API format | OpenAI-compatible | Change the base URL, and your OpenAI SDK code works |
What's new compared to Hy4 Preview
The final model got much more training than the preview. Hy4 Preview worked with text only, while Hy4 reads images, including small details on charts.
Unlike the preview, Hy4 can use a computer, through the command line and through graphical interfaces. Its training included programs such as Blender and CAD tools and tasks that use several apps one after another.
It invents facts less often. In Tencent's internal tests, its hallucination rate fell from 15.76% to 5.45%, and errors from guessing fell from 23.1% to 5.6%.
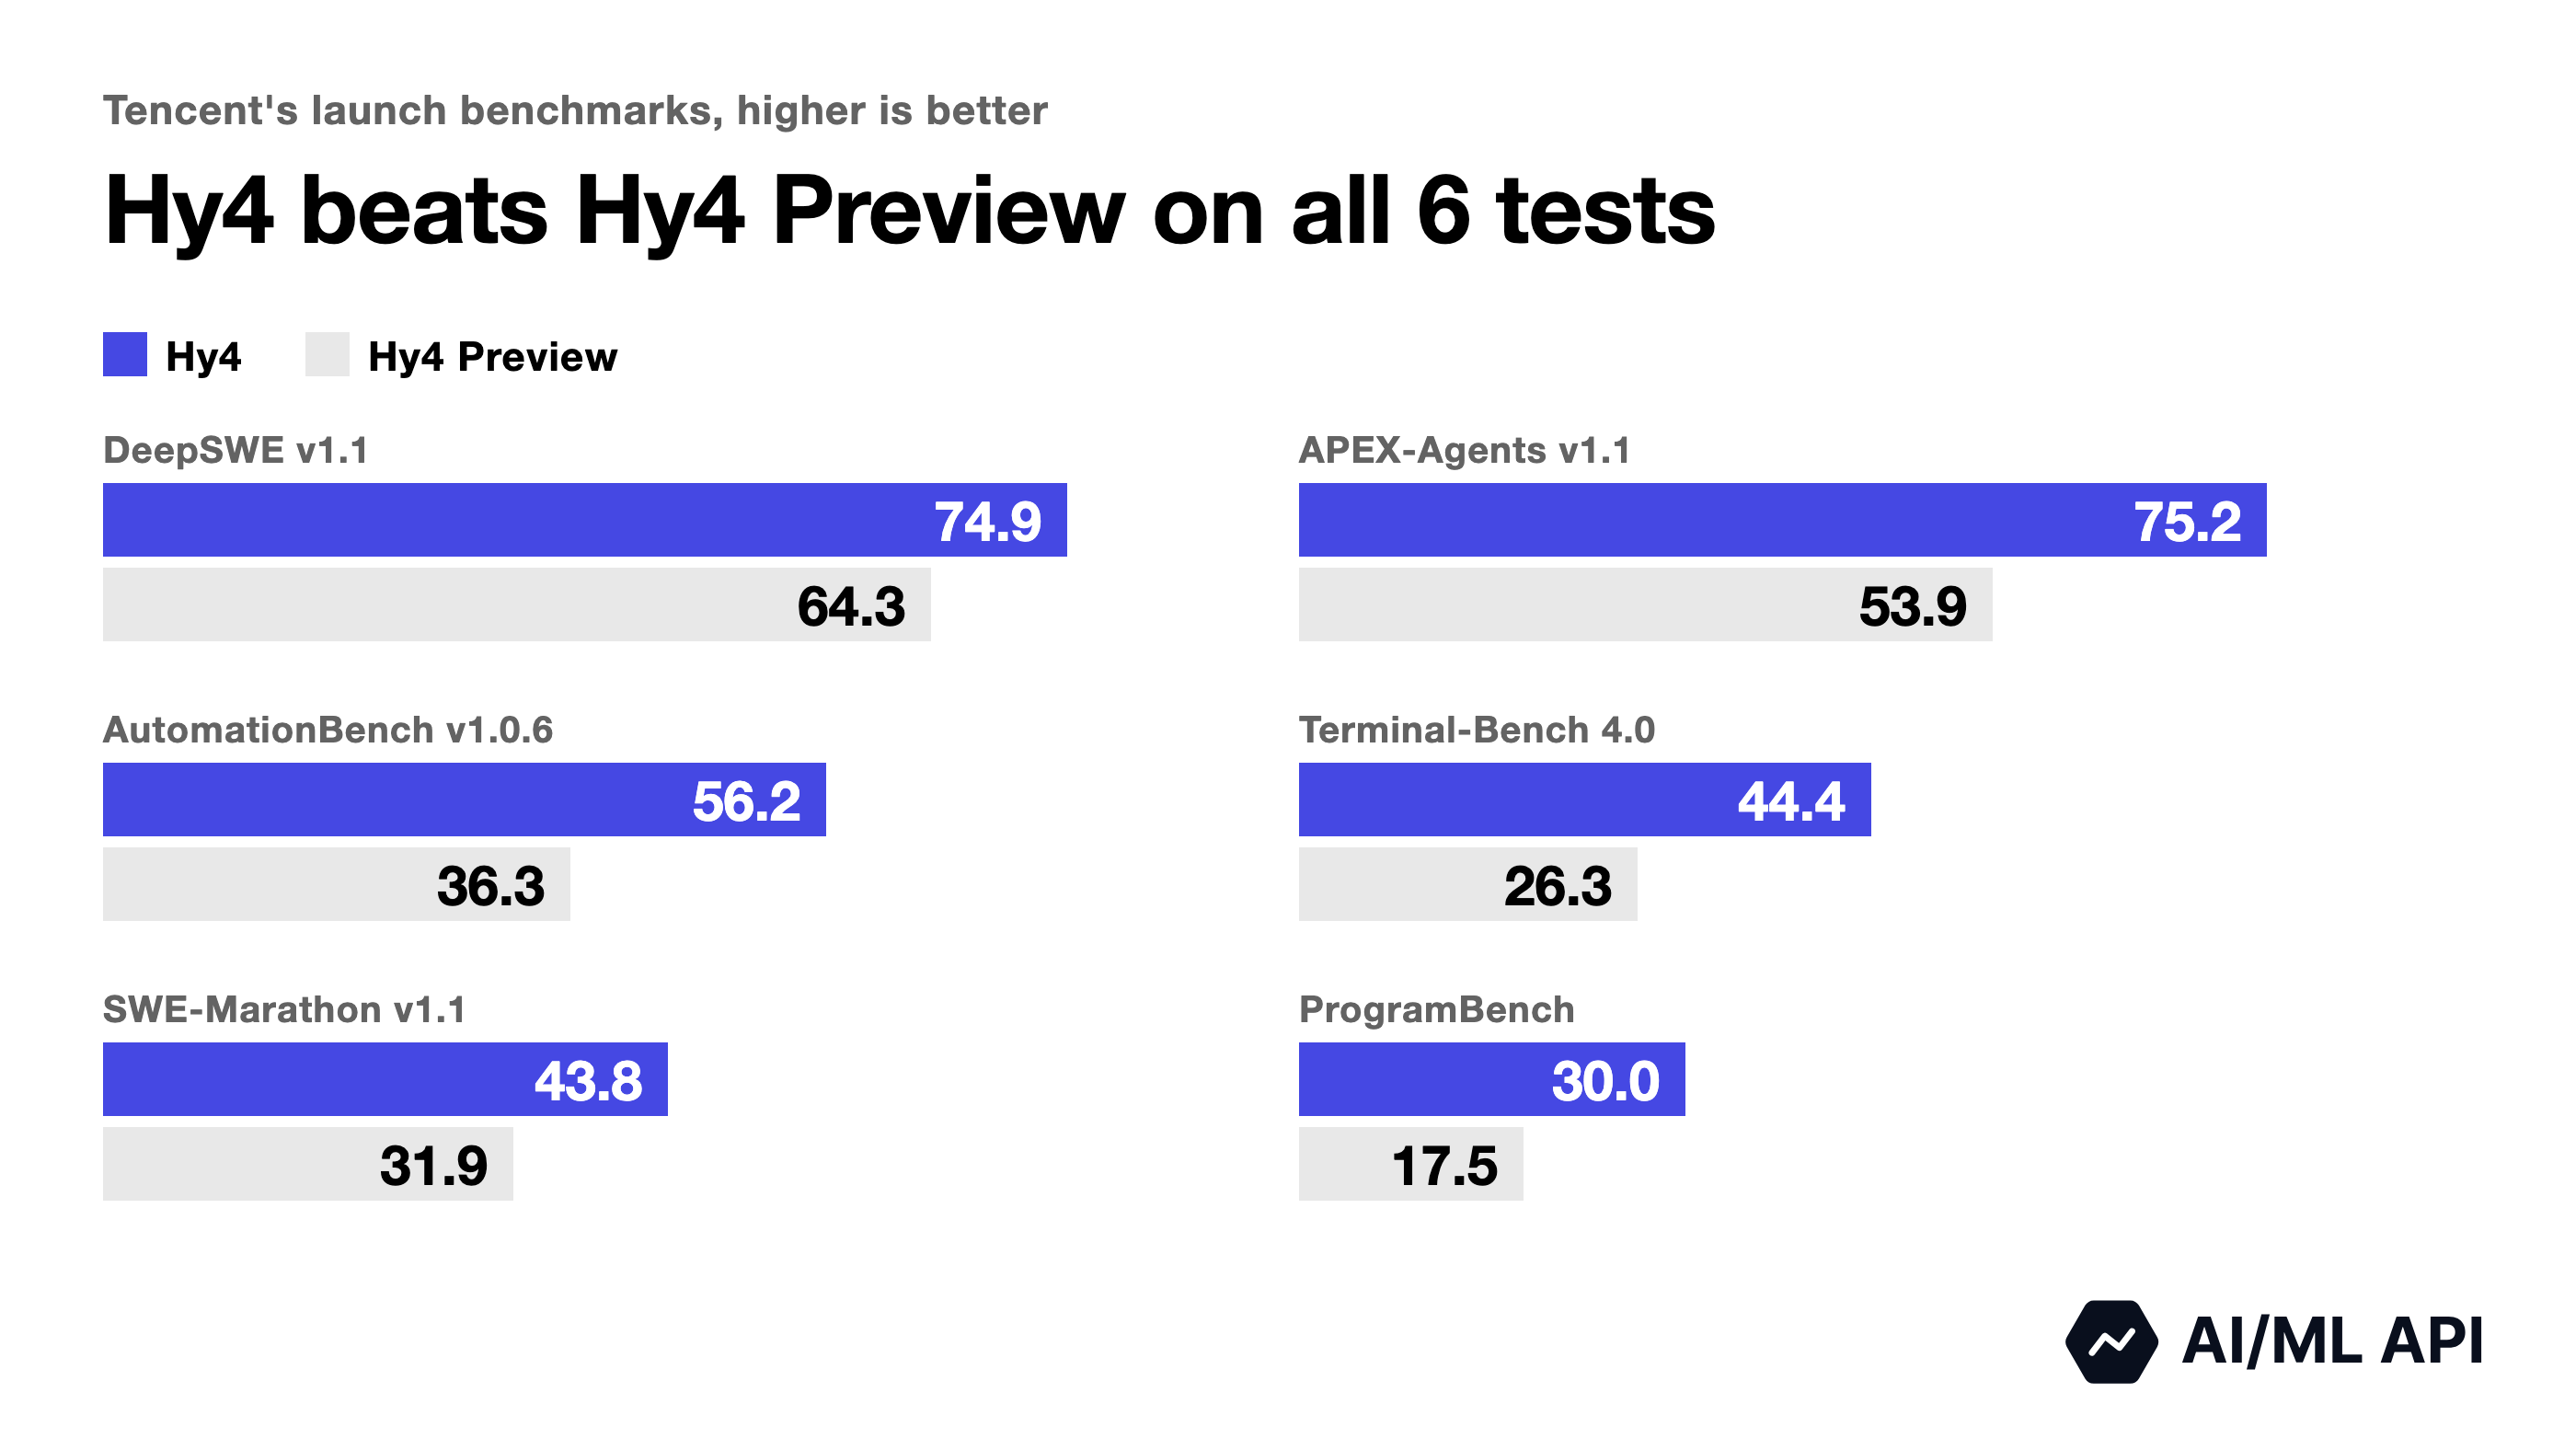
On the launch benchmarks, Hy4 scores higher than the preview on every test where both have scores. Of the six tests below, the biggest jumps are on APEX-Agents (21.3 points) and AutomationBench (19.9 points).
On AI/ML API, Hy4 costs the same as Hy4 Preview.
Hy4 benchmark results
On Tencent's launch benchmarks, Hy4 beats DeepSeek V4.1 Flash and GLM 5.3 on most tests. Kimi K3.1 Pro and Claude Opus 5.5 score higher than Hy4 on most tests. On Terminal-Bench 4.0, both score above 65, while Hy4 scores 44.4.
Tencent's benchmarks for Hy4
| Benchmark | Hy4 | DeepSeek V4.1 Flash | GLM 5.3 | Kimi K3.1 Pro | GPT-6.1 Sol | Claude Opus 5.5 |
|---|---|---|---|---|---|---|
| DeepSWE v1.1 (changes in real repositories) | 74.9 | 77.0 | 66.9 | 75.5 | 75.2 | 74.2 |
| SWE-Marathon v1.1 (coding) | 43.8 | 46.3* | 42.5 | 51.7 | 42.5 | 46.3 |
| ProgramBench (coding) | 30.0 | 29.1 | 19.0 | 31.5 | 46.0 | 65.0 |
| Terminal-Bench 4.0 (terminal tasks) | 44.4 | 42.3 | 42.9* | 65.7 | 55.9 | 66.4 |
| APEX-Agents v1.1 (agent work tasks) | 75.2 | 72.1 | 64.3* | 67.2 | 60.0 | 73.5 |
| Agents' Last Exam v1.1 (professional tasks) | 41.0 | 35.3 | 26.2 | 43.4 | 40.2 | 43.4 |
| AutomationBench v1.0.6 (business workflows) | 56.2 | 60.5 | 48.2 | 65.6* | 51.4* | 58.8* |
| HLE-Full with tools (expert questions) | 59.1 | 57.1* | 62.5 | 70.0 | 60.6* | 67.7 |
| OSWorld 2.1 (computer use) | 78.9 | 68.4* | - | 79.6 | 75.2* | 81.8 |
| MMMU-Pro (questions about images) | 78.6 | 76.7* | - | 84.1 | 84.9* | 88.2* |
* Tencent's own run. Where Tencent shows two scores, we use the one the model's developer published. Tencent tested DeepSeek-V4.1-Flash-1017. On AI/ML API, that name points to deepseek/deepseek-v4.1-flash.
Hy4 has the top score on APEX-Agents and beats Claude Opus 5.5 on DeepSWE, but scores less than half of Opus on ProgramBench, 30.0 against 65.0.
All scores here come from Tencent's launch post. 20 of the 34 tests in its full table are internal, and no independent lab has tested Hy4 yet: Artificial Analysis lists only Hy3 models so far.
Hy4 vs DeepSeek V4.1 Flash
Hy4 beats DeepSeek V4.1 Flash on 7 of the 10 tests in the table above, but on a coding task in our test, DeepSeek was about 10 times faster and 10 times cheaper.
| Hy4 | DeepSeek V4.1 Flash | |
|---|---|---|
| Tests won in the table above, out of 10 | 7 | 3 |
| DeepSWE v1.1 | 74.9 | 77.0 |
| OSWorld 2.1 | 78.9 | 68.4* |
| Maximum output | 65,536 tokens | 384K tokens |
| AI/ML API price per 1M tokens, input / output | $0.882 / $2.646 | $0.30 / $1.20 |
| Our test: runs passed | 23/23 | 46/46 |
| Our test: time per coding task | 264 s | 25 s |
| Our test: cost per coding task | $0.049 | $0.0049 |
DeepSeek V4.1 Flash is also ahead on SWE-Marathon and AutomationBench.
Hy4 vs GLM 5.3
Hy4 beats GLM 5.3 on 7 of the 8 tests in the table where both have scores, and in our test it was faster and cheaper on every task type both models finished.
| Hy4 | GLM 5.3 | |
|---|---|---|
| Tests won in the table above, out of 8 | 7 | 1 |
| Agents' Last Exam v1.1 | 41.0 | 26.2 |
| HLE-Full with tools | 59.1 | 62.5 |
| Image input | Yes | No, text only |
| AI/ML API price per 1M tokens, input / output | $0.882 / $2.646 | $1.40 / $4.40 |
| Our test: runs passed | 23/23 | 17/20 |
| Our test: time per coding task | 264 s | 298 s |
| Our test: cost per coding task | $0.049 | $0.056 |
GLM 5.3 takes text only, so all 3 image questions in our test returned an error. For screenshots or charts, use Hy4 or GLM 5.3 Flash, which reads images.
Our Hy4 benchmark: Hy4 vs Claude Opus 5.5, GLM 5.3 and DeepSeek V4.1 Flash
Hy4 passed all 23 of its runs, but it was slow on code: a coding task took a median of 4.4 minutes.
How we tested
We ran the same kind of test as in our MiniMax M3.1 Flash review, on 4 models through AI/ML API.
| What we asked | Tasks | How we checked |
|---|---|---|
| Write code | 8 | We ran tests the model didn't see |
| Build a 3D lighthouse scene in Three.js in one try | 1 | We opened the page and checked it for errors and by eye |
| Finish a task with several tool calls | 3 | We checked that the model called the right tools with the right data |
| Find facts in a very long log (200,000 tokens) | 2 | We compared the answer with the right one |
| Answer questions about images | 3 | We compared the answer with the right one |
| Answer questions about things that don't exist | 10 | We checked if the model made up an answer or said it didn't know |
Each model ran at its default reasoning setting. Hy4 had 23 runs, Claude Opus 5.5 had 45, GLM 5.3 had 20 and DeepSeek V4.1 Flash had 46, because we cut the test from 3 runs per task to 1 partway through. These counts cover the coding, Three.js, tool, long-log and image tasks. We scored the 10 questions about things that don't exist separately. Times include network latency, and costs include reasoning tokens.
Results by task type
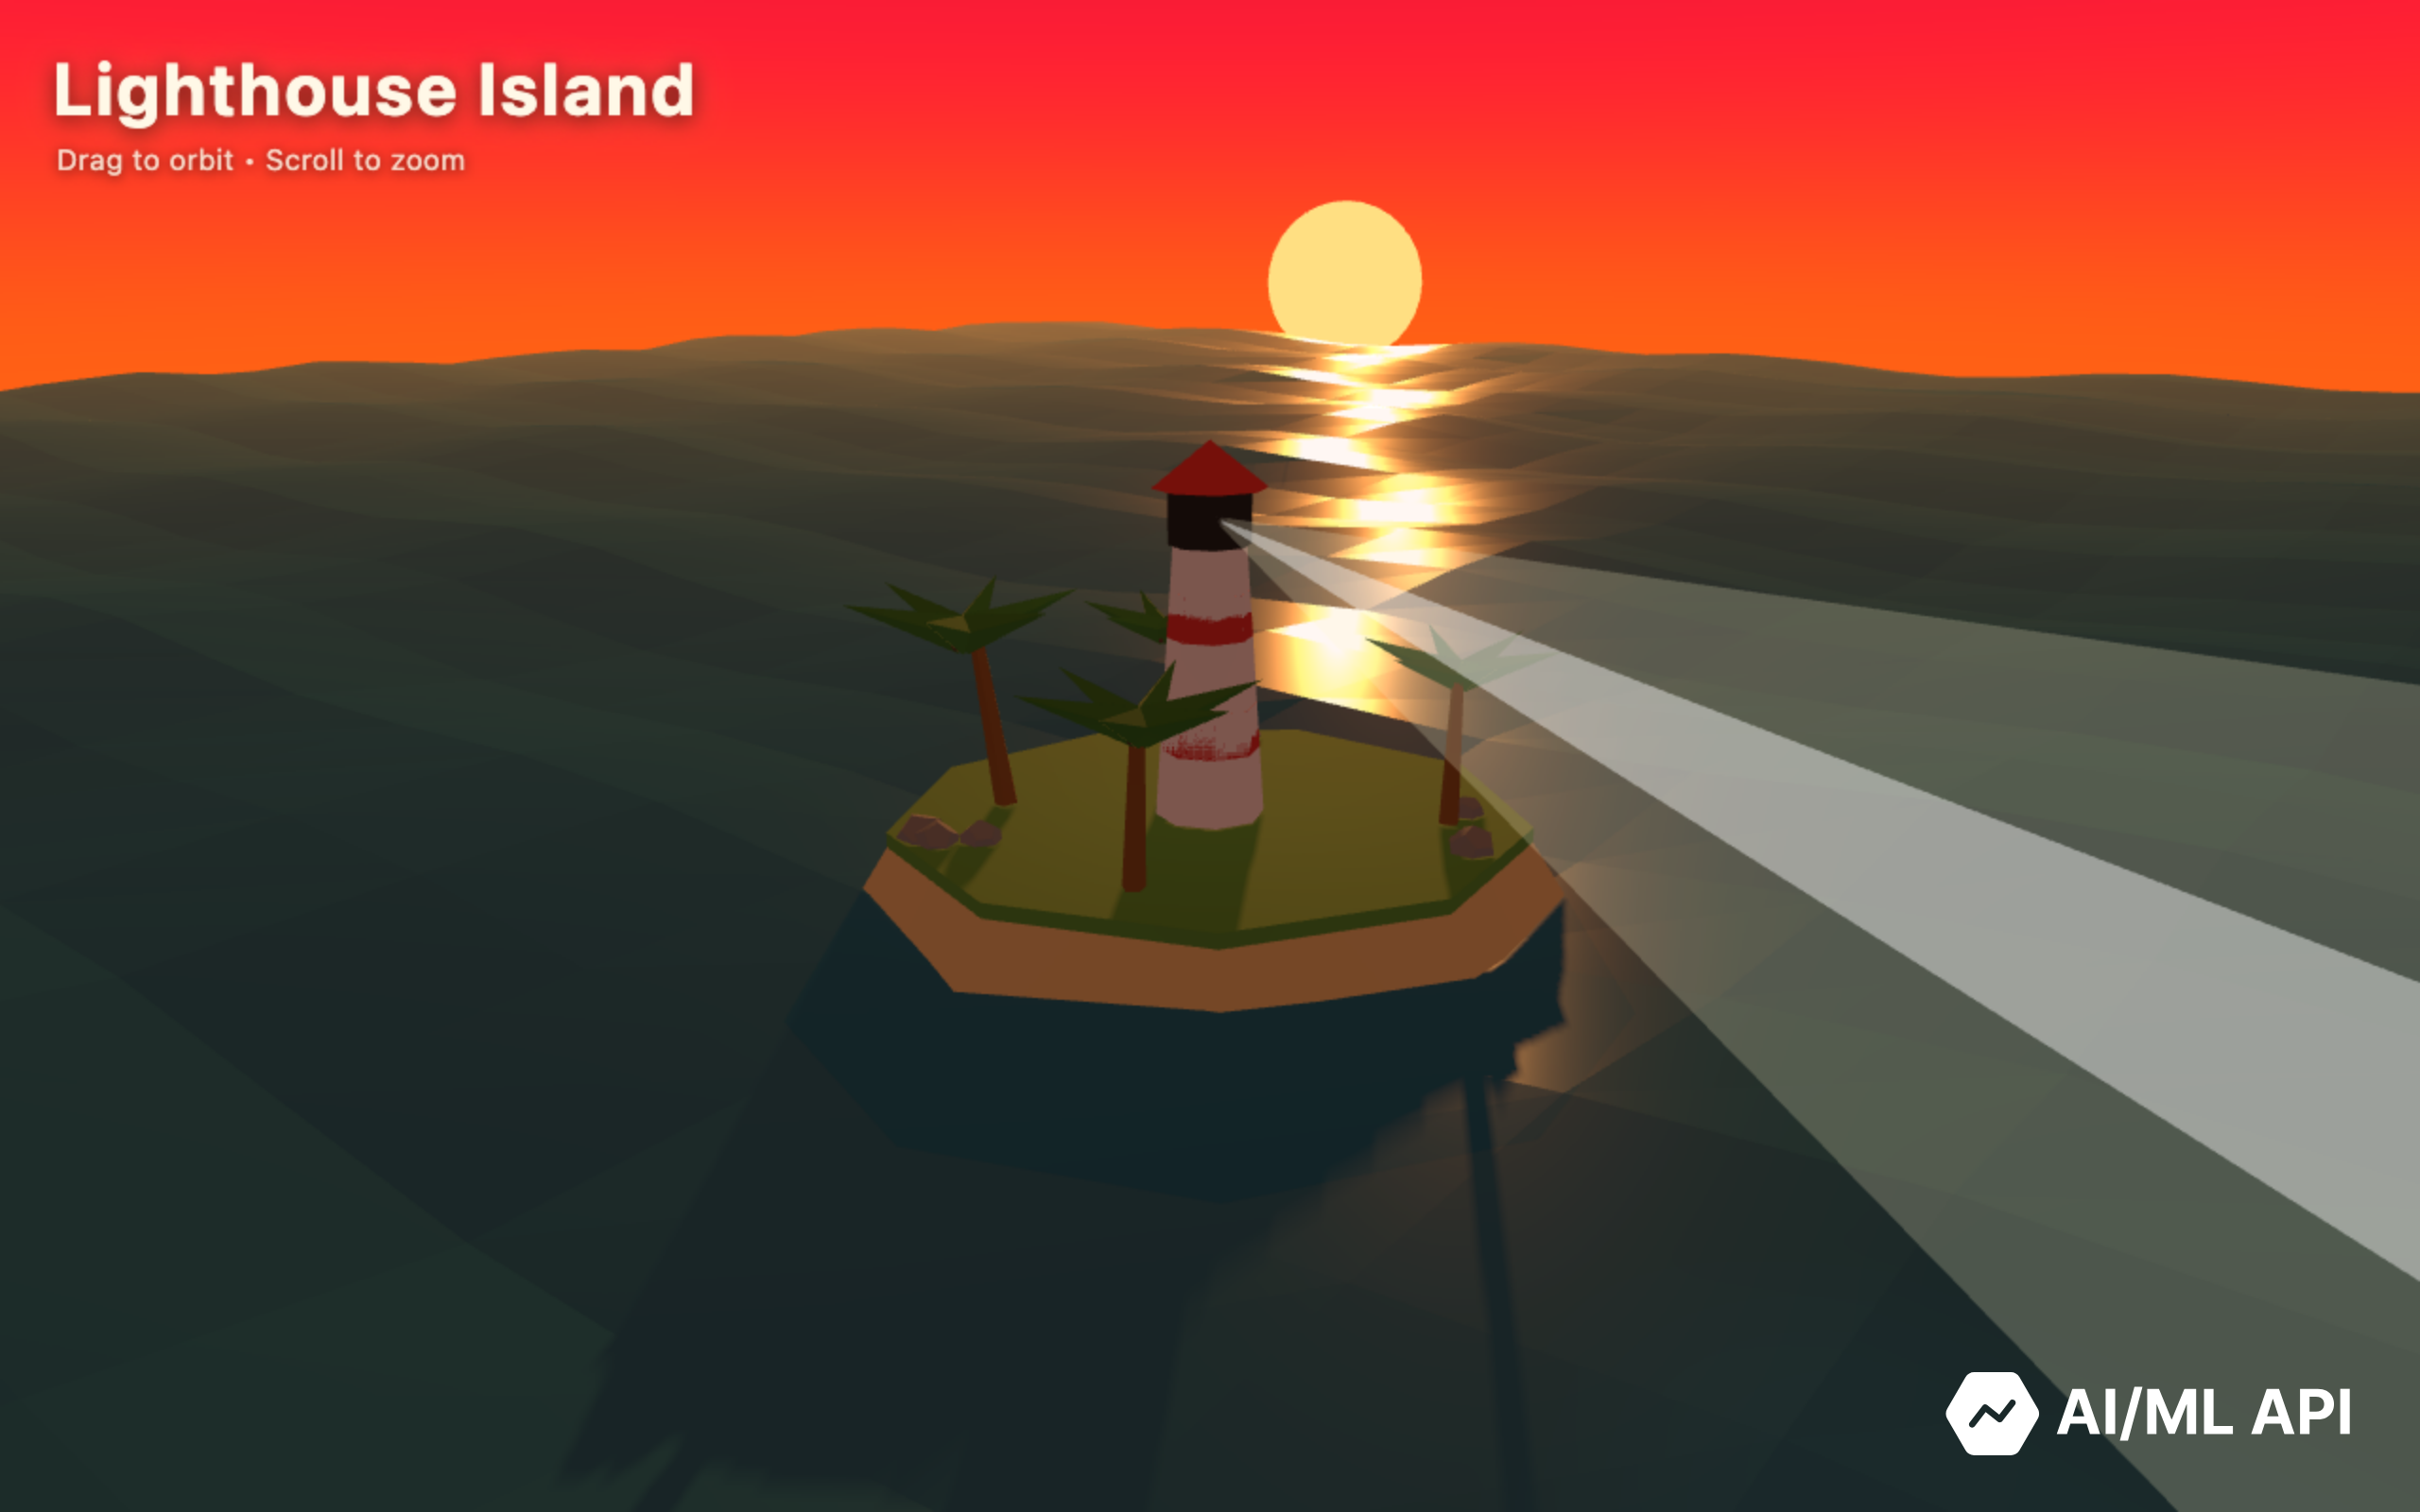
Hy4, Claude Opus 5.5 and DeepSeek V4.1 Flash passed every run. On the 10 questions about things that don't exist, no model made up an answer. Hy4 said it didn't know on 8 of them. On the other 2, it spent the whole 8,192-token limit on reasoning and returned no answer. GLM 5.3 never finished the Three.js scene, so we didn't count that run. Hy4 built the lighthouse scene in all 3 runs.
On code, Hy4 wrote about 18,000 reasoning tokens per task on average, five times more than DeepSeek V4.1 Flash, at about half the speed: 88 tokens per second against 165. The median coding task came to about 23,000 tokens, which is why it took 4.4 minutes. Claude Opus 5.5 decides by itself how much to think, and on these tasks it used no reasoning tokens and wrote about 1,000 tokens per answer, so it finished a task in about 10 seconds. In a separate check, we sent Hy4 the same request every 5 minutes for 25 minutes, and its speed stayed at 84 to 91 tokens per second.
How reasoning effort changes Hy4's speed and cost
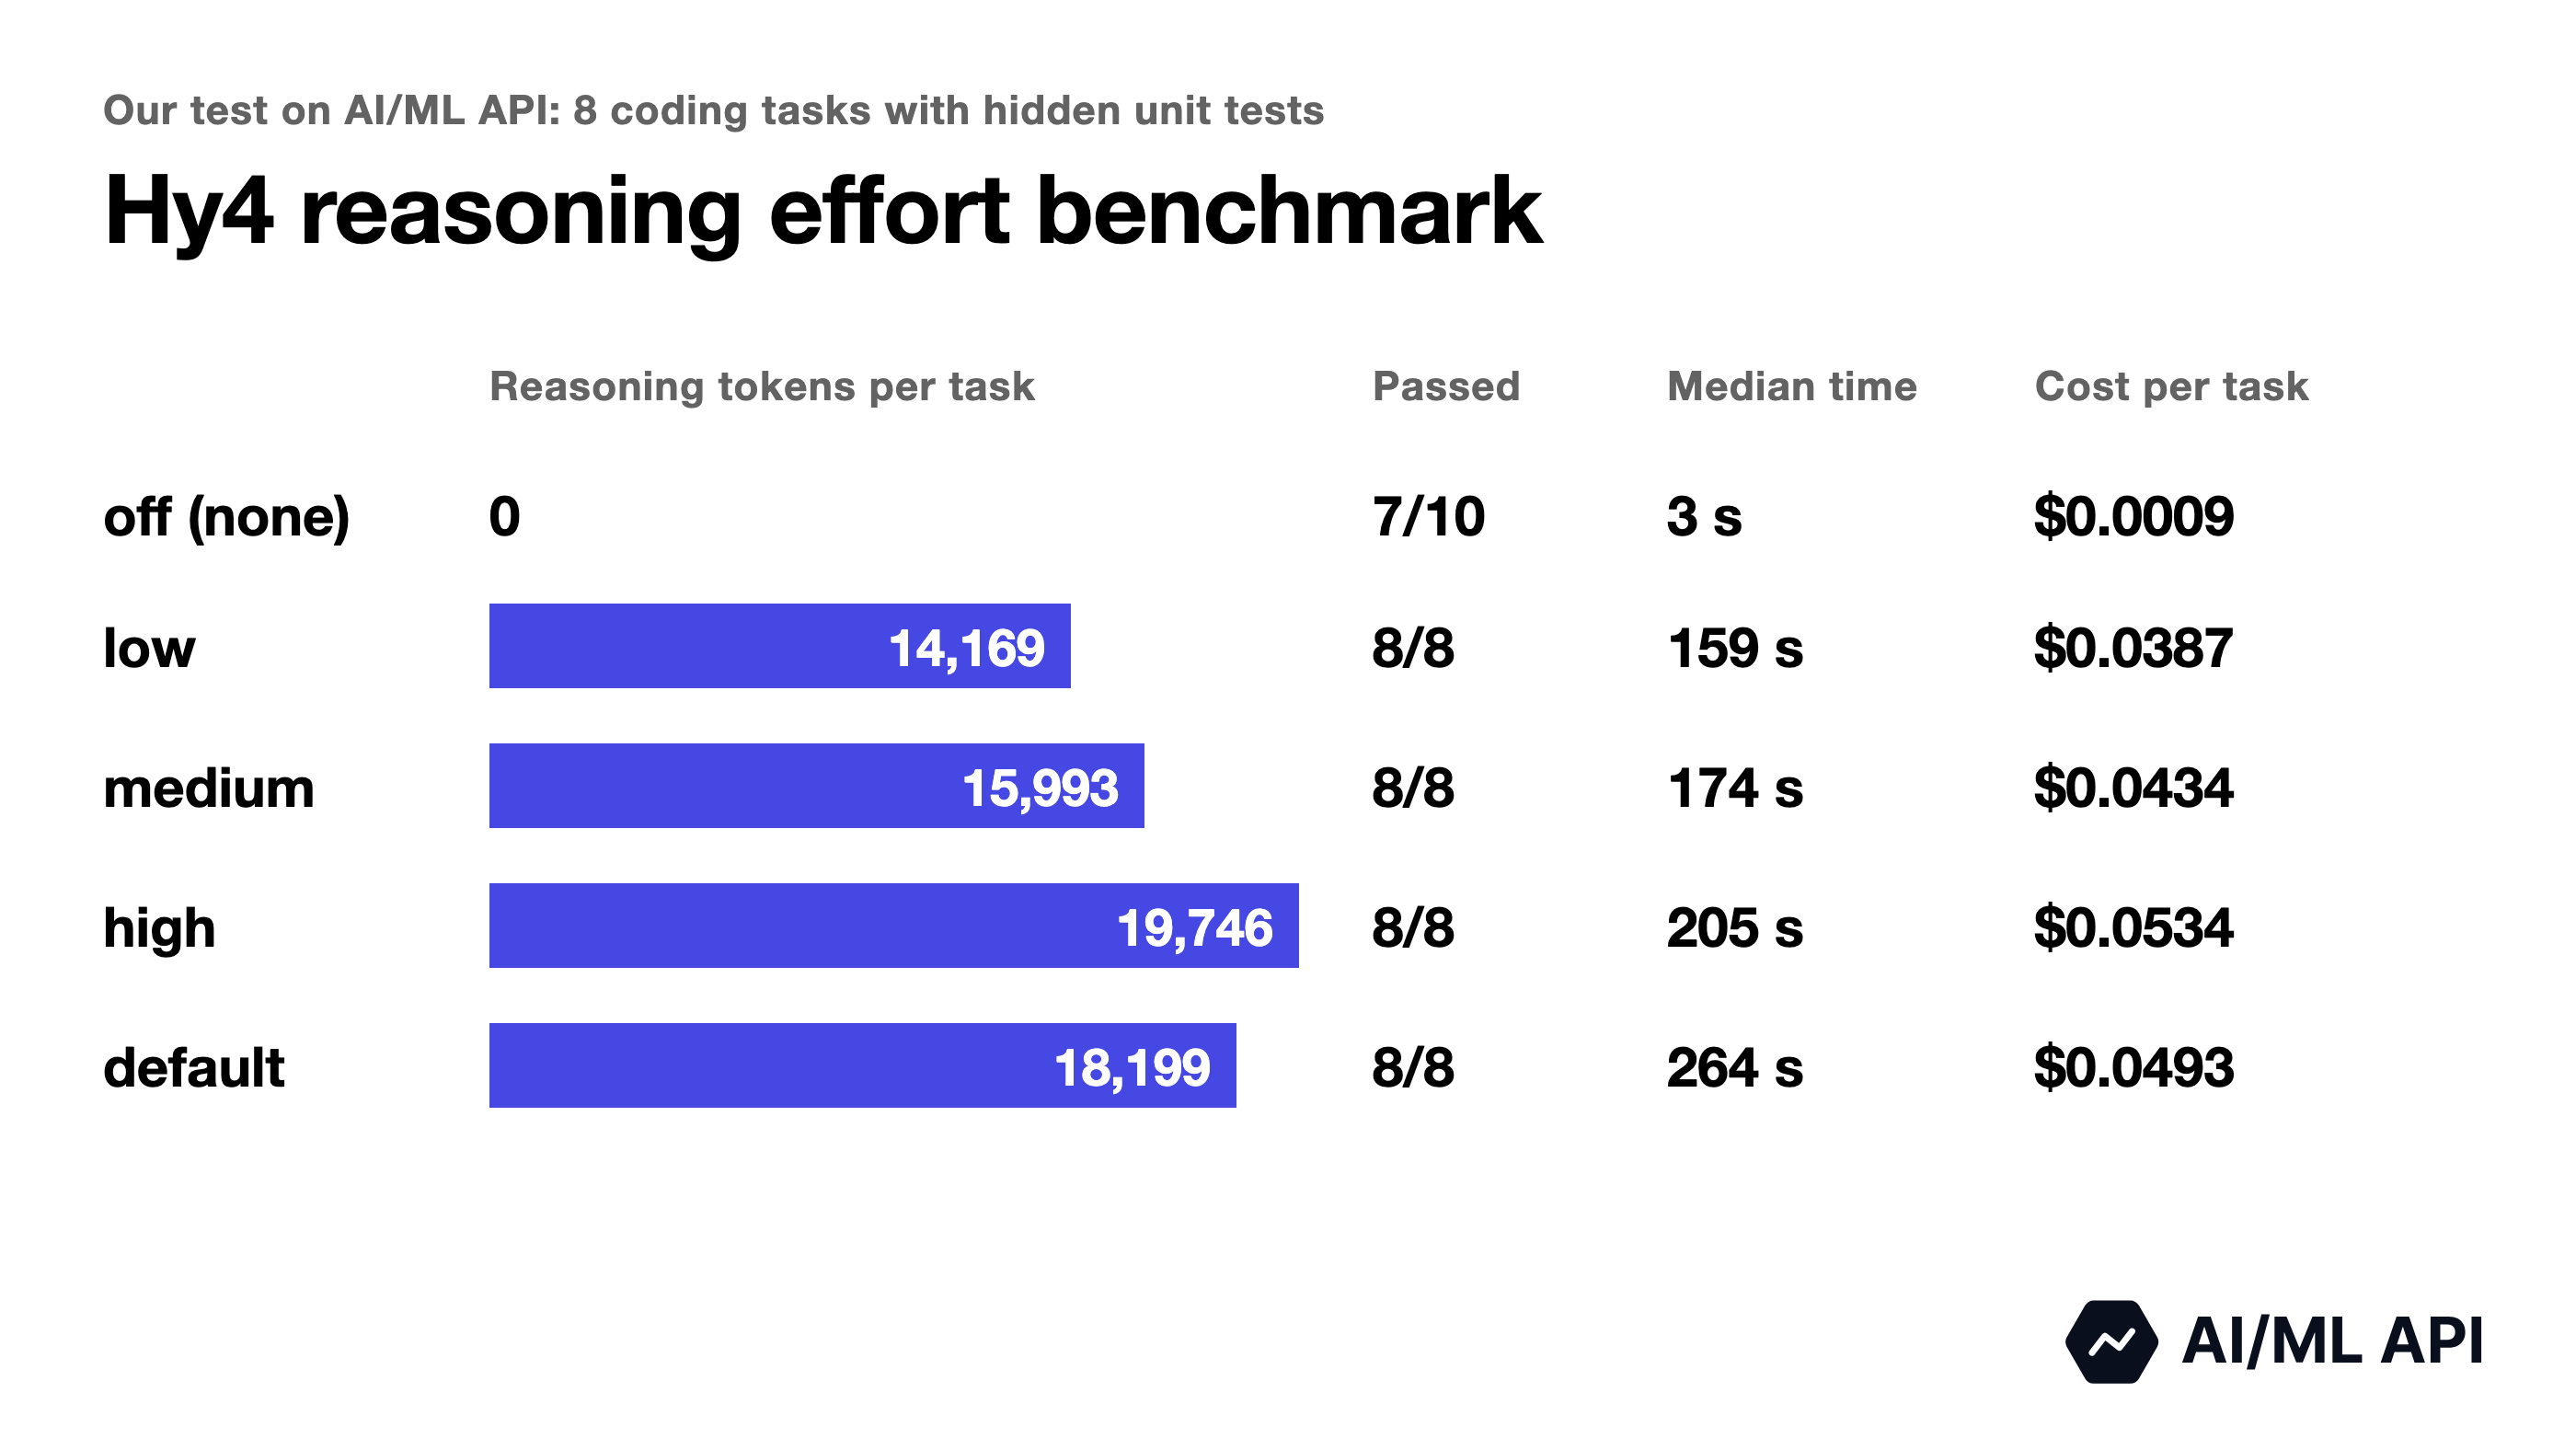
For coding tasks, start with low: in our test it passed all 8 tasks, as often as the default, with 22% fewer reasoning tokens and for $0.039 per task against $0.049. With thinking off (none), Hy4 answered in 3 seconds for less than a tenth of a cent, but failed 3 of 10 runs. A difference of 1 or 2 runs is within chance, since each setting had 8 to 10 runs.
Where it failed
At the default setting, Hy4 passed all 23 runs. All 3 failures came with reasoning turned off.
In a duration parser, it removed all spaces before reading the text, so it accepted "1 h" as 3,600 seconds, although the task said each number must be followed directly by its unit. In 2 runs of a slug function, it cut the text at the length limit and then always went back to the last hyphen, so "abc def ghi" with a limit of 7 became "abc" instead of "abc-def".
Hy4 pricing on AI/ML API
On AI/ML API, Hy4 costs $0.882 per million input tokens and $2.646 per million output tokens. Reasoning tokens are billed as output, and cached input costs $0.044 per million.
| Average cost per task on AI/ML API, from our test | Hy4 | Claude Opus 5.5 | GLM 5.3 | DeepSeek V4.1 Flash |
|---|---|---|---|---|
| Coding task | $0.0493 | $0.0205 | $0.0557 | $0.0049 |
| Three.js scene | $0.0376 | $0.2386 | - | $0.0368 |
| Agent task with tools | $0.0041 | $0.0356 | $0.0055 | $0.0011 |
| Question over a 200,000-token log | $0.0703 | $1.0983 | $0.2078 | $0.0120 |
| Question about an image | $0.0013 | $0.0070 | - | $0.0005 |
| Median cost per task, all groups | $0.0194 | $0.0307 | $0.0536 | $0.0016 |
Across all task groups, a median task cost $0.019 on Hy4, against $0.031 on Claude Opus 5.5 and $0.054 on GLM 5.3. On the long-log questions, AI/ML API billed 67% of Hy4's prompt tokens at the cached rate, so a question cost $0.07. We didn't turn on caching for Claude Opus 5.5, so a question there cost the full $1.10. Without the cache, the first question over a 200,000-token log costs about $0.18 on Hy4. A coding task cost more on Hy4, $0.049 against $0.021 on Opus, because of its long reasoning.
How to use the Hy4 API
You need an AI/ML API key and Python 3.9 or later with the OpenAI SDK (pip install openai). Create a key on the API keys page and save it in the AIMLAPI_KEY environment variable. Then point the OpenAI client at our base URL:
import os
from openai import OpenAI

client = OpenAI(
    base_url="https://api.aimlapi.com/v1",
    api_key=os.environ["AIMLAPI_KEY"],
)

response = client.chat.completions.create(
    model="tencent/hy4",
    reasoning_effort="low",
    messages=[
        {"role": "user", "content": "Write a Python function that checks if a string is a valid IPv4 address."}
    ],
)

print(response.choices[0].message.content)
If you leave out reasoning_effort, Hy4 uses its default. In reasoning_effort, it accepts none, low and high, and none turns thinking off. For medium, pass extra_body={"reasoning": {"effort": "medium"}}. For JSON output, add response_format={"type": "json_object"}. To send an image, add it to the message as an image_url part, the same way as for OpenAI models.
Every parameter Hy4 accepts is listed in our Hy4 API docs. To try the model without code, open it in the AI/ML API Playground.
What are Hy4's pros and cons?
Pros:
- Passed all 23 runs in our test
- The top APEX-Agents score of the 6 models in Tencent's table, 75.2
- A median task cost $0.019, less than on Claude Opus 5.5 and GLM 5.3
- 1M-token context and image input
Cons:
- A coding task took a median 4.4 minutes at the default setting, against 25 seconds on DeepSeek V4.1 Flash
- With thinking turned off, it failed 3 of 10 coding runs
- Behind Kimi K3.1 Pro and Claude Opus 5.5 on most of Tencent's tests, with 44.4 on Terminal-Bench 4.0 against their 65.7 and 66.4
- 20 of Tencent's 34 tests are internal, and no independent lab has scored Hy4 yet
- No published weights yet, and no local or self-hosted run
- On 2 of 10 questions about things that don't exist, it spent the whole 8,192-token limit on reasoning and returned no answer
Who should use Hy4?
Hy4 fits agent work across documents, images and other apps: it has the top APEX-Agents score in Tencent's table and passed every agent and image run in our test. At reasoning_effort low, Hy4 passed all 8 coding tasks in our test for $0.039 each.
Pick DeepSeek V4.1 Flash when response time or price matters, and Kimi K3.1 Pro or Claude Opus 5.5 for hard terminal and coding tasks. To try it, create an AI/ML API key and call tencent/hy4.
FAQ
Is Hy4 free?
No. AI/ML API bills Hy4 per token, and reasoning tokens count as output. All 67 Hy4 requests in our test, including the reasoning-effort runs, cost $2.16 together.
Is Hy4 better than Claude Opus 5.5 for coding?
Not overall. On the 10 Tencent launch benchmarks in this review, Claude Opus 5.5 is ahead on 8, with the biggest leads on ProgramBench and Terminal-Bench 4.0. Hy4 is ahead on DeepSWE, 74.9 against 74.2. On AI/ML API, Claude Opus 5.5 costs $4 per million input tokens and $20 per million output tokens, about 4.5 and 7.6 times more than Hy4. In our test, both passed every run, but Opus answered coding tasks without visible reasoning, so it was faster and even cheaper per coding task: 10 seconds and $0.021, against 4.4 minutes and $0.049 on Hy4. For more models, see our best LLMs for coding.
Is Hy4 better than DeepSeek V4.1 Flash?
On Tencent's benchmarks, mostly yes: Hy4 beats DeepSeek V4.1 Flash on 7 of the 10 tests in this review, including APEX-Agents and OSWorld 2.1. For code, DeepSeek was the better pick in our test, at 25 seconds and $0.0049 per task against 4.4 minutes and $0.049 on Hy4.
Can you run Hy4 locally?
Not yet. Hy4 isn't open source yet: Tencent plans to publish the weights and is working with the vLLM and SGLang teams on support. Tencent has already published the weights of Hy4 Preview and Hy3 on Hugging Face. The hardware the final Hy4 needs is unknown, because Tencent hasn't published its parameter count.
How do I get a Hy4 API key?
Sign up on AI/ML API and create a key on the API keys page. The same key works for Hy4 and every other model in our catalog.
Key Takeaways
- Tencent Hy4, released on November 4, 2026, is the final version of Hy4 Preview and reads images, which the preview couldn't do.
- On Tencent's launch benchmarks, it beats DeepSeek V4.1 Flash and GLM 5.3 on most tests, but Kimi K3.1 Pro and Claude Opus 5.5 still score higher on most of them.
- 20 of Tencent's 34 tests are internal, and no independent lab has tested the final Hy4 yet.
- In our test on AI/ML API, Hy4 passed all 23 runs, but a coding task took a median of 4.4 minutes at the default setting.
- Hy4 costs $0.882 per million input tokens and $2.646 per million output tokens on AI/ML API: create a key and call
tencent/hy4.