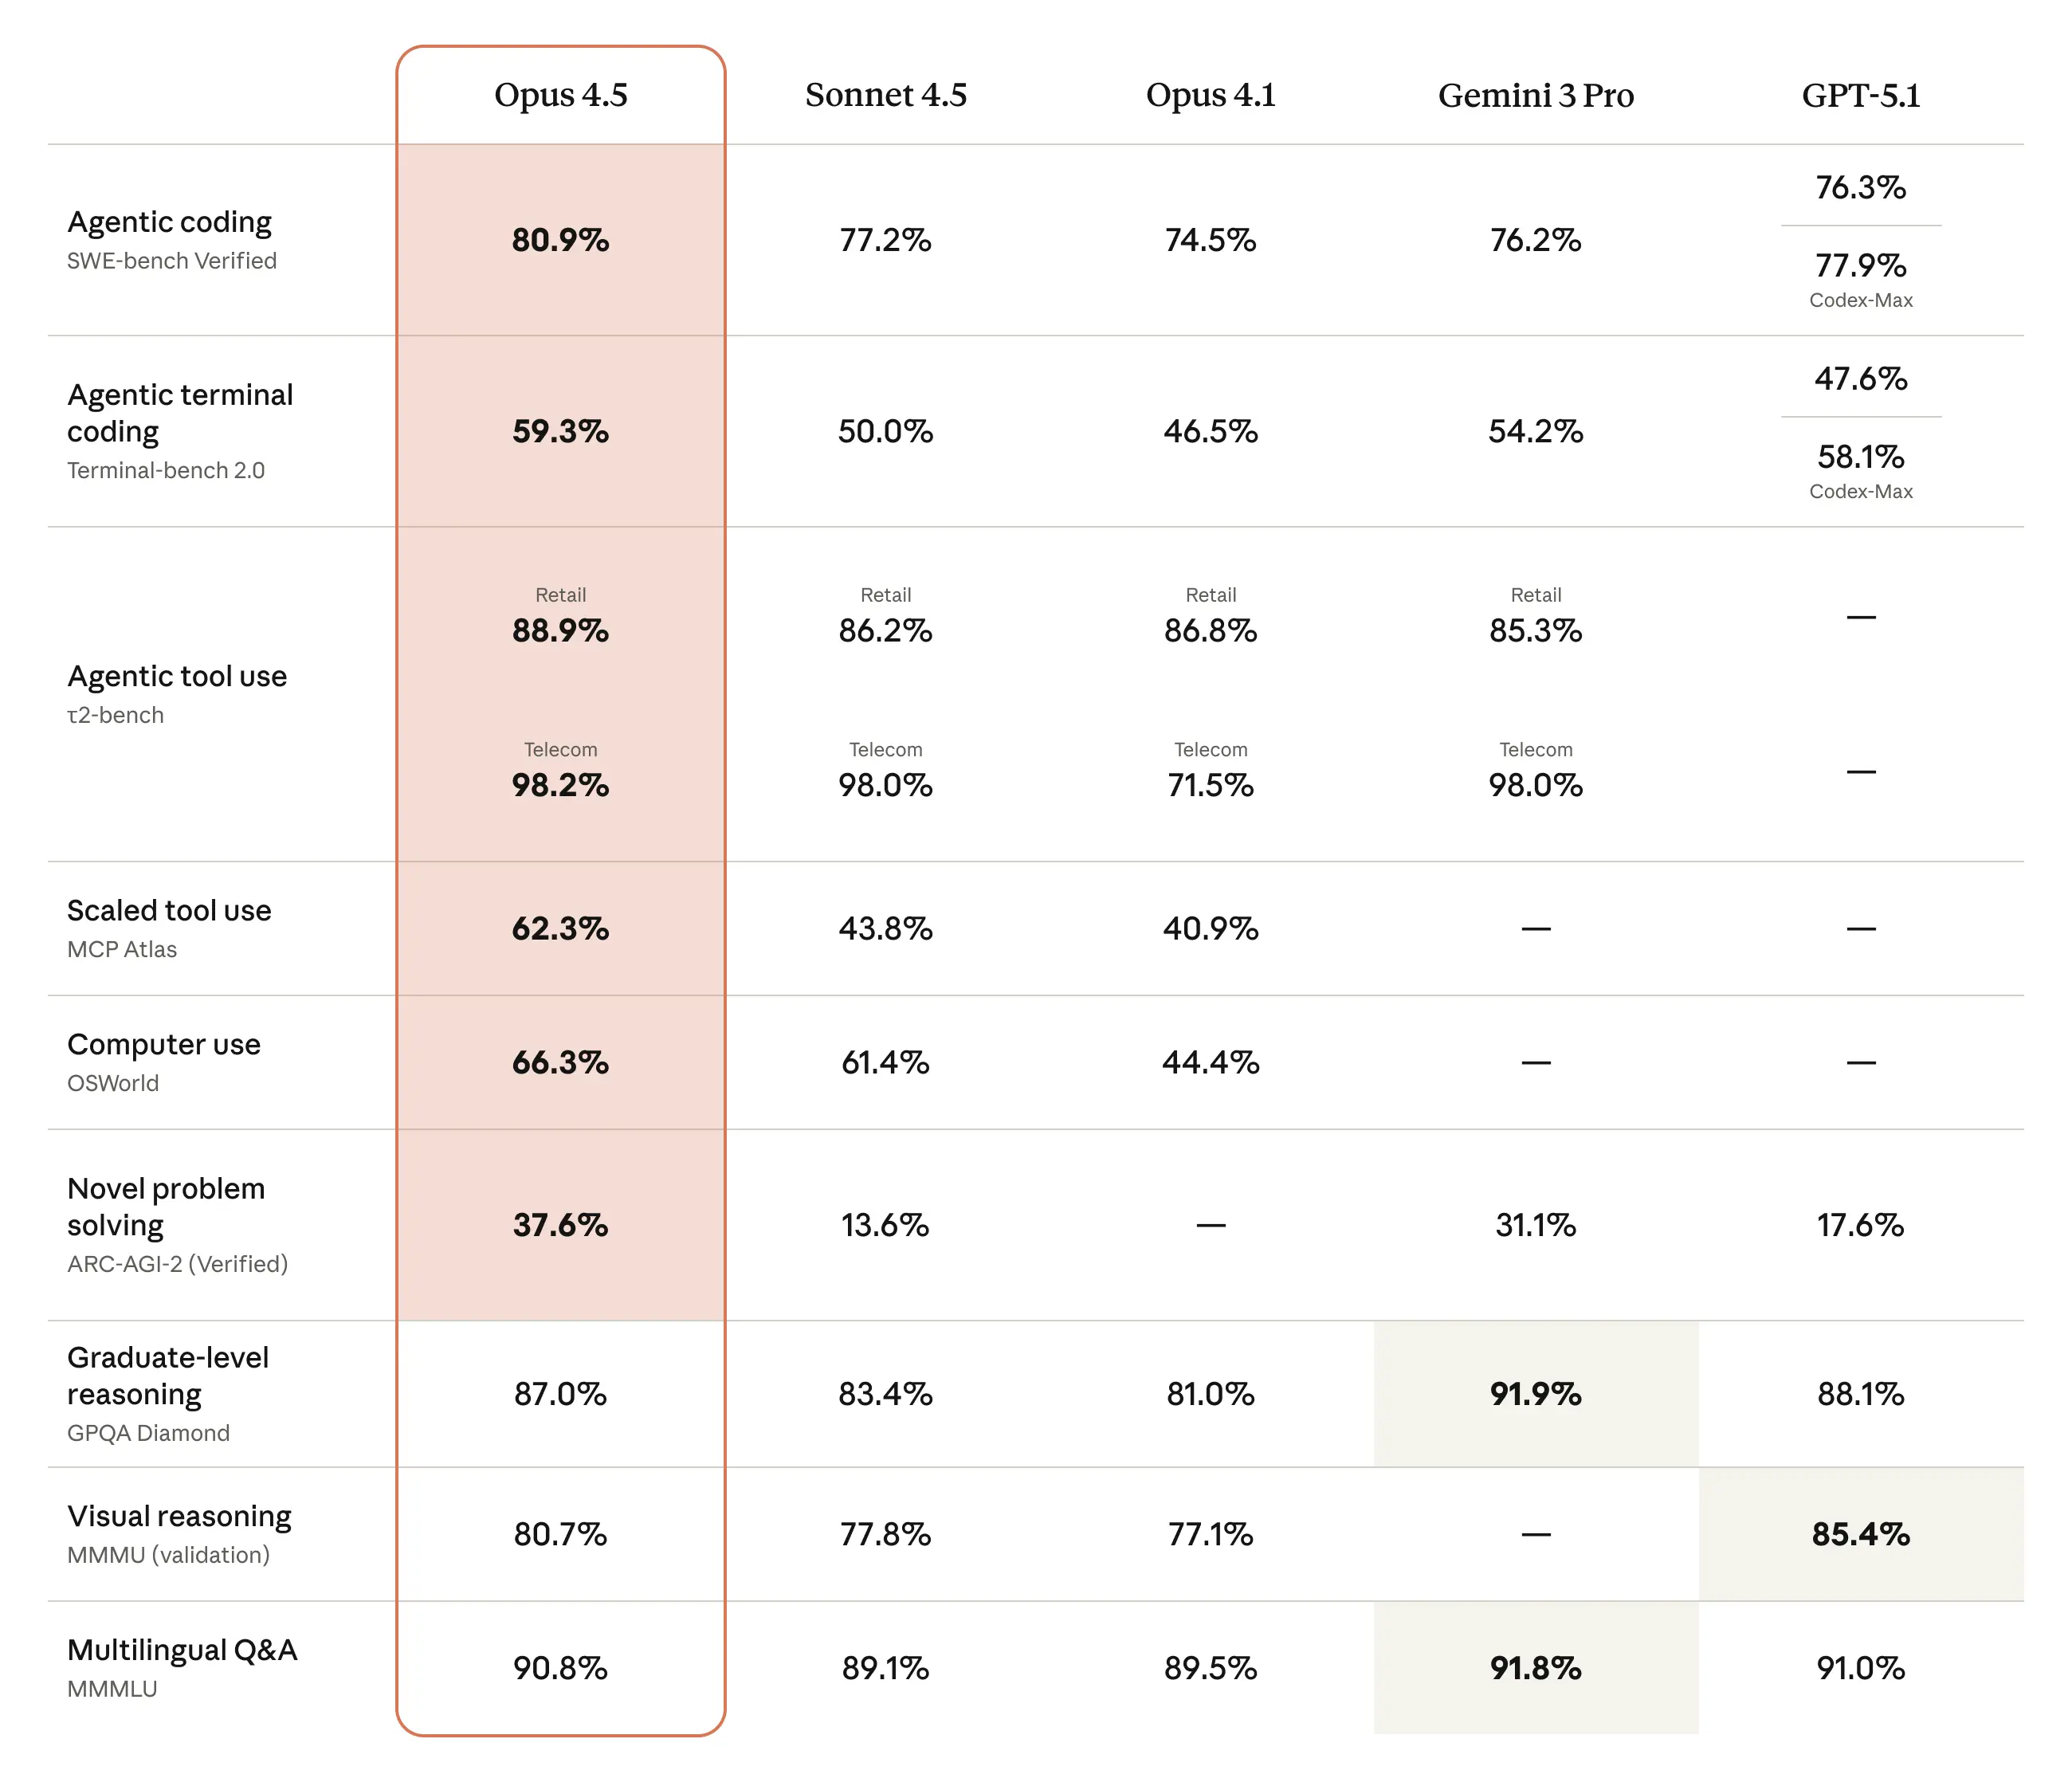
Anthropic positions Claude Opus 4.5 as its best model for coding, agents and computer use: state-of-the-art on tests of real-world software engineering, and leading across seven of eight programming languages. It handles ambiguity and reasons about tradeoffs without hand-holding, is effective at managing a team of subagents, and reaches similar or better outcomes on dramatically fewer tokens than its predecessors — at medium effort it matches Sonnet 4.5 while using 76% fewer output tokens. Served with a 200K context window.
Claude 4.5 Opus sets a new standard in AI performance, focusing on intelligence, efficiency, and practical utility. This model excels in complex tasks like coding, agentic operations, and deep research, while prioritizing robust safety and alignment.
Technical Specifications
Context Window: Supports up to 200K tokens, enabling handling of extensive inputs for long-form analysis and multi-step processes.
Multimodality: It can process various input types, including text, code, images, and documents. It excels at visual reasoning tasks like understanding charts and diagrams and extracting structured data from screenshots.
Output: The model generates text output.
Performance Benchmarks
Claude Opus 4.5 demonstrates leadership in key evaluations, outperforming predecessors and peers in efficiency and capability.
SWE-bench Verified (Software Engineering): Achieves state-of-the-art scores among frontier models, surpassing previous benchmarks with 4.3 percentage points improvement over Sonnet 4.5 at high effort.
Output Quality & Reasoning Performance
Users report markedly more natural, contextually rich responses with internal stepwise reflection improving answer correctness and detail. The model shows superior handling of complex instructions with balanced conversational tone and precision.
Key Features
Advanced Reasoning and Ambiguity Handling: Independently navigates tradeoffs, fixes multi-system bugs, and resolves complex issues without explicit guidance.
Creative Problem-Solving: Employs novel strategies in agentic scenarios, such as policy-compliant workarounds in restricted tasks.
Token-Efficient Processing: Matches or exceeds prior model performance using significantly fewer tokens, optimizing for cost and speed.
Robust Alignment and Safety: Features the lowest rates of concerning behaviors, including resistance to misuse and prompt injections, as validated by external audits.
Agentic Toolset: Supports context compaction, memory retention, and multi-agent coordination for extended, collaborative workflows.
Claude 4.5 Opus API Pricing
Input: $6.5 / MTok
Output: $32.5 / MTok
Use Cases
Software Engineering and Coding: Ideal for building detailed plans, debugging code, researching repositories, and executing multi-step implementations.
Agentic and Automation Tasks: Handles real-world interactions, such as acting as a virtual assistant for customer support or managing multi-turn processes across systems.
Deep Research and Analysis: Excels in synthesizing information from slides, spreadsheets, and web sources, supporting in-depth investigations and report generation.
Professional Evaluations: Simulates human-level performance in assessments like engineering interviews, aiding recruitment and training.
Collaborative Workflows: Coordinates subagents for complex projects, enabling scalable AI teams in enterprise settings.
Everyday Productivity: Assists with tasks involving desktop apps, browsers, and documents, streamlining workflows in business and creative fields.
Code Sample
Comparison with Other Models
vs Claude Sonnet 4.5: While Sonnet 4.5 excels in speed for lighter workloads, Opus 4.5's advanced reasoning and token efficiency make it better suited for deep research and multi-agent scenarios, achieving comparable results with up to 76% fewer tokens.
vs Gemini 3 Pro: Claude Opus 4.5 reclaims the edge in specialized benchmarks like software engineering and coding, outperforming Gemini 3 Pro on SWE-bench Verified and agentic tasks with enhanced reasoning depth.
vs Claude 3 Opus: Claude 4.5 Opus significantly advances on its predecessor by incorporating efficiency optimizations and enhanced agentic capabilities, achieving higher scores on SWE-bench and research tasks.
Uptime and performance
Uptime (24h): 100%
Uptime (7d): 100%
Availability (24h): 100%
Error rate (24h): 0%
Measured on the AI/ML API gateway across live traffic. Figures are medians unless stated. Last updated 2026-10-12.
Use cases
Software Engineering and Coding: Ideal for building detailed plans, debugging code, researching repositories, and executing multi-step implementations.
Agentic and Automation Tasks: Handles real-world interactions, such as acting as a virtual assistant for customer support or managing multi-turn processes across systems.
Deep Research and Analysis: Excels in synthesizing information from slides, spreadsheets, and web sources, supporting in-depth investigations and report generation.
Professional Evaluations: Simulates human-level performance in assessments like engineering interviews, aiding recruitment and training.
Collaborative Workflows: Coordinates subagents for complex projects, enabling scalable AI teams in enterprise settings.
Everyday Productivity: Assists with tasks involving desktop apps, browsers, and documents, streamlining workflows in business and creative fields.
How to use Claude Opus 4.5 API
Install any OpenAI-compatible SDK, point it at api.aimlapi.com/v1, and set the model to anthropic/claude-opus-4.5.