Llama Guard 3 Vision is a content safety classification model designed to safeguard Large Language Model (LLM) inputs and responses by detecting harmful multimodal prompts and text responses.
Designed for use cases requiring the detection of harmful content in multimodal inputs and responses, such as ensuring the safety of LLM applications.
Primarily optimized for the English language.
Llama Guard 3 Vision is a Llama-3.2-11B pretrained model, fine-tuned for content safety classification.
The model was trained using a hybrid dataset of human-generated and synthetically generated data. This includes human-created prompts paired with corresponding images, as well as benign and violating model responses generated using in-house Llama models and jailbreaking techniques.
The dataset includes a diverse range of prompt-image pairs, labeled by humans or the Llama 3.1 405B model, and covers all hazard categories defined by MLCommons. For image data, the vision encoder rescales images into 4 chunks, each of 560x560.
The dataset was carefully curated to encompass a diverse range of prompt-image pairs, spanning all hazard categories.
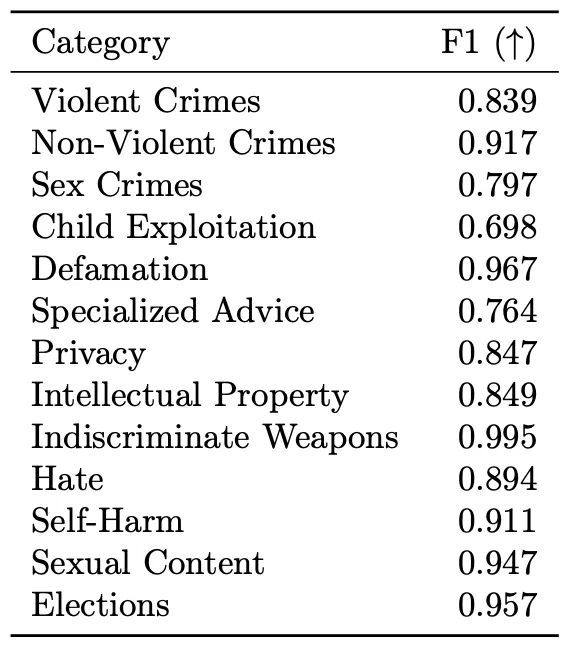
Llama Guard 3 Vision is evaluated on an internal test set following the MLCommons hazard taxonomy. Llama Guard 3 Vision demonstrates strong performance in categories such as Indiscriminate Weapons and Elections, achieving F1 scores exceeding 0.69 in every category.
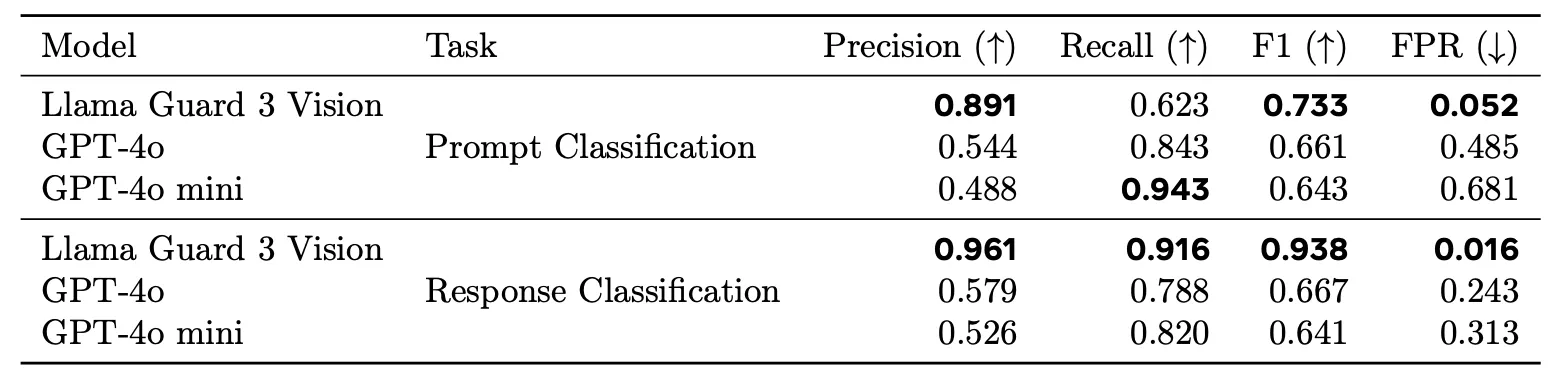
Llama Guard 3 Vision outperforms GPT-4o and GPT-4o mini, particularly in response classification, with higher F1 scores and significantly lower false positive rates. The ambiguity of combined text and image prompts makes prompt classification more challenging compared to response classification. Llama Guard 3 Vision relies more on the model response for classification, effectively minimizing prompt-based attacks.
UsageThe model is available on the AI/ML API platform as "Llama-Guard-3-11B-Vision-Turbo" .
Detailed API Documentation is available here.
Llama Guard 3 Vision is fine-tuned on Llama 3.2-vision, and its performance might be limited by its (pre-)training data. It is not meant to be used as an image safety classifier nor a text-only safety classifier.
Get Llama Guard 3 11B Vision Turbo API here.
OpenAI-compatible — swap the base URL and it works with your existing SDK.
| Type | Price |
|---|---|
| Input | |
| Output | |
| Model | Input | Output | Context | Best for |
|---|---|---|---|---|
Llama Guard 3 11B Vision Turbo This page | ||||
| Reasoning + agents | ||||
| Balanced coding + agents | ||||
| Long-context, multimodal & agentic workflows | ||||
| Reasoning + agents |
Yes, Llama Guard 3 11B Vision Turbo can stream responses as they are generated.
Llama Guard 3 11B Vision Turbo was built by Meta.
The model is available through the v1 endpoint.





