Qwen3-Next-80B-A3B Instruct is a next-generation large language model that balances enormous parameter scale with sparse activation to deliver fast, cost-efficient, and scalable instruction-following capabilities.
Qwen3-Next-80B-A3B Instruct is a highly efficient instruction-tuned large language model designed for fast, stable responses with ultra-long context handling and high throughput. It activates only a small portion of its 80 billion parameters to achieve significant improvements in speed and cost-efficiency without sacrificing performance in reasoning, code generation, and other complex tasks.
Technical Specifications
Qwen3-Next-80B-A3B Instruct activates only about 3 billion parameters out of 80 billion during inference, making it much faster and cheaper to run — about 10 times faster and more cost-efficient compared to the earlier Qwen3-32B model. It delivers over 10 times higher throughput on long contexts of 32K tokens or more. The model supports flexible deployment options including serverless, on-demand dedicated, and monthly reserved hosting. It is compatible with SGLang and vLLM for deployment with advanced mult-token prediction capabilities, ensuring efficient and scalable usage.
Technical Specifications
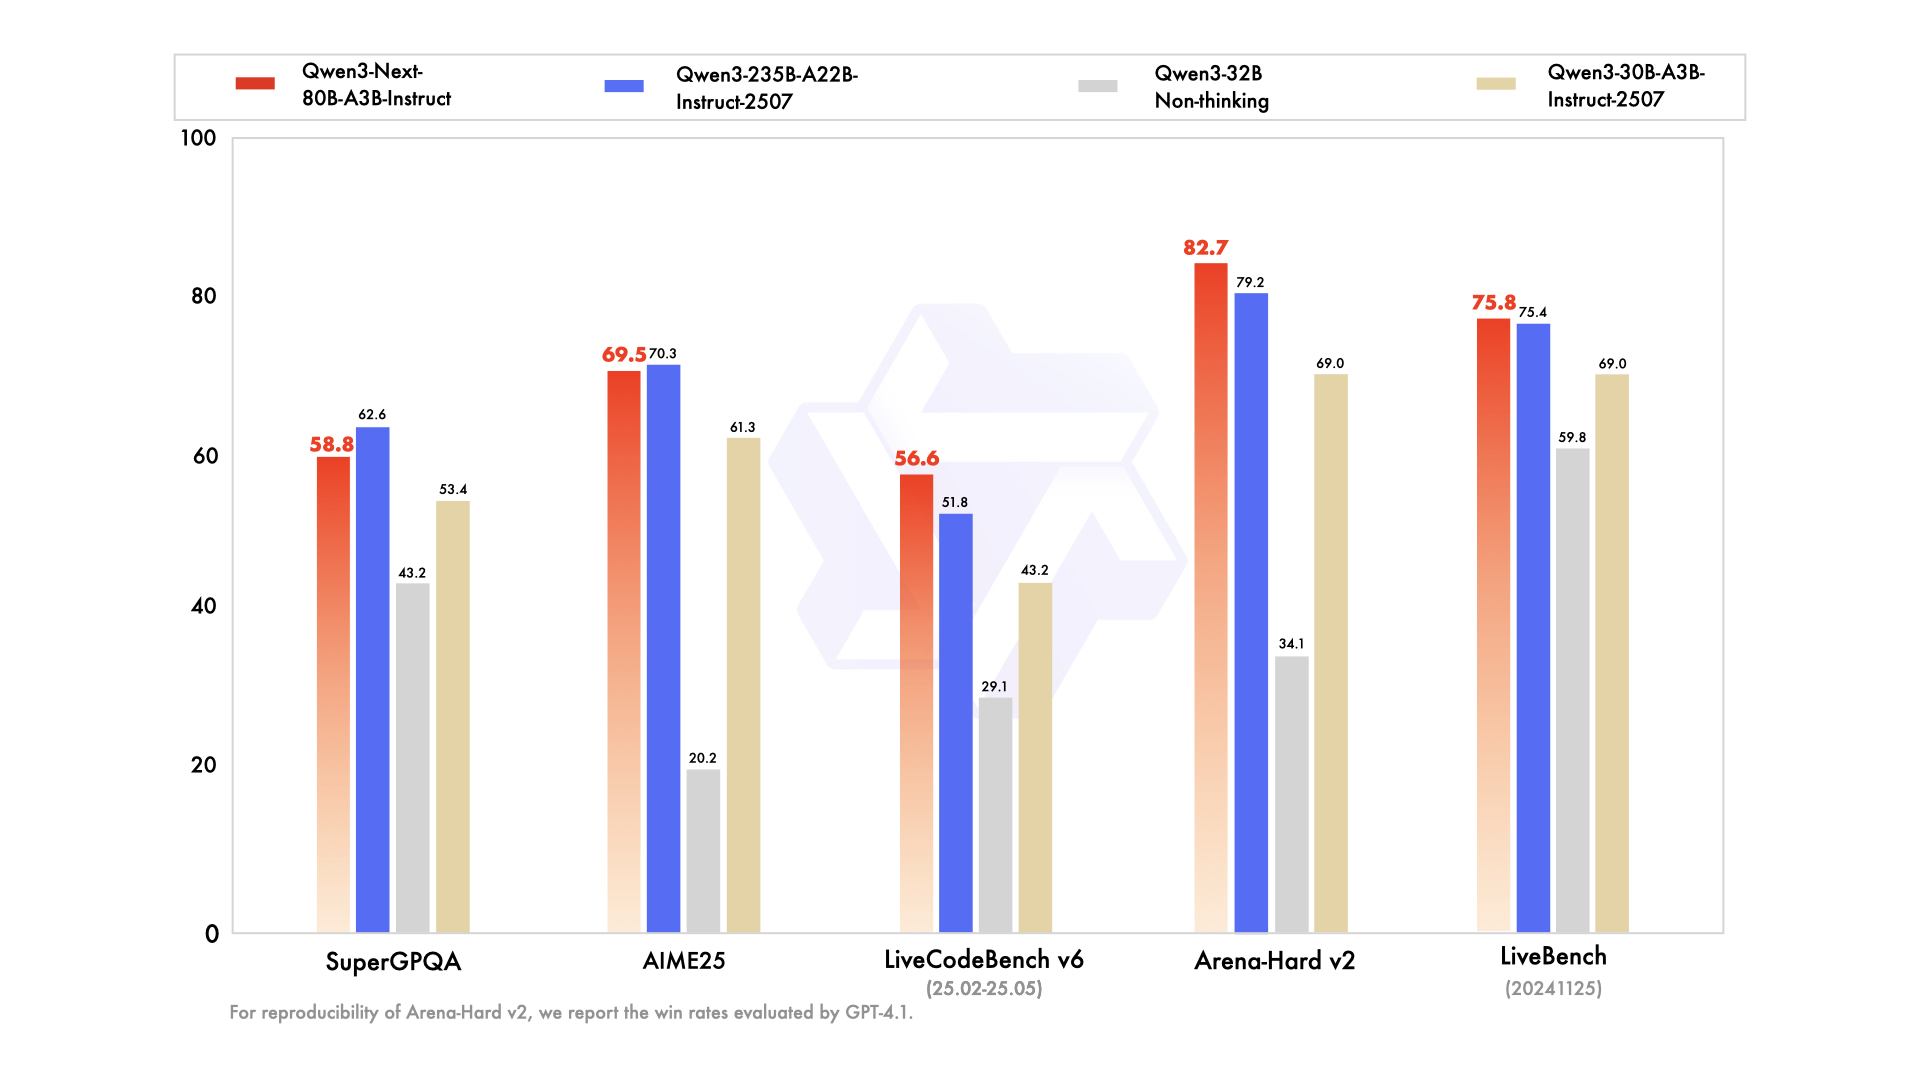
Performance Benchmarks
Performance matches or closely approaches Qwen3-235B flagship in many reasoning, code completion, and instruction-following tasks
Excels in long-context tasks with stable, deterministic answers
Suitable for tools integration, retrieval-augmented generation (RAG), and agentic workflows requiring consistent chain-of-thought outputs
API Pricing
Input: $0.195
Output: $1.56
Key Capabilities
Highly efficient instruction-following with sparse Mixture-of-Experts (MoE) architecture activating only 3B parameters out of 80B, offering faster and cheaper inference.
Exceptional performance on complex tasks including reasoning, code generation, knowledge question answering, and multilingual usage.
Stable and fast responses optimized for instruction mode without intermediate “thinking” steps.
Supports ultra-long context handling with native 262K token length, extendable to 1 million tokens with scaling technology.
High throughput for processing long contexts (10x improvement over previous models).
Excellent for multi-turn dialogues and tasks requiring deterministic, consistent final answers.
Strong capabilities for tool calling, multi-step task execution, and agentic workflows with integrated tools.
Use Cases
Code generation and software development assistance
Content creation and editing based on detailed instructions
Data analysis and complex report generation
Customer service automation with precise instruction handling
Technical documentation generation and format-specific outputs
Process automation including multi-step task execution and tool calling
Handling of long conversations and large documents
Code Sample
Comparison with Other Models
vs Qwen3-235B: The 80B A3B model matches or closely approaches the flagship 235B in reasoning and code tasks but is much more efficient, activating fewer parameters for faster, cheaper inference.
vs GPT-4.1: Qwen3-Next offers comparable instruction-following and long-context capabilities, with an edge in throughput and token window size, making it suitable for extensive document comprehension.
vs Claude 4.1 Opus: Qwen3-Next provides superior performance in multi-turn dialogues and agentic workflows, with more deterministic outputs on very long contexts compared to Claude’s conversational strengths.
vs Gemini 2.5 Flash: Qwen3-Next shows better scaling in ultra-long context handling and multi-token prediction efficiency, giving it an advantage in processing complex, multi-step reasoning tasks.
Uptime and performance
Uptime (24h): 100%
Uptime (7d): 100%
Availability (24h): 100%
Error rate (24h): 0%
Measured on the AI/ML API gateway across live traffic. Figures are medians unless stated. Last updated 2026-10-12.
Use cases
Code generation and software development assistance
Content creation and editing based on detailed instructions
Data analysis and complex report generation
Customer service automation with precise instruction handling
Technical documentation generation and format-specific outputs
Process automation including multi-step task execution and tool calling
Handling of long conversations and large documents
How to use Qwen3-Next-80B-A3B Instruct API
Install any OpenAI-compatible SDK, point it at api.aimlapi.com/v1, and set the model to alibaba/qwen3-next-80b-a3b-instruct.