

Text to image
Elo · text-to-image arena
Custom pricing for production workloads

Grok Imagine Image is a lightweight text-to-image model by xAI optimized for fast and cost-efficient image generation.
The Grok Imagine Image API is xAI's most capable image generation and editing model, delivering photorealistic output, multi-style mastery, and best-in-class prompt adherence through a single, developer-friendly REST endpoint.
x-ai/grok-imagine-imagePOST https://api.aimlapi.com/v1/images/generationsThe Grok Imagine Image API is xAI's flagship visual generation model, built to handle the full creative lifecycle from a blank text prompt to a polished, production-ready image. Developed by the same team behind the Grok family of foundation models, it was engineered with a dual mandate: exceptional output quality and real-world developer economics.
Under the hood, Grok Imagine Image draws on an autoregressive architecture, originally code-named Aurora, that builds images patch by patch, much like a language model builds text token by token. The result is remarkably coherent output, with tightly controlled composition, accurate anatomical rendering, and legible in-image text that many diffusion-based models struggle with.
Unlike most image generation tools that bolt generation capabilities onto a general-purpose assistant, Grok Imagine Image was purpose-built for visual creation. The model interprets natural language with strong prompt fidelity, which means what you describe is genuinely close to what you get, even for complex, multi-element scenes.
Transform natural language descriptions into high-fidelity images across dozens of visual styles from hyperrealistic photography to anime, oil painting, pencil sketch, stenciled street art, and cinematic renders.
The model's prompt adherence is a genuine differentiator here. Describe a scene with multiple subjects, specific lighting conditions, and a target aesthetic, and Grok Imagine Image delivers output that closely matches your intent, rather than approximating it.
Pass an existing image (via URL or base64) alongside a plain-English instruction "render this as a pencil sketch with detailed shading" or "swap the background to a busy Tokyo street at night" and receive a transformed image that respects both the edit instruction and the original composition.
This is particularly powerful for product photography workflows, where you need multiple variations of a base asset without re-shooting.
Restyle entire scenes with a single prompt. Convert a realistic photograph into an anime illustration, apply cinematic color grading, or shift the artistic medium from digital to watercolor, all without manual masking, layers, or post-processing.
The model shows particular strength in retro anime and cyberpunk aesthetics, making it a natural fit for creative studios, game developers, and content teams that iterate across visual directions rapidly.
Generate images at 1024×1024 pixels as a baseline, suitable for web, social, and lightweight print applications without upscaling. The model handles complex compositions at this resolution without the quality degradation common in lower-end generation models.
Accurate rendering of hands, faces, and legible in-image text are standout strengths, areas where many competing models still leave visual artifacts.
Teams across industries are already using Grok Imagine to cut production time and eliminate bottlenecks in visual content workflows.
Text-to-image generation is documented for Grok Imagine Image, including generating new images from text prompts.
Image editing is documented, including editing an existing image by providing a source image and a prompt describing the changes.
Image-to-image workflows are documented, including using reference images for generation or style transfer.
Batch image generation is documented, including generating multiple images and controlling aspect ratio, resolution, and quality.
 Artificial Analysis
Human-preference results for Grok Imagine in text to image, next to models available on AI/ML API. Data retrieved Nov 3, 2026.
Elo · text-to-image arena
USD per generation
Arena results for models you can call with the same API key.
Blind pairwise human votes on images generated from text prompts. Grok Imagine ranks #34 of 98.
| Usage | Price | Unit |
|---|---|---|
| Image generation | $0.02 | per generation |
Prices from the AI/ML API price list, checked on Nov 4, 2026.
AI/ML API rates for 5 models, per generation.
| Model | Per generation |
|---|---|
| Grok Imagine | $0.02 |
 FLUX.1 Dev | $0.025 |
 Wan 2.2 Flash | $0.025 |
| Grok Imagine Image 2.0 | $0.04 |
| Grok Imagine Image Pro | $0.05 |



Give your agent the model details, code and documentation.
export AIMLAPI_KEY="8f2b4c7d9a1e6b3f…"curl 'https://api.aimlapi.com/v1/images/generations' \
-H "Authorization: Bearer $AIMLAPI_KEY" \
-H 'Content-Type: application/json' \
-d '{
"model": "x-ai/grok-imagine-image",
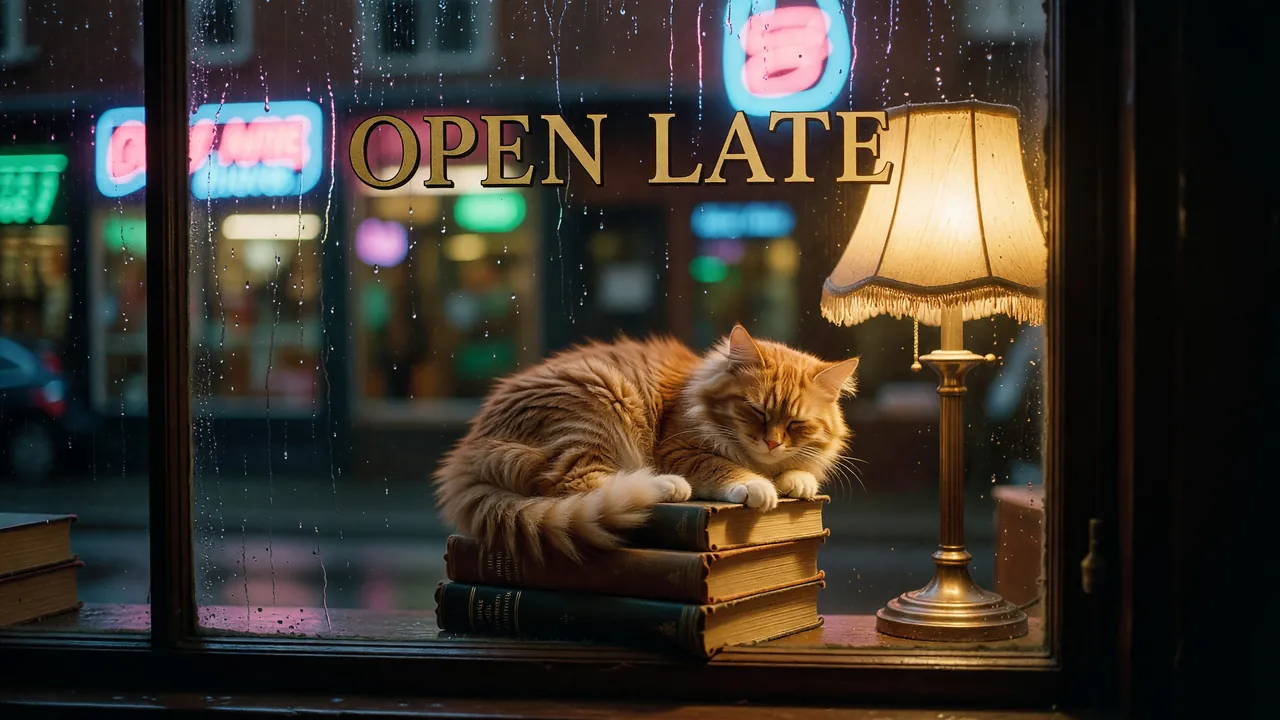
"prompt": "A ginger cat asleep on a stack of exactly three hardcover books in a rainy bookshop window at dusk. Gold lettering on the glass reads OPEN LATE. Warm lamp light inside, raindrops and blurred neon reflections outside, 35mm film photo."
}'import os
import requests
headers = {
"Authorization": f"Bearer {os.environ['AIMLAPI_KEY']}",
"Content-Type": "application/json",
}
payload = {
"model": "x-ai/grok-imagine-image",
"prompt": "A ginger cat asleep on a stack of exactly three hardcover books in a rainy bookshop window at dusk. Gold lettering on the glass reads OPEN LATE. Warm lamp light inside, raindrops and blurred neon reflections outside, 35mm film photo."
}
response = requests.post("https://api.aimlapi.com/v1/images/generations", headers=headers, json=payload, timeout=120)
response.raise_for_status()
print(response.json())const response = await fetch("https://api.aimlapi.com/v1/images/generations", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.AIMLAPI_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"model": "x-ai/grok-imagine-image",
"prompt": "A ginger cat asleep on a stack of exactly three hardcover books in a rainy bookshop window at dusk. Gold lettering on the glass reads OPEN LATE. Warm lamp light inside, raindrops and blurred neon reflections outside, 35mm film photo."
}),
});
if (!response.ok) throw new Error(`HTTP ${response.status}`);
console.log(await response.json());Grok Imagine takes image, text as input and returns image.
Grok Imagine costs $0.02 per generation on AI/ML API, billed as you go with no subscription.
Grok Imagine is billed per generation, a fixed charge per output rather than by prompt length.
Yes, Grok Imagine accepts image input as well as a text prompt.
Grok Imagine was built by xAI .
Send a request to https://api.aimlapi.com/v1/images/generations with x-ai/grok-imagine-image as the model id.
Yes. Grok Imagine is served through AI/ML API, so the same key and endpoint format used for other models applies.
No, Grok Imagine is an image generation model that only produces images from text input.
Grok Imagine is a lightweight text-to-image model by xAI built for fast, cost-efficient image generation.
Use x-ai/grok-imagine-image as the model parameter. Requests go to https://api.aimlapi.com/v1/images/generations with your AI/ML API key.


