

Seedream 4 Text-to-Image overview
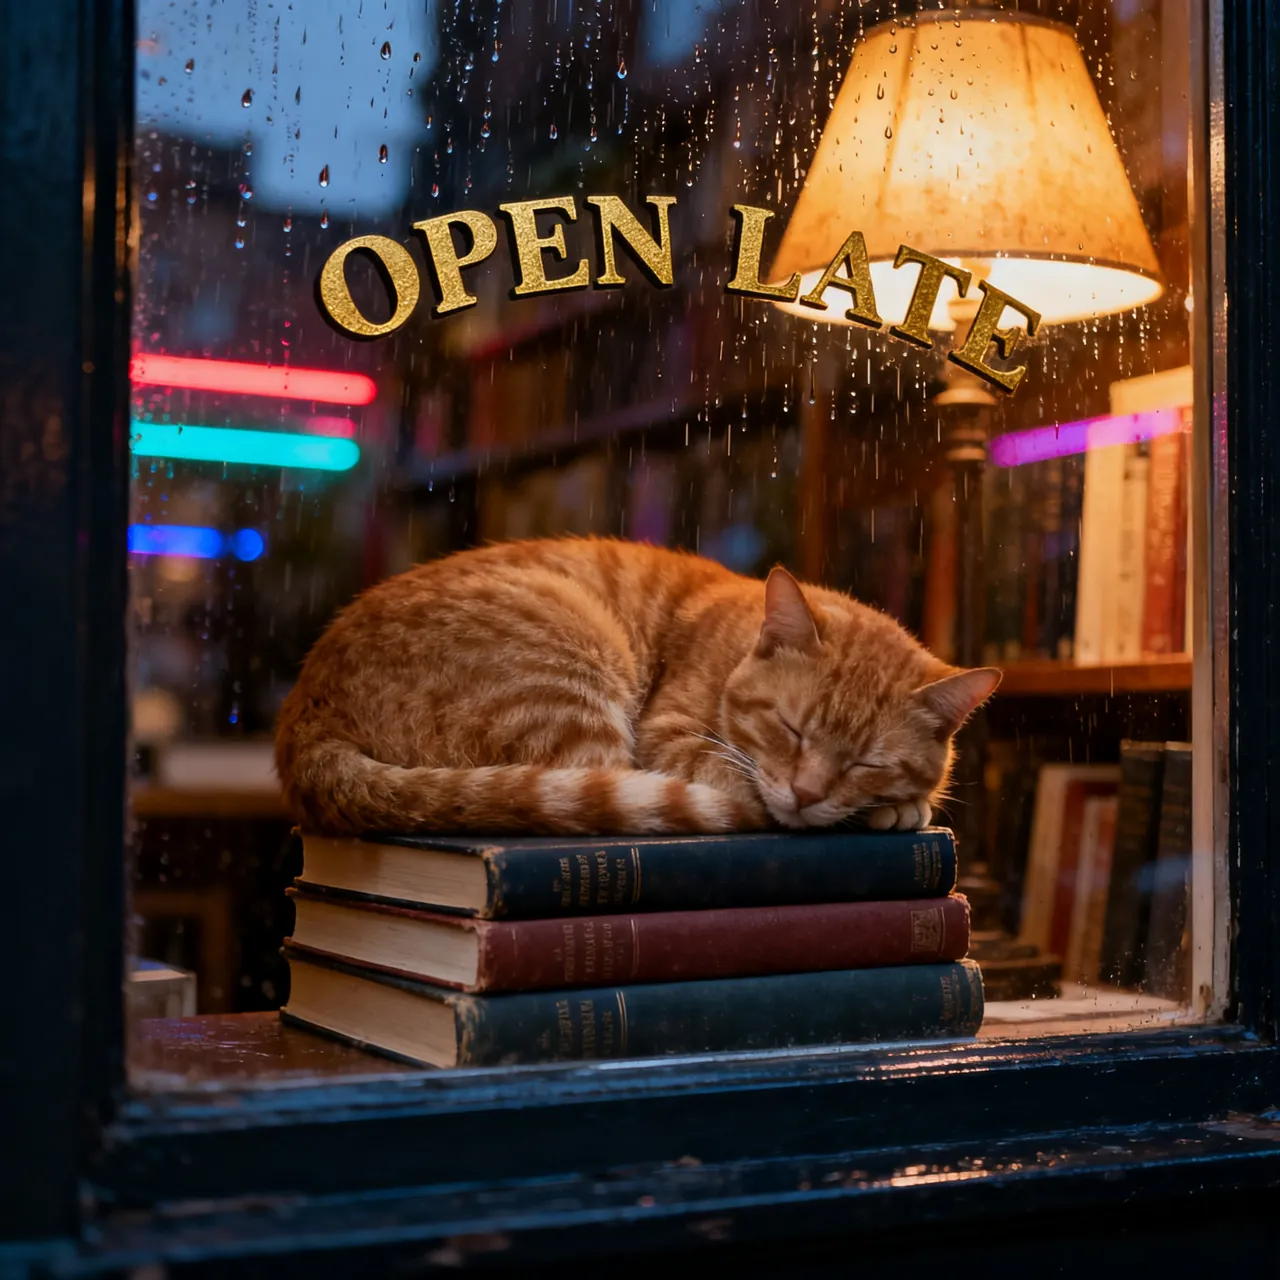
Seedream 4 Text-to-Image by ByteDance
The model is designed for scalability, handling batch generation and multimodal inputs efficiently.
Seedream 4 Text-to-Image specs
- Model ID
bytedance/seedream-v4-text-to-image- Developer
- ByteDance
- Input
- Text, Image
- Output
- Image
- Endpoint
POST https://api.aimlapi.com/v1/images/generations
Seedream 4 Text to Image Description
Seedream 4 is ByteDance’s advanced AI model that unifies image generation within a single powerful platform. It delivers photorealistic images at 2K resolution in about 1.8 seconds and supports outputs up to 4K resolution, enabling rapid, high-quality content creation. The model accepts up to six reference images and can generate up to nine consistent images simultaneously, ideal for batch campaigns and storyboard workflows. It features natural language-driven editing, allowing users to add or remove elements easily without complex inputs, while maintaining strong character consistency. Seedream 4 supports bilingual prompts in Chinese and English, making it accessible for global and localized creative workflows.
Performance Benchmarks
- Inference Speed: Seedream 4 Text to Image produces high-resolution images (2048×2048 pixels) in approximately 1.8 seconds, setting an industry standard for fast and efficient generation suited for real-time creative use.
- Resolution Support: Supports outputs up to 4K resolution, delivering ultra-sharp, photorealistic visuals with professional-grade lighting, textures, and aesthetics.
- Prompt Adherence: Excels at accurately translating complex natural language prompts into detailed visuals that reflect conceptual intent and fine visual details.
Technical Overview
Seedream 4 is built on ByteDance’s next-generation hybrid transformer architecture featuring a dynamic Mixture of Experts (MoE) design. This advanced architecture dynamically allocates computation at the token level, enabling ultra-low latency and high-quality image generation. The MoE layers provide efficient scaling, delivering 2K resolution outputs in roughly 1.8 seconds and supporting up to 4K ultra-high-resolution outputs.
This unified model supports text-to-image generation and batch creation within a single multimodal framework. It handles complex inputs, including natural language prompts, up to six reference images, and video frames, enabling rich multimodal reasoning and synthesis with strong semantic and prompt fidelity.
Key Features
- Natural language-driven editing: Allows intuitive image modifications via text commands without the need for masks or bounding boxes.
- Character consistency and detail preservation: Maintains facial features, clothing, lighting, and textures across different styles and images, preventing visual inconsistencies.
- Photorealistic image quality: Produces professional-grade visuals with flawless lighting and texture, supporting styles from realistic cinematics to abstract art.
- Native bilingual support: Accurately understands and processes both Chinese and English prompts, catering to a global and localized user base.
- Context-aware generation: Leverages semantic understanding for context-rich image synthesis, such as infographics or thematic visuals.
- Multi-reference and batch generation: Supports up to six reference images and batch outputs up to nine images maintaining coherence.
Use Cases
- E-commerce and Marketing: Rapid generation of product variations, lifestyle shots, and advertising visuals with consistent style and identity across campaigns, supporting quick iterative creative cycles.
- Storyboard and Comic Creation: Producing coherent sequences of images for artists and filmmakers that enable narrative planning and shot composition without manual frame-by-frame editing.
- Interior and Concept Design: Refinement of sketches and photos with lighting, style, and compositional adjustments to create high-resolution renderings suitable for presentations and client approvals.
- Fan Art and Illustration: Multi-reference and style-consistent generation allow creation of stylized portraits, anime characters, and collectibles with preserved character identity.
- Professional Poster and Infographic Design: High-resolution outputs up to 4K with superior text rendering, layout composition, and precise natural language-driven editing help produce compelling visual assets.
- Creative Multimedia Content: Integration of text, images, and videos to generate advertising, entertainment, and e-learning materials with rich semantic alignment.
Comparison with Other Models
vs Gemini 2.5 Flash Image: Seedream 4 demonstrates superior understanding of user intent, producing more accurate and contextually relevant edits. It also outperforms Gemini 2.5 in maintaining character consistency and complex scene detail.
vs Seedream 3.0: Seedream 4 achieves about 35% faster inference speeds and supports higher output resolutions up to 4K. It also unifies generation and editing capabilities into one model, unlike Seedream 3.50 which handles these separately.
vs Flux Kontext: Seedream 4 provides significantly better prompt adherence, image alignment, and text rendering quality. Flux Kontext often produces inconsistent compositions and less polished images.
vs Qwen-Image: Seedream 4 handles complex scenes and multi-object prompts with better accuracy and coherence. Qwen-Image struggles with complex logic and retrieves weaker prompt alignment.
Use cases
- E-commerce and Marketing: Rapid generation of product variations, lifestyle shots, and advertising visuals with consistent style and identity across campaigns, supporting quick iterative creative cycles.
- Storyboard and Comic Creation: Producing coherent sequences of images for artists and filmmakers that enable narrative planning and shot composition without manual frame-by-frame editing.
- Interior and Concept Design: Refinement of sketches and photos with lighting, style, and compositional adjustments to create high-resolution renderings suitable for presentations and client approvals.
- Fan Art and Illustration: Multi-reference and style-consistent generation allow creation of stylized portraits, anime characters, and collectibles with preserved character identity.
- Professional Poster and Infographic Design: High-resolution outputs up to 4K with superior text rendering, layout composition, and precise natural language-driven editing help produce compelling visual assets.
- Creative Multimedia Content: Integration of text, images, and videos to generate advertising, entertainment, and e-learning materials with rich semantic alignment.
Seedream 4 Text-to-Image API pricing
| Usage | Price | Unit |
|---|---|---|
| Image generation | $0.03 | per generation |
The final price depends on request parameters such as resolution or duration.
Prices from the AI/ML API price list, checked on Nov 4, 2026.
Seedream 4 Text-to-Image vs other image models: prices
AI/ML API rates for 5 models, per generation.
| Model | Per generation |
|---|---|
 Seedream 4 Text-to-Image | $0.03 |
| Dreamina Creative Upscale | $0.031 |
| Seedream 5.0 Lite Preview | $0.035 |
| Seedream 4.5 | $0.04 |
| Seedream 5.0 Pro | $0.045 |
How to use the Seedream 4 Text-to-Image API
View docs



Build with your agent
Give your agent the model details, code and documentation.
1Get your API key
Create API keyexport AIMLAPI_KEY="8f2b4c7d9a1e6b3f…"2Make your first request
curl 'https://api.aimlapi.com/v1/images/generations' \
  -H "Authorization: Bearer $AIMLAPI_KEY" \
  -H 'Content-Type: application/json' \
  -d '{
  "model": "bytedance/seedream-v4-text-to-image",
  "prompt": "A ginger cat asleep on a stack of exactly three hardcover books in a rainy bookshop window at dusk. Gold lettering on the glass reads OPEN LATE. Warm lamp light inside, raindrops and blurred neon reflections outside, 35mm film photo."
}'
import os
import requests
headers = {
"Authorization": f"Bearer {os.environ['AIMLAPI_KEY']}",
"Content-Type": "application/json",
}
payload = {
"model": "bytedance/seedream-v4-text-to-image",
"prompt": "A ginger cat asleep on a stack of exactly three hardcover books in a rainy bookshop window at dusk. Gold lettering on the glass reads OPEN LATE. Warm lamp light inside, raindrops and blurred neon reflections outside, 35mm film photo."
}
response = requests.post("https://api.aimlapi.com/v1/images/generations", headers=headers, json=payload, timeout=120)
response.raise_for_status()
print(response.json())const response = await fetch("https://api.aimlapi.com/v1/images/generations", {
method: "POST",
headers: {
Authorization: `Bearer ${process.env.AIMLAPI_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({
"model": "bytedance/seedream-v4-text-to-image",
"prompt": "A ginger cat asleep on a stack of exactly three hardcover books in a rainy bookshop window at dusk. Gold lettering on the glass reads OPEN LATE. Warm lamp light inside, raindrops and blurred neon reflections outside, 35mm film photo."
}),
});
if (!response.ok) throw new Error(`HTTP ${response.status}`);
console.log(await response.json());Models similar to Seedream 4 Text-to-Image


Related articles


Seedream 4 Text-to-Image FAQ
What inputs and outputs does Seedream 4 Text-to-Image support?
Seedream 4 Text-to-Image takes image, text as input and returns image.
How much does Seedream 4 Text-to-Image cost?
Seedream 4 Text-to-Image costs $0.03 per generation on AI/ML API, billed as you go with no subscription.
How is Seedream 4 Text-to-Image billed?
Seedream 4 Text-to-Image is billed per generation, a fixed charge per output rather than by prompt length.
Can Seedream 4 Text-to-Image take an existing image as input?
Yes, Seedream 4 Text-to-Image accepts image input as well as a text prompt.
Who created Seedream 4 Text-to-Image?
Seedream 4 Text-to-Image was built by ByteDance.
How do I call Seedream 4 Text-to-Image on AI/ML API?
Send a request to https://api.aimlapi.com/v1/images/generations with bytedance/seedream-v4-text-to-image as the model id.
Is Seedream 4 Text-to-Image available through a single API key?
Yes. Seedream 4 Text-to-Image is served through AI/ML API, so the same key and endpoint format used for other models applies.
What is the Seedream 4 Text-to-Image model ID?
Use bytedance/seedream-v4-text-to-image as the model parameter. Requests go to https://api.aimlapi.com/v1/images/generations with your AI/ML API key.