DeepSeek V3.1 is a high-efficiency hybrid AI model optimized for fast, direct responses without deep reasoning, supporting extensive multimodal inputs and large context windows.
DeepSeek-V3.1 is a next-generation hybrid language model built by DeepSeek AI. It runs on a Mixture-of-Experts (MoE) transformer architecture, which means it routes each inference request through a small, relevant subset of its parameters, keeping latency low and compute costs lean without sacrificing output quality.
The Chat variant specifically operates in non-thinking mode. Rather than working through multi-step reasoning chains, it returns direct, high-quality answers with minimal overhead. That design choice makes DeepSeek-V3.1 a natural fit for applications where speed is a first-class requirement: customer-facing chatbots, CI/CD code automation pipelines, real-time data extraction, and any agentic system calling external tools in a tight loop.
Low-Latency Direct Responses
The non-thinking Chat mode skips deliberation overhead entirely. You get crisp answers fast — ideal for high-throughput production environments.
Native Tool & Agent Calling
First-class support for structured function calls, code agents, and search agents. Build complex agentic pipelines without bolting on workarounds.
Mixture-of-Experts Efficiency
MoE layers activate only the parameters relevant to each token. The result: competitive performance at a significantly lower compute footprint than dense alternatives.
100+ Language Multilinguality
Extended multilingual training means you can serve global users from a single model deployment without separate fine-tuning per language.
Features
Technical Specifications
Every parameter below is relevant to planning your integration. Understanding them upfront helps you size context windows correctly, avoid truncation surprises, and choose the right sampling settings for your use case.
The model's non-thinking, high-speed profile makes it particularly strong in scenarios where fast, accurate, and contextually aware output matters more than deep step-by-step deliberation.
Code Generation & Review
Write, debug, and refactor code across Python, TypeScript, Go, Rust, and more. The 128K context lets the model process full files and multi-file diffs in a single request, no chunking required.
Agentic Workflows
DeepSeek-V3.1 ships with built-in support for structured tool calls, code execution agents, and search agents. Wire it into LangChain, AutoGen, or your own orchestration layer for autonomous task execution.
Customer-Facing Chatbots
High response speed and multilingual support across 100+ languages make this a strong foundation for global support bots that need consistent, coherent replies without visible latency.
Document & Research Analysis
Feed entire reports, contracts, or research papers into the 128K window and extract structured summaries, comparisons, or action items. No pre-chunking pipelines, no retrieval workarounds for moderate-length docs.
Multimodal Business Intelligence
Combine image and text inputs to process charts, screenshots, or scanned documents alongside natural language queries, useful for financial dashboards, compliance review, and visual data extraction.
EdTech & Adaptive Tutoring
Build responsive, multi-turn educational tools that explain concepts clearly, adapt to learner level, and handle follow-up questions, without the reasoning overhead of a more expensive model.
API Pricing
• 1М input tokens: $0.294
• 1М output tokens: $0.441
DeepSeek-V3.1 vs Comparable Models
Knowing where a model excels (and where it doesn't) saves you from using an expensive sledgehammer for a finishing nail. Here's how DeepSeek-V3.1 stacks up against the main alternatives you're likely to consider.
Comparison with Other Models
DeepSeek-V3.1 vs. DeepSeek V3
V3.1 is a meaningful step up from its predecessor. Inference speed has improved by around 30%, multimodal alignment accuracy is noticeably better, and handling of low-resource languages is sharper. For anyone already on DeepSeek V3, migrating to V3.1 is an easy upgrade — the API interface is identical.
DeepSeek-V3.1 vs. GPT-4.1
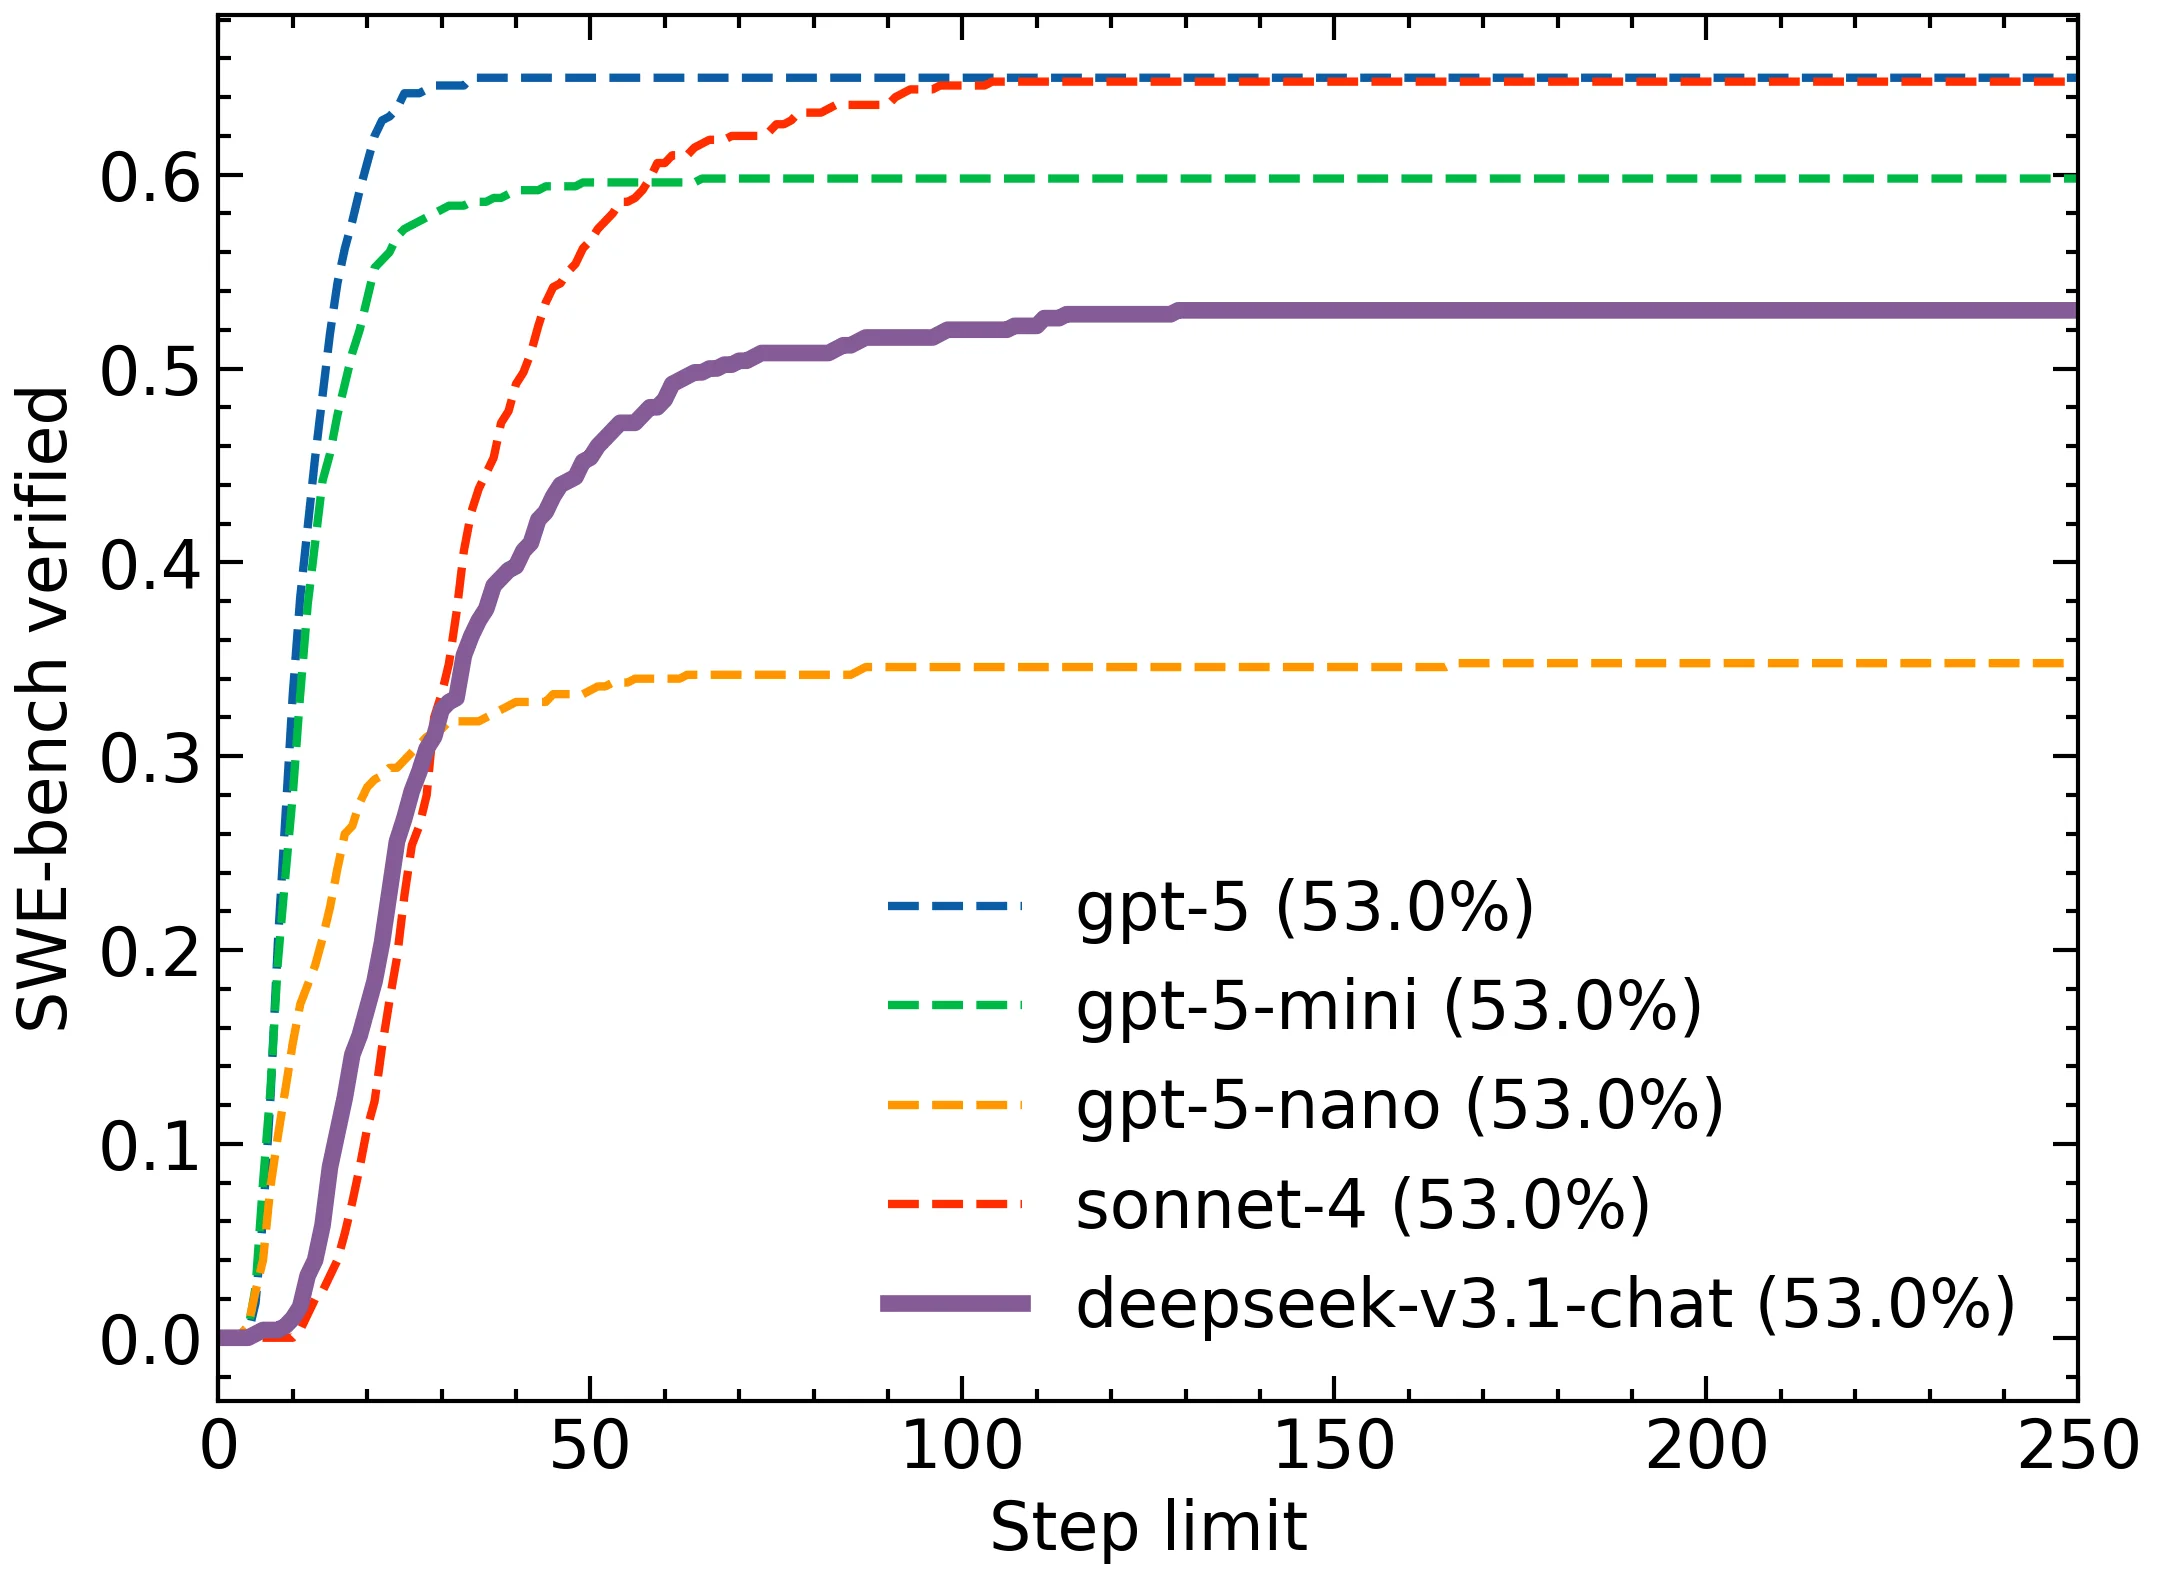
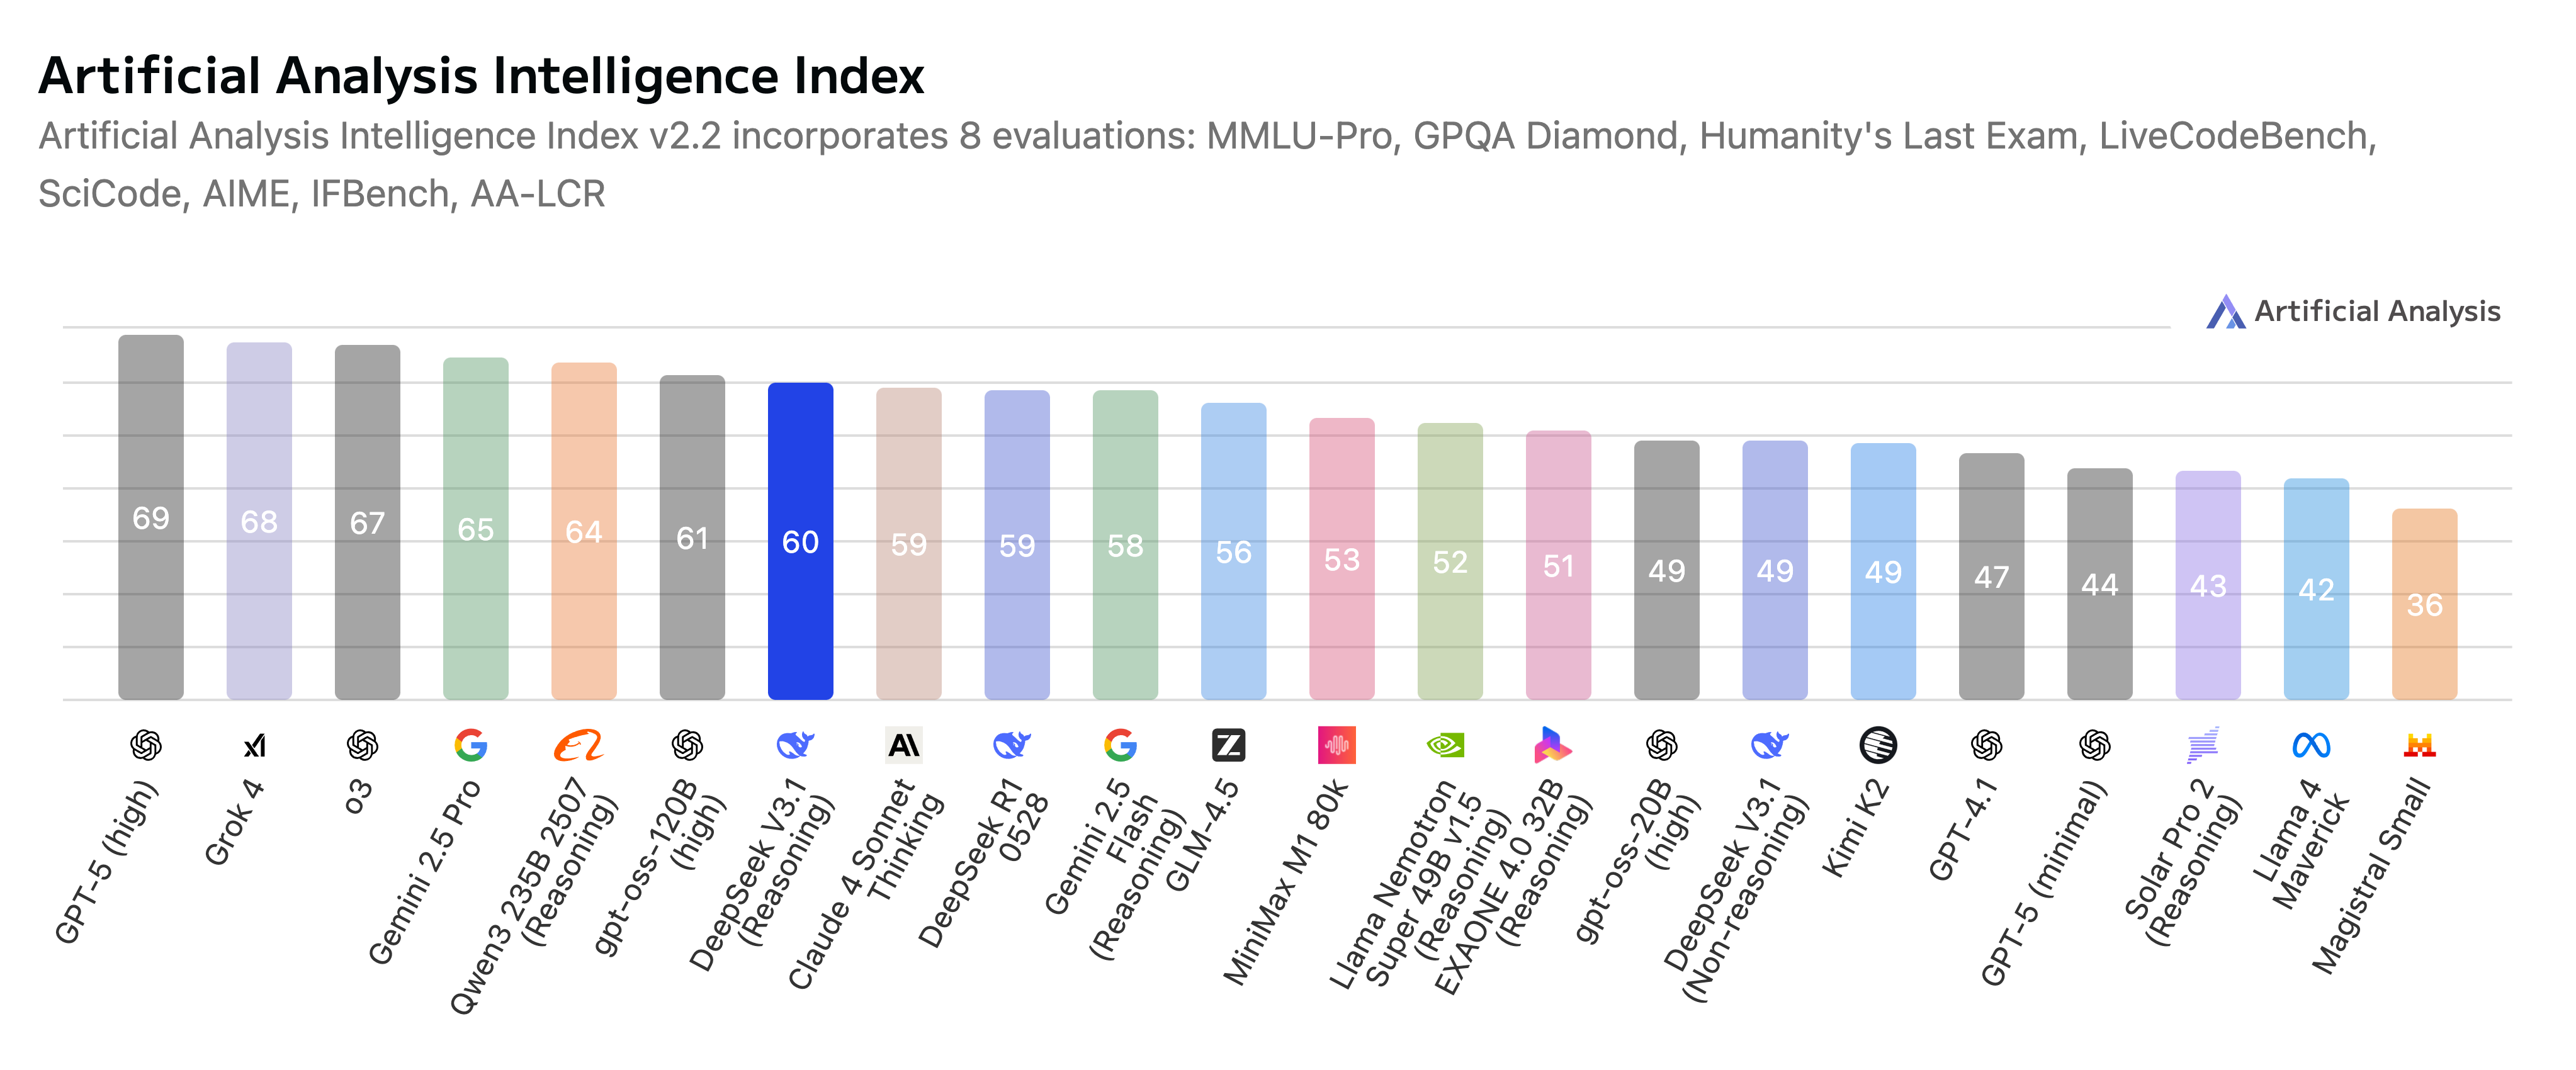
GPT-4.1 is OpenAI's code-optimized workhorse and a fine choice if you're deep in the OpenAI ecosystem. DeepSeek-V3.1 offers a different tradeoff: the MoE architecture delivers better resource efficiency, and its visual-textual coherence is stronger for multimodal tasks. For pure code generation, quality is competitive at roughly 7× lower cost.
DeepSeek-V3.1 vs. GPT-5
GPT-5 is a more powerful model with a 400K context window and broader multimodal breadth. For tasks that genuinely need that scale, it's the right call. But DeepSeek-V3.1 covers the majority of real-world production workloads at a fraction of the price — and through AI/ML API you can mix both under a single account, routing tasks to the right model without switching integrations.
Uptime and performance
Uptime (24h): 100%
Uptime (7d): 100%
Availability (24h): 100%
Error rate (24h): 0%
End-to-end latency (24h median): 130.0s
Time to first token (24h median): 3.0s
Throughput (24h median): 20.4 tok/s
Measured on the AI/ML API gateway across live traffic. Figures are medians unless stated. Last updated 2026-10-12.
Use cases
Fast software engineering assistance including code synthesis and debugging.
Multimodal chatbots focusing on image and text understanding with prompt responses.
Routine research and document analysis with moderate context requirements.
Efficient multi-turn dialogue suited for basic task-oriented educational tools.
Business intelligence processes emphasizing rapid visual data interpretation.
Agentic applications requiring intelligent tool calls without deep reasoning overhead.
How to use DeepSeek-V3.1 API
Install any OpenAI-compatible SDK, point it at api.aimlapi.com/v1, and set the model to deepseek/deepseek-chat-v3.1.