GPT-5.2 represents OpenAI's latest advancement in large language models, engineered for deeper analytical work and superior handling of complex, real-world tasks. It excels at coding assistance, long-document summarization, precise analysis of uploaded files, step-by-step math and logic breakdowns, and structured support for planning and decision-making with enhanced clarity and actionable detail.
This model builds on prior iterations with refined reasoning chains and output polish, making it ideal for professional workflows requiring reliability and depth across technical and cognitive domains.
These technical innovations empower GPT-5.2 to deliver high-precision AI assistance for enterprises, developers, educators, and researchers. Ideal for applications requiring reliable long-context understanding, coding tools, multilingual communication, and content creation workflows.
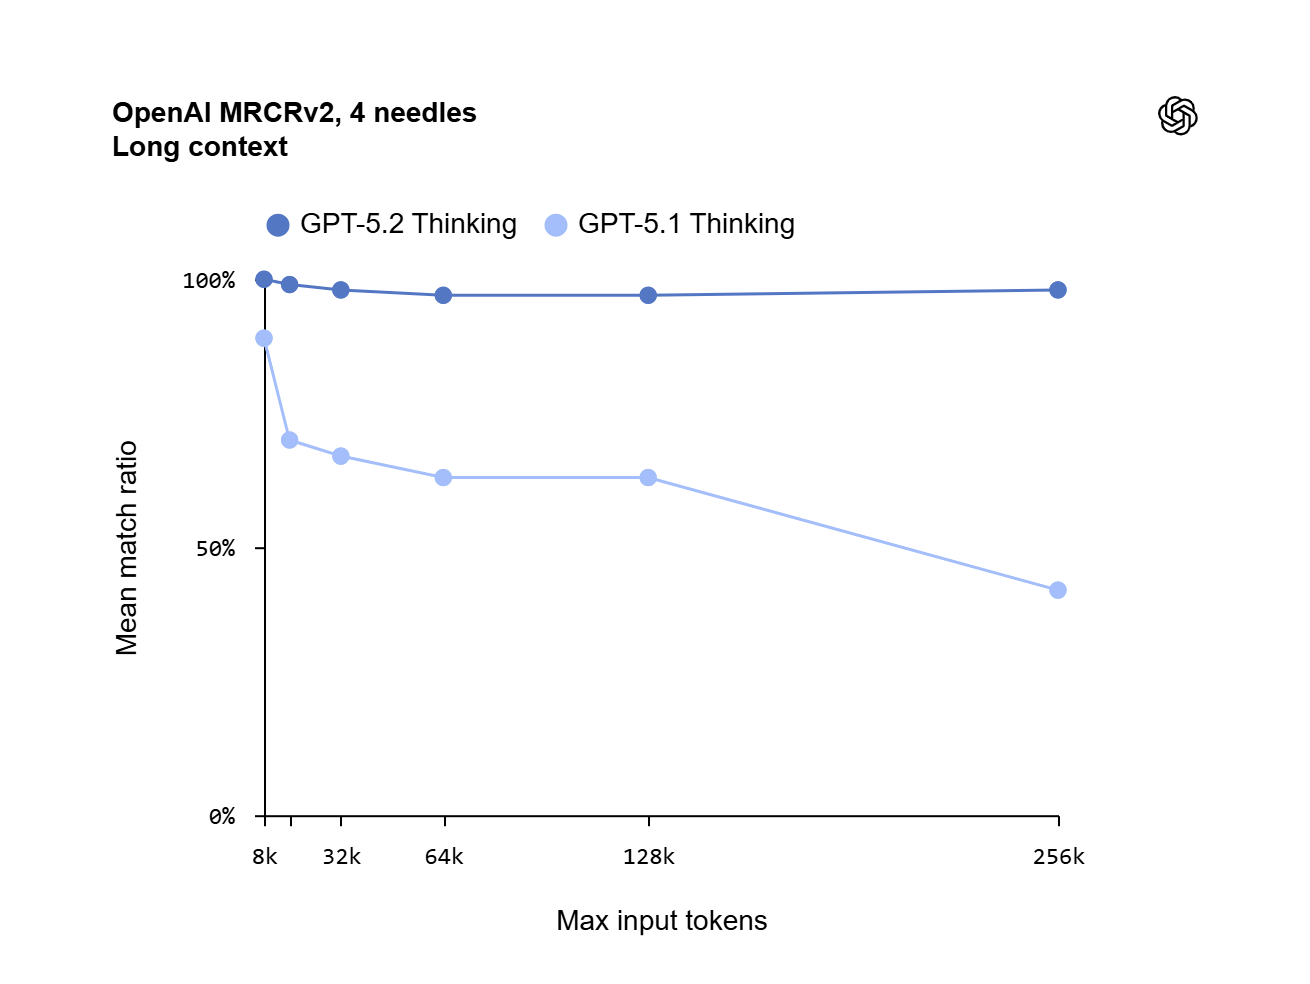
vs GPT-5.1: GPT-5.2 delivers dramatic gains in long-context accuracy (77% vs. 29.6% at 256K), coding (55.6% vs. 50.8% on SWE-Bench Pro), and tool reliability (98.7% vs. 95.6% on Tau2 Telecom). Hallucinations are 30% less frequent, and output quality is consistently more professional.
vs GPT-5: 20% faster with lower energy consumption; improved factual accuracy and fewer hallucinations on extended contexts. Superior handling of complex multi-turn dialogues and abstract reasoning tasks.
Measured on the AI/ML API gateway across live traffic. Figures are medians unless stated. Last updated 2026-10-12.
GPT-5.2 is documented as suited for code-heavy and multi-step agentic tasks, including complex reasoning and broad world knowledge. It is also described as useful for creating spreadsheets, building presentations, writing code, and handling complex, multi-step projects. For professional engineering work, it is presented as a model for debugging production code, implementing feature requests, refactoring large codebases, and shipping fixes end-to-end with less manual intervention. It is additionally described as well suited for analyzing long documents, such as reports, contracts, research papers, transcripts, and multi-file projects, with support for deep analysis, synthesis, and complex multi-source workflows.
import requests

r = requests.post(
    "https://api.aimlapi.com/v1/chat/completions",
    headers={"Authorization": "Bearer " + AIMLAPI_KEY},
    json={
      "model": "openai/gpt-5-2",
      "messages": [
        {
          "role": "user",
          "content": "Hello!"
        }
      ]
    },
)
print(r.json())
const r = await fetch("https://api.aimlapi.com/v1/chat/completions", {
  method: "POST",
  headers: {
    Authorization: `Bearer ${process.env.AIMLAPI_KEY}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
    "model": "openai/gpt-5-2",
    "messages": [
      {
        "role": "user",
        "content": "Hello!"
      }
    ]
  }),
});
console.log(await r.json());
curl -X POST https://api.aimlapi.com/v1/chat/completions \
  -H "Authorization: Bearer $AIMLAPI_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"openai/gpt-5-2","messages":[{"role":"user","content":"Hello!"}]}'
OpenAI-compatible — swap the base URL and it works with your existing SDK.
| Type | Price |
|---|---|
| Input | |
| Output | |
| Cached input |
| Benchmark | Score | What it measures | Source | Retrieved |
|---|---|---|---|---|
| AIME 2025 | 100% | Competition mathematics (AIME), 2025 | Source | July 12, 2026 |
| GPQA Diamond | 92.4% | Google-proof graduate science questions (hardest subset) | Source | July 12, 2026 |
| SWE-bench Verified | 80% | Resolving verified real GitHub issues | Source | July 12, 2026 |
| Intelligence | 30.4 | Composite score across standardised reasoning, knowledge and problem-solving evaluations, measured independently by Artificial Analysis | Source | September 12, 2026 |
| Math | 99 | Composite score across standardised mathematics evaluations, measured independently by Artificial Analysis | Source | September 12, 2026 |
| Model | Input | Output | Context | Best for |
|---|---|---|---|---|
GPT-5.2 This page | Reasoning + agents | |||
| Reasoning + agents | ||||
| Balanced coding + agents | ||||
| Long-context, multimodal & agentic workflows | ||||
| Reasoning + agents |
GPT-5.2 has a 400,000 tokens context window and can return up to 128,000 tokens.
GPT-5.2 takes image, text as input and returns text.
Use openai/gpt-5-2 as the model id. Requests go to https://api.aimlapi.com/v1/chat/completions.
GPT-5.2 is priced at input $2.275 / 1M tokens, output $18.2 / 1M tokens, cached input $0.2275 / 1M tokens.
Yes, GPT-5.2 can stream responses as they are generated.
Yes, GPT-5.2 accepts image input alongside text.
GPT-5.2 was built by OpenAI.
Yes, it supports function calling, parallel tool calls, and structured outputs.






