Gemini 3 Flash Preview is Google’s low-latency, high-throughput multimodal LLM API built for agentic workflows, coding assistants, and document intelligence without giving up Pro-grade reasoning controls.
Gemini 3 Flash (Preview) is built to deliver frontier-ish capability at Flash speed—great for agentic workflows, coding helpers, document intelligence, and high-volume production apps where latency and cost matter as much as quality. It’s rolling out across Gemini API (AI Studio), Vertex AI, and other Google dev surfaces, and it’s also becoming the default in parts of the consumer Gemini experience.
Technical Specifications
Architecture: Transformer-based generative multimodal LLM Context Length: Up to 1M tokens input / 64K tokens output Capabilities: Text + multimodal understanding (images, audio, video, PDFs), structured outputs, tool/function calling, agent-friendly behaviors. Knowledge cutoff: Jan 2025 Inference features: Reasoning (“thinking”) is supported, and output pricing explicitly includes thinking tokens in Gemini API pricing.
Performance Benchmarks
Speed / throughput: Independent pre-release testing reported ~218 output tokens/sec for Gemini 3 Flash Preview (fast enough for real-time-ish agent loops and high-QPS backends). Quality vs prior Flash: Google/DeepMind positions Flash as meaningfully stronger than previous Flash generations for difficult extraction and doc tasks.
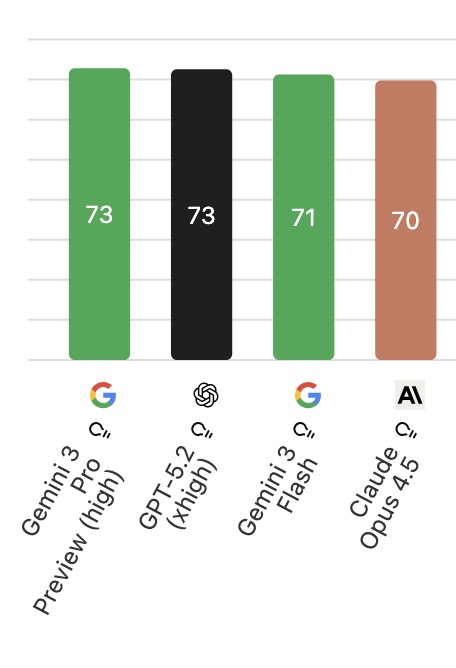
Artificial Analysis Intelligence Index
Quality Improvements
More nuanced answers at lower latency than the prior default Flash in Gemini (per Google’s positioning and reporting around the rollout).
Stronger document/extraction performance: DeepMind highlights a relative improvement (~15%) in overall accuracy vs Gemini 2.5 Flash for hard extraction scenarios (e.g., handwriting, long contracts, financial docs).
Agent readiness: Designed to keep “Pro-grade” reasoning foundations while staying Flash-fast for multi-step tool use and workflows.
New Features & Technical Upgrades
1M-token long context (with 64K output) for long docs, multi-file projects, and persistent agent state.
Multimodal tool/function calling (including support for multimodal content in certain function-response flows).
API Pricing
Input: $0.65
Output : $3.9
Practical Impact
Gemini 3 Flash is a strong default when you need:
High-throughput assistants (support, ops copilots, internal tools) with tool calling
Document intelligence at scale (summaries, extraction, Q&A across long PDFs / corpora)
Gemini 3 Pro is the “reasoning-first” flagship, while Flash targets similar agentic/coding workflows but optimized for cost/latency.
Gemini 3 Flash vs Gemini 2.5 Flash
Gemini 3 Flash is positioned as a major upgrade (replacing the prior default Flash), aiming for more detailed answers while staying fast.
Gemini 3 Flash vs GPT-5.2
GPT-5.2 is a reasoning/coding-first flagship that’s typically chosen when you want the most dependable multi-step analysis, strong code correctness, and consistent “final answer” polish in complex, real-world workflows. Gemini 3 Flash (Preview) targets many of the same agentic/coding and document-intelligence use cases, but it’s tuned primarily for low latency and high throughput, making it a more “speed-first” default when responsiveness matters. The other big practical difference is context behavior: Flash emphasizes very long input context for feeding large corpora or long documents, while GPT-5.2 emphasizes high-quality long-form reasoning and large outputs for deeply structured work.
Limitations and Guardrails
Gemini 3 Flash applies policy-based safety filtering and can block or stop generations for restricted categories. Guardrails can feel stricter on edge-case prompts (especially around sensitive topics), and long-context or high “thinking” settings may increase latency and token usage, so production apps usually need fallback prompts and clear UX for refusals.
Uptime and performance
Uptime (24h): 100%
Uptime (7d): 100%
Availability (24h): 100%
Error rate (24h): 0%
End-to-end latency (24h median): 9.8s
Time to first token (24h median): 5.0s
Throughput (24h median): 178.7 tok/s
Measured on the AI/ML API gateway across live traffic. Figures are medians unless stated. Last updated 2026-10-12.
Use cases
Gemini 3 Flash Preview is documented as suited for coding, complex analysis, and quick answers in interactive apps. It is also described as useful for complex video analysis, data extraction, and visual Q&A.
It is documented as appropriate for agentic workflows and tool use, including multi-turn chat and collaborative coding tasks. It is also presented as useful for document analysis and deepfake detection.
How to use Gemini 3 Flash API
Install any OpenAI-compatible SDK, point it at api.aimlapi.com/v1, and set the model to google/gemini-3-flash-preview.