DeepSeek V3.2 Speciale is an advanced reasoning-focused large language model (LLM) designed to handle multi-step logical problems and extended context processing up to 128K tokens. It introduces a “thinking-only” mode that allows the model to perform silent reasoning before producing output, a feature that improves accuracy, factual coherence, and stepwise deduction on complex queries.
The model complies with DeepSeek’s Chat Prefix/FIM completion specifications, supports tool calling, and is offered through a Speciale endpoint with limited-duration access. Positioned between research and applied AI reasoning, it delivers analytical consistency for code, math, and scientific reasoning tasks.
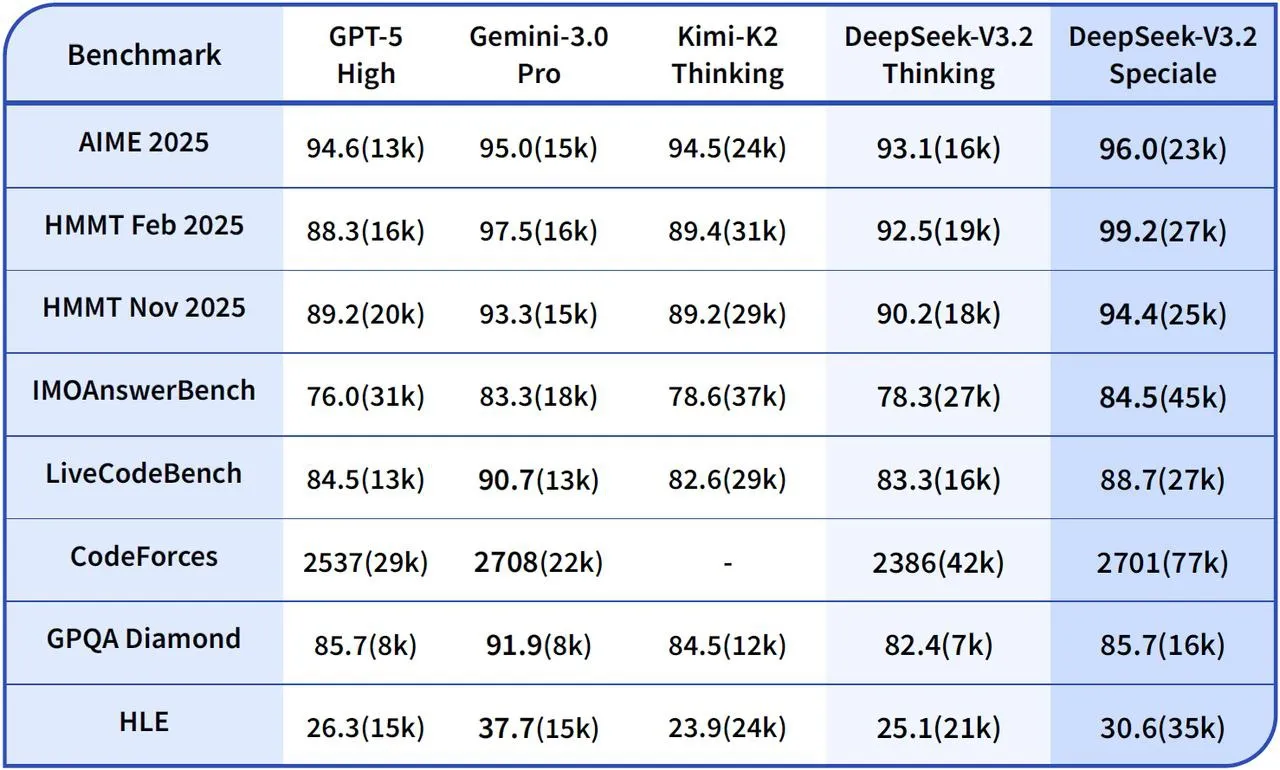
Users and testers report noticeable advancements in structured logical coherence, response transparency, and mathematical precision.
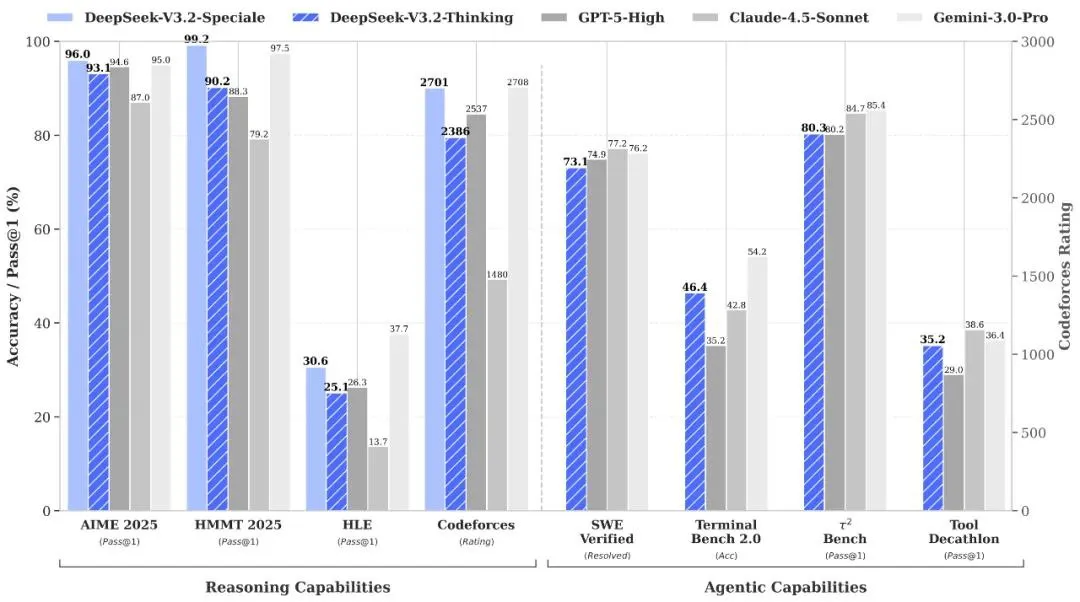
DeepSeek-V3.2-Speciale introduces new reasoning frameworks and internal optimization layers designed for higher stability, interpretability, and long-context accuracy.
These upgrades translate into higher interpretive depth on mathematics, scientific logic, and long analytical tasks, ideal for automation pipelines and cognitive research experiments.
vs Gemini-3.0-Pro: Benchmarks suggest that DeepSeek-V3.2-Speciale reaches roughly similar overall proficiency to Gemini-3.0-Pro, but with a stronger emphasis on transparent, stepwise reasoning for agents.
vs GPT-5: Reported evaluations place DeepSeek-V3.2-Speciale ahead of GPT-5 on difficult reasoning workloads, especially in math-heavy and competition-style benchmarks, while remaining competitive in coding and tool-use reliability
vs DeepSeek-R1: Speciale targets even more extreme reasoning scenarios with 128K context and high-compute thinking mode, making it better suited for agentic frameworks and benchmark-grade experiments rather than casual interactive use.
User feedback on platforms like Reddit highlights DeepSeek V3.2 Speciale as a standout forhigh-stakes reasoning tasks, with strong praise for its benchmark dominance and cost efficiency.
Developers note its superiority over GPT-5 on math, code, and logical benchmarks, often at 15x lower cost, calling it "remarkable" for agentic workflows and complex problem-solving. Many note impressive coherence in long chains, reduced errors, and "human-like" depth, especially vs prior DeepSeek versions.
OpenAI-compatible — swap the base URL and it works with your existing SDK.
| Type | Price |
|---|---|
| Input | |
| Output | |
| Benchmark | Score | What it measures | Source | Retrieved |
|---|---|---|---|---|
| Intelligence | 14.5 | Composite score across standardised reasoning, knowledge and problem-solving evaluations, measured independently by Artificial Analysis | Source | September 12, 2026 |
| Math | 96.7 | Composite score across standardised mathematics evaluations, measured independently by Artificial Analysis | Source | September 12, 2026 |
| AIME 2025 | 96.0% | Competition mathematics (AIME), 2025 | Source | September 20, 2026 |
| GPQA Diamond | 85.7 | Google-proof graduate science questions (hardest subset) | Source | September 20, 2026 |
| LiveCodeBench | 88.7% | Contamination-free competitive programming problems | Source | September 20, 2026 |
| Model | Input | Output | Context | Best for |
|---|---|---|---|---|
DeepSeek-V3.2 Speciale This page | ||||
| Reasoning + agents | ||||
| Balanced coding + agents | ||||
| Long-context, multimodal & agentic workflows | ||||
| Reasoning + agents |
Yes, DeepSeek-V3.2 Speciale can stream responses as they are generated.
Yes, DeepSeek-V3.2 Speciale supports both function calling and structured outputs.
DeepSeek-V3.2 Speciale was built by DeepSeek.
It supports function calling, streaming, and structured outputs, which are features commonly needed to build agentic workflows.
It is accessed via the v1 endpoint.




