Qwen3 VL 32B Instruct is a specialized vision-language large model designed for instruction-following in tasks involving image description, visual dialogue, and content generation. It is a “non-thinking only” version optimized to excel in interpreting visual inputs and generating coherent, context-aware textual output in response to visual content and instructions.
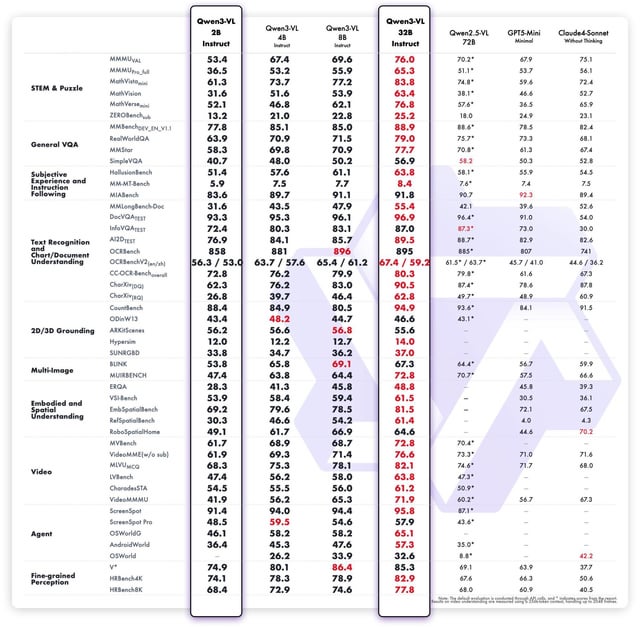
vs Qwen3 VL 32B Base: Instruct version is fine-tuned for better instruction adherence and generates more context-relevant and accurate descriptions, whereas the base targets general multimodal understanding.
vs OpenAI GPT-4 (with vision): Qwen3 VL 32B Instruct is optimized specifically for instruction-following and visual content generation with fewer hallucinations on visual inputs; GPT-4 offers broader general AI capabilities but can be less specialized in visual instruction adherence.
vs Claude 4.5 Visual: Qwen3 VL 32B Instruct provides stronger image description and dialogue quality with a focus on visual instructions, while Claude often excels in text-based reasoning and larger context management but with slightly less visual specialization.
vs DeepSeek V3.1: Qwen3 VL 32B Instruct outperforms in detailed content generation and visualization tasks, whereas DeepSeek focuses more on semantic image search and retrieval functionality.
Measured on the AI/ML API gateway across live traffic. Figures are medians unless stated. Last updated 2026-10-12.
import requests

r = requests.post(
    "https://api.aimlapi.com/v1/chat/completions",
    headers={"Authorization": "Bearer " + AIMLAPI_KEY},
    json={
      "model": "alibaba/qwen3-vl-32b-instruct",
      "messages": [
        {
          "role": "user",
          "content": "Hello!"
        }
      ]
    },
)
print(r.json())
const r = await fetch("https://api.aimlapi.com/v1/chat/completions", {
  method: "POST",
  headers: {
    Authorization: `Bearer ${process.env.AIMLAPI_KEY}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
    "model": "alibaba/qwen3-vl-32b-instruct",
    "messages": [
      {
        "role": "user",
        "content": "Hello!"
      }
    ]
  }),
});
console.log(await r.json());
curl -X POST https://api.aimlapi.com/v1/chat/completions \
  -H "Authorization: Bearer $AIMLAPI_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"alibaba/qwen3-vl-32b-instruct","messages":[{"role":"user","content":"Hello!"}]}'
OpenAI-compatible — swap the base URL and it works with your existing SDK.
| Type | Price |
|---|---|
| Input | |
| Output | |
| Benchmark | Score | What it measures | Source | Retrieved |
|---|---|---|---|---|
| MMMU | 76% | College-level multimodal understanding + reasoning | Source | July 12, 2026 |
| Intelligence | 8.4 | Composite score across standardised reasoning, knowledge and problem-solving evaluations, measured independently by Artificial Analysis | Source | September 12, 2026 |
| Math | 68.3 | Composite score across standardised mathematics evaluations, measured independently by Artificial Analysis | Source | September 12, 2026 |
| Model | Input | Output | Context | Best for |
|---|---|---|---|---|
Qwen3 VL 32B Instruct This page | Coding + agents | |||
| Reasoning + agents | ||||
| Balanced coding + agents | ||||
| Long-context, multimodal & agentic workflows | ||||
| Reasoning + agents |
Qwen3 VL 32B Instruct has a 126,000 tokens context window and can return up to 32,768 tokens.
Qwen3 VL 32B Instruct takes image, text as input and returns text.
Use alibaba/qwen3-vl-32b-instruct as the model id. Requests go to https://api.aimlapi.com/v1/chat/completions.
Qwen3 VL 32B Instruct became available on November 11, 2025.
Qwen3 VL 32B Instruct is priced at input $0.91 / 1M tokens, output $3.64 / 1M tokens.
Yes, Qwen3 VL 32B Instruct can stream responses as they are generated.
Yes, Qwen3 VL 32B Instruct accepts image input alongside text.
Qwen3 VL 32B Instruct was built by Alibaba Cloud.
Yes, it supports function calling, parallel tool calls, structured outputs, and web search.





