Alibaba's Wan2.2 is a state-of-the-art AI model designed for multi-modal understanding, especially integrating text and vision inputs. It supports large context processing with superior precision in text-to-vision tasks and complex reasoning.
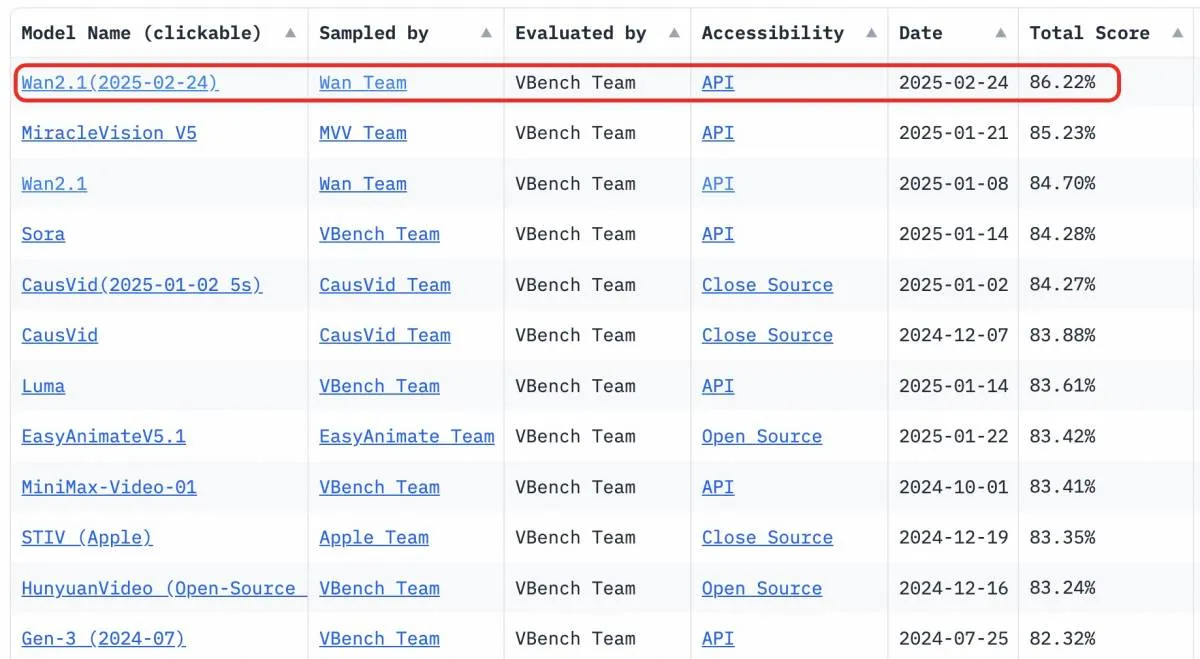
Wan2.1 leads with an overall VBench score of 86.22%, excelling in dynamic motion, spatial relationships, color accuracy, and multi-object interaction. Training foundational video models demands vast compute power and large, high-quality datasets. Open access to these models reduces barriers, empowering more businesses to create tailored, high-quality visual content in a cost-effective way.
Vs. Gemini 2.5 Flash: Higher multi-modal accuracy (78.3% vs. 70.8% VQA-bench), better for integrated tasks.
Vs. OpenAI GPT-4 Vision: Larger context window (65K vs. 32K tokens text) supports longer conversations with images.
Vs. Qwen3-235B-A22B: Superior cross-modal retrieval precision (81.9% vs. ~78% estimated), optimized for large-scale vision-language workflows.
Occasionally, videos may contain unwanted elements such as text artifacts or watermarks; using negative prompts can mitigate but does not fully eliminate these occurrences.
Accessible via AI/ML API. Documentation: available here.
import requests, time

headers = {"Authorization": "Bearer " + AIMLAPI_KEY}
job = requests.post(
    "https://api.aimlapi.com/v2/video/generations",
    headers=headers,
    json={
      "model": "alibaba/wan2.2-t2v-plus",
      "prompt": "A serene timelapse of clouds over a mountain range"
    },
).json()
gid = job["id"]

while True:
    res = requests.get(f"https://api.aimlapi.com/v2/video/generations?generation_id={gid}", headers=headers).json()
    if res.get("status") in ("completed", "error"):
        break
    time.sleep(5)
print(res["video"]["url"])
const headers = {
  Authorization: `Bearer ${process.env.AIMLAPI_KEY}`,
  "Content-Type": "application/json",
};
const job = await (await fetch("https://api.aimlapi.com/v2/video/generations", {
  method: "POST",
  headers,
  body: JSON.stringify({
    "model": "alibaba/wan2.2-t2v-plus",
    "prompt": "A serene timelapse of clouds over a mountain range"
  }),
})).json();

let res;
do {
  await new Promise((r) => setTimeout(r, 5000));
  res = await (await fetch(`https://api.aimlapi.com/v2/video/generations?generation_id=${job.id}`, { headers })).json();
} while (!["completed", "error"].includes(res.status));
console.log(res.video.url);
# submit the generation — the response contains the job "id"
curl -X POST https://api.aimlapi.com/v2/video/generations \
  -H "Authorization: Bearer $AIMLAPI_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"alibaba/wan2.2-t2v-plus","prompt":"A serene timelapse of clouds over a mountain range"}'

# then poll until status is "completed" — video.url holds the result
curl "https://api.aimlapi.com/v2/video/generations?generation_id={id}" -H "Authorization: Bearer $AIMLAPI_KEY"
OpenAI-compatible — swap the base URL and it works with your existing SDK.
| Type | Price |
|---|---|
| Output | |
| Model | Input | Output | Context | Best for |
|---|---|---|---|---|
Wan 2.2 Plus Text to Video This page | Video generation |
Wan 2.2 Plus Text to Video takes text as input and returns video.
Wan 2.2 Plus Text to Video became available on November 20, 2025.
Wan 2.2 Plus Text to Video is priced at $0.525 / gen.
Wan 2.2 Plus Text to Video is billed per generation — a fixed charge per output rather than by prompt length.
Wan 2.2 Plus Text to Video was built by Alibaba Cloud.
Send a request to v2/generate/video/alibaba/generation with alibaba/wan2.2-t2v-plus as the model id.
Yes. Wan 2.2 Plus Text to Video is served through AI/ML API, so the same key and endpoint format used for other models applies.
It generates high-quality videos from text prompts with improved stability and coherence.



