Ox Alpha: Benchmarks, API Access, and Who Built It
Update: Z.ai confirmed on August 26, 2026 that Ox Alpha is GLM-5.3-Flash. On AI/ML API, it is available under the model ID z-ai/glm-5.3-flash. We tested GLM-5.3-Flash against MiniMax M3.1 Flash and DeepSeek V4.1 Flash in our MiniMax M3.1 Flash review. The tests and benchmarks below come from the Ox Alpha preview.
We've added Ox Alpha to AI/ML API. Here's everything you need to know about the new model.
What is Ox Alpha?
Ox Alpha launched as an anonymous (“stealth”) AI reasoning model aimed heavily at coding, complex reasoning, and long-running AI-agent tasks. Its features: a 1,048,576-token context window, up to 131,072 output tokens, and support for text, images, and video as input. It also supports tool/function calling and structured output.
The free stealth preview has ended. On AI/ML API, Ox Alpha is now available as GLM-5.3-Flash under the model ID z-ai/glm-5.3-flash.
Ox Alpha Main Features
Ox Alpha combines a large context window with multimodal input, extended reasoning, tool calling, and structured text output. Here are the model's main features:
| Specification | Value |
|---|---|
| model identifier | z-ai/glm-5.3-flash |
| preview release date | August 20, 2026 |
| release status | revealed as GLM-5.3-Flash on August 26, 2026; the free stealth preview has ended |
| developer | Z.ai (Zhipu AI) |
| primary use cases | coding, complex reasoning, sustained agentic work, and production workflows |
| context window | 1,048,576 tokens |
| maximum completion | 131,072 tokens |
| input modalities | text, images, and video |
| output modality | text |
| reasoning | supported; requests may include reasoning controls |
| tool calling | supported through tools and tool_choice |
| structured output | JSON output through response_format; JSON Schema enforcement is not documented |
| API format | OpenAI-compatible Chat Completions |
| AI/ML API endpoint | https://api.aimlapi.com/v1/chat/completions |
| authentication | Bearer API key in the Authorization header |
| required request fields | model and messages |
| output limit parameter | max_completion_tokens |
| provider routing | provider: "auto" uses the available fallback chain; a supported provider key can override it |
| token price on AI/ML API | $0.15 per million input tokens, $0.50 per million output tokens, and $0.03 per million cached input tokens |
| OpenRouter data handling during the preview | prompts and completions were retained by the provider but were not used for training |
We tested Ox Alpha
We tested Ox Alpha through AI/ML API with temperature: 0 and compared it with GLM, MiMo, and Qwen models. Here's what we found:
| Finding | What we measured | Why it matters |
|---|---|---|
| Same tokenizer as GLM | Ox Alpha counted all 8 test packs exactly like GLM-5.2 and GLM-5.3. GLM vision models matched 5 packs. MiMo and Qwen matched 2. | Ox Alpha most likely uses the same tokenizer as GLM-5.2 and GLM-5.3. |
| About 85 hidden input tokens | A four-token message used 91 prompt tokens. The extra tokens appeared on every repeated call. | Each request uses about 85 more input tokens than the prompt alone. |
| 35 to 39 tokens per second | Ox Alpha reached 35 to 39 tokens per second on two identical tests. GLM-5.3 reached about 69. | Ox Alpha was about twice as slow as GLM-5.3 in this test. |
| Speed changed during the hour | The reported median speed fell from 60.42 to 17.69 tokens per second in 45 minutes. The first token arrived after about 9 to 10 seconds. | Response time can vary a lot during the day. |
| Reasoning counted as output | A one-word answer used 36 completion tokens but reported zero reasoning tokens. GLM-5.3 counted 30 of its 35 tokens as reasoning. | Ox Alpha does not show how many tokens it spent thinking. |
Before the reveal, it was widely thought that Ox Alpha was part of the GLM model family, and our tokenizer test counted every test string exactly like GLM-5.2 and GLM-5.3. Thus, Ox Alpha most likely uses the same tokenizer as the GLM models.
Ox Alpha generated 35 to 39 tokens per second. GLM-5.3 completed the same task at about 69 tokens per second, so it was almost twice as fast.
Ox Alpha’s speed also changed during the session. Its median fell from 60.42 to 17.69 tokens per second in 45 minutes. The slowest one percent of requests grew from about 45 seconds to 131 seconds. A product using Ox Alpha during the preview had to allow for these large swings.
How does Ox Alpha Perform? Benchmark Results
The table below shows how Ox Alpha performs in software engineering benchmarks:
| Benchmark | Ox Alpha result | Evaluation setup |
|---|---|---|
| Early DeepSWE sample | 8/10 tasks solved (80%) | Ten repository-level coding tasks; one recorded result per task for Ox Alpha |
| Full DeepSWE community run | 66/113 tasks solved (58.4%) | pier 0.3.1, mini-swe-agent, and a Docker backend |
| LiveCodeBench release_v6 | 49/175 problems solved (28.0% pass@1) | Greedy decoding, one attempt, no tools or agent scaffold |
| SlopCodeBench | 7/39 strict checkpoints passed (17.9%) | Eight cumulative repository-maintenance trajectories using pi 0.84.2 |
DeepSWE is a benchmark that closely mimics real-world software engineering. It contains 113 new tasks from 91 active open-source repositories in TypeScript, Go, Python, JavaScript, and Rust. For each task, the agent receives a repository and a change request. The benchmark then runs tests to check whether the change works.
In the first recorded public benchmark run, Ox Alpha solved eight of the ten requests, giving it an 80% completion score (Claude Fable 5 from Anthropic, for example, scored 65% and GLM-5.3 from Zhipu AI scored 62%).
However, on a larger run that included all 113 DeepSWE tasks, Ox Alpha completed 66 tasks, giving it a 58.4% completion score, often coming close on the remaining tasks. It passed at least 90% of the new tests on about 80% of all tasks. DeepSWE still counted an almost-correct task as a failure when even one required test failed. This explains how the model could make useful changes while finishing only 58.4% of the tasks.
Ox Alpha Vs. Other Models
The tables below show how Ox Alpha performs vs other models.
An independent Ox Alpha run solved 66 tasks. The official DeepSWE leaderboard reports higher scores for several competing models.
| Model | DeepSWE score | Source |
|---|---|---|
| Claude Opus 5 (max) | 74% ±4% | official leaderboard |
| GPT-5.6 Sol (max) | 73% ±3% | official leaderboard |
| Claude Fable 5 (max) | 70% ±4% | official leaderboard |
| GLM-5.3 (max) | 69% ±3% | official leaderboard |
| Claude Opus 4.8 (max) | 59% ±2% | official leaderboard |
| Ox Alpha | 58.4% (66/113) | independent community run |
Based on DeepSWE results, Ox Alpha performs similarly to Claude Opus 4.8.
SlopCodeBench tests if a model can keep working on the same project while keeping old features working. All three models below used the same 39-checkpoint set.
| Model | All tests passed | Current tests passed | Core task passed |
|---|---|---|---|
| GLM-5.3 | 11/39 (28.2%) | 17/39 (43.6%) | 26/39 (66.7%) |
| Ox Alpha | 7/39 (17.9%) | 10/39 (25.6%) | 21/39 (53.8%) |
| Qwen3.8-27B | 5/39 (12.8%) | 8/39 (20.5%) | 17/39 (43.6%) |
On this test, Ox Alpha fell behind GLM-5.3. It often completed the core task, but later changes broke tests or missed edge cases. None of its eight projects passed every test at the final checkpoint.
Ox Alpha is a good coding generalist, but its performance begins to deteriorate over time while working on the same codebase. In our later test of MiniMax M3.1 Flash alternatives, GLM-5.3-Flash passed 28 of 30 runs, including all nine vision runs.
Who built Ox Alpha
Z.ai confirmed on August 26, 2026 that Ox Alpha is GLM-5.3-Flash. Before the reveal, the technical evidence already pointed toward Zhipu AI, now more widely known as Z.ai. Our own research above found the same clues.
Specifically, the clues pointed to their GLM-5 generation.
What we knew before the reveal
Ox Alpha first appeared on OpenRouter on August 20, 2026, under the model ID stealth/ox-alpha with this attribution:
it was developed and operated by a third-party provider that chose to remain anonymous.
However, independent researchers tested characteristics that are difficult for a model to fake and found that:
1. Its tokenizer is almost a fingerprint for GLM.
In one reproducible investigation, 44 out of 44 discriminating test strings matched the GLM-5-generation tokenizer exactly. Competing tokenizers performed noticeably worse: Qwen, OpenAI tokenizers, Kimi and DeepSeek all produced different results on multiple tests.
2. Ox Alpha appears to use Z.ai's server infrastructure.
Researchers deliberately sent malformed API requests to the service and one bad request caused the upstream system to reveal a Java class path:
com.wd.paas.api.domain.v4.chat.ChatCompletionRequest
This API structure can be linked to Zhipu/Z.ai's serving infrastructure. Ox Alpha also reportedly produced distinctive numerical error codes and message formats matching Z.ai-hosted GLM models.
3. Its video processing behaves like Zhipu's GLM vision models.
The video-token behavior of Ox Alpha matches GLM-5V-Turbo across several characteristics, including sampling behavior, video duration and resolution scaling. That suggests Ox Alpha may share not only a language-model tokenizer but also parts of Zhipu's multimodal processing stack.
4. Its reasoning controls resemble GLM-5.
Finally, Ox Alpha exposes reasoning levels such as low, high, and max, with reasoning essentially built into the model's operation. There are similarities between these controls and those documented for recent GLM models. Its context limits and output ceiling also line up well with GLM-5.
Fun fact: Ox Alpha isn't even the first “Alpha” model to follow this pattern. Previous anonymous models have eventually been revealed as models from companies including Chinese AI labs. For example, Zhipu's earlier Pony Alpha was eventually associated with GLM-5.
How to access Ox Alpha through AI/ML API
AI/ML API offers two ways to access Ox Alpha.
- In the Playground
- Through the API
Option 1: Test Ox Alpha in the Playground
- Sign in to AI/ML API and open the Playground.
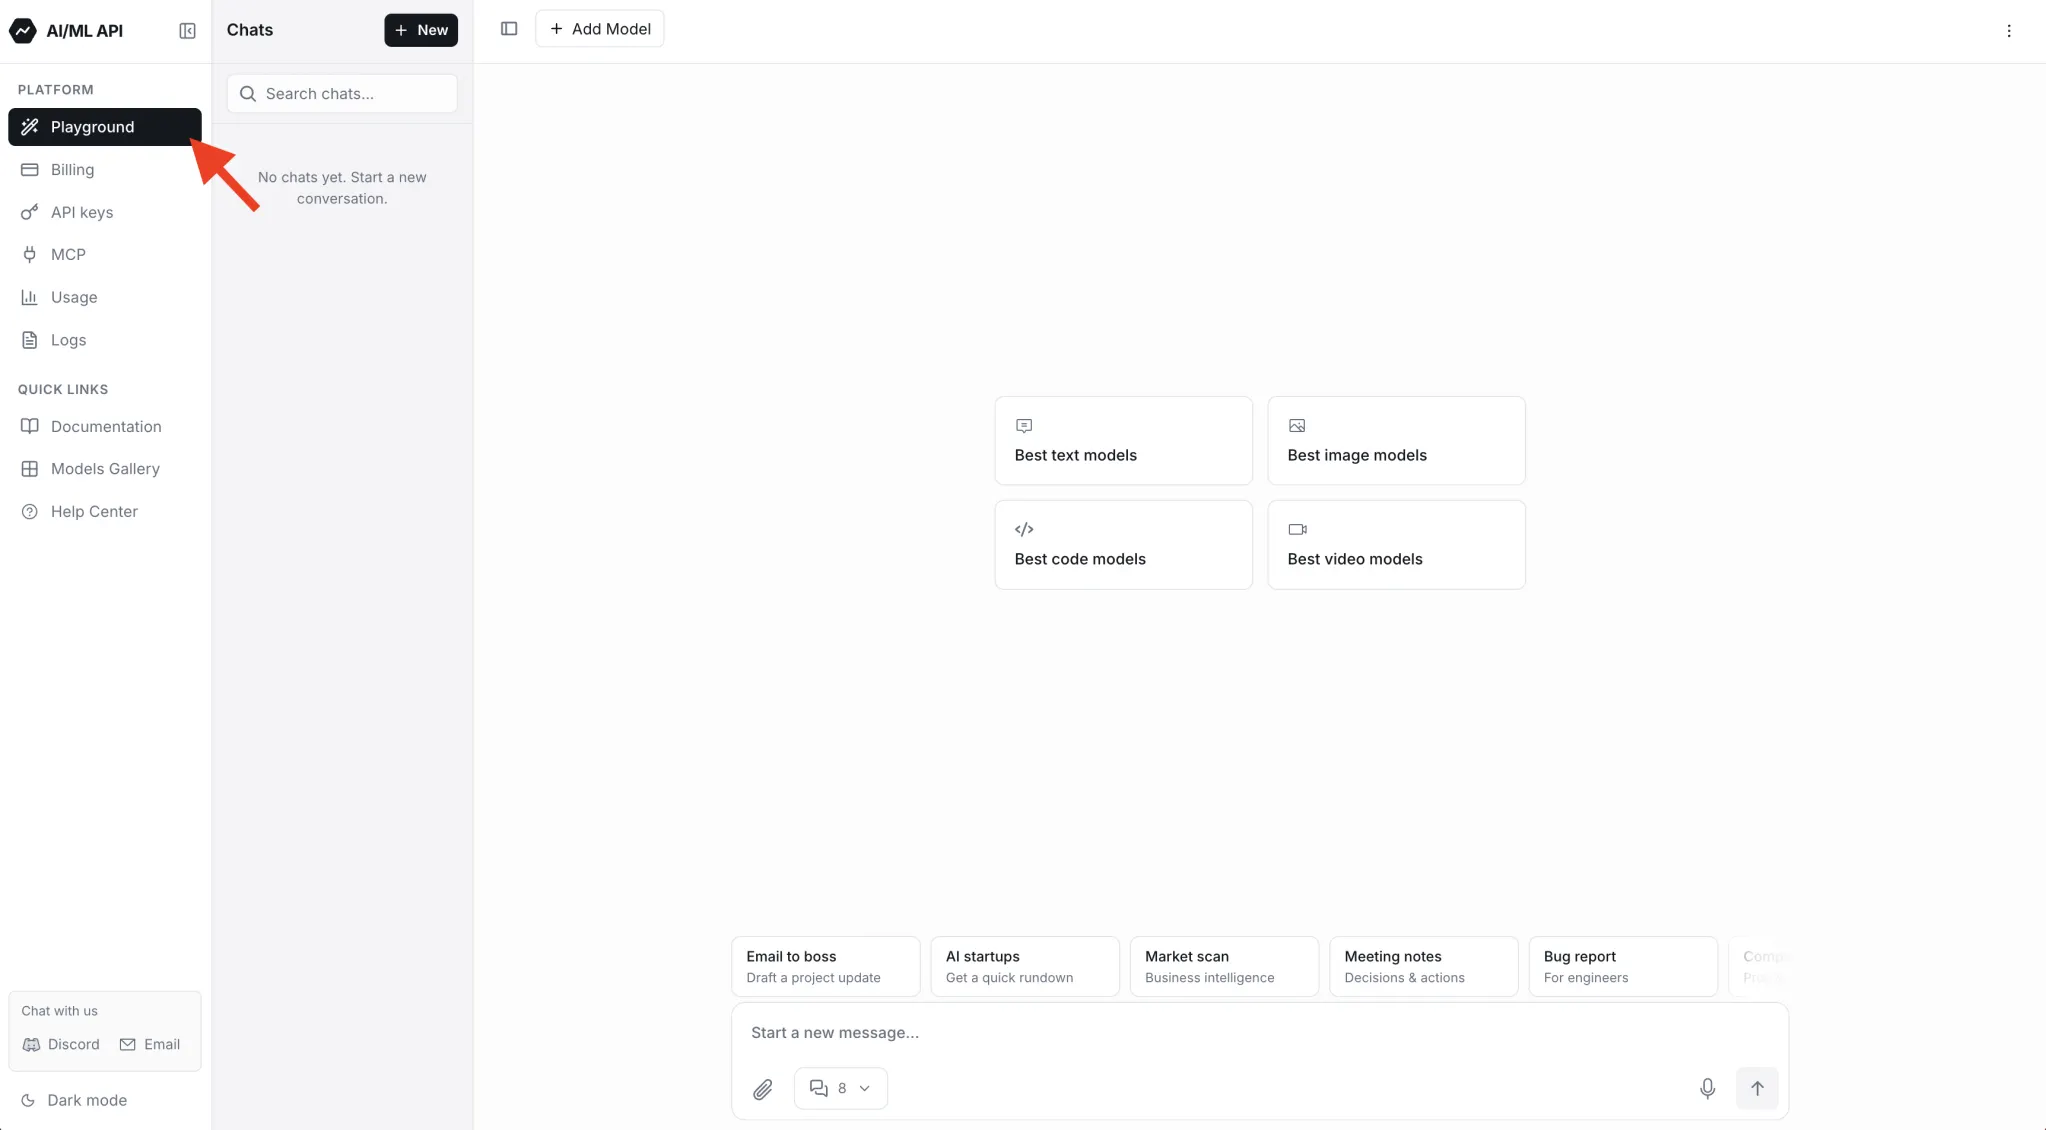
- Select Playground in the left sidebar.
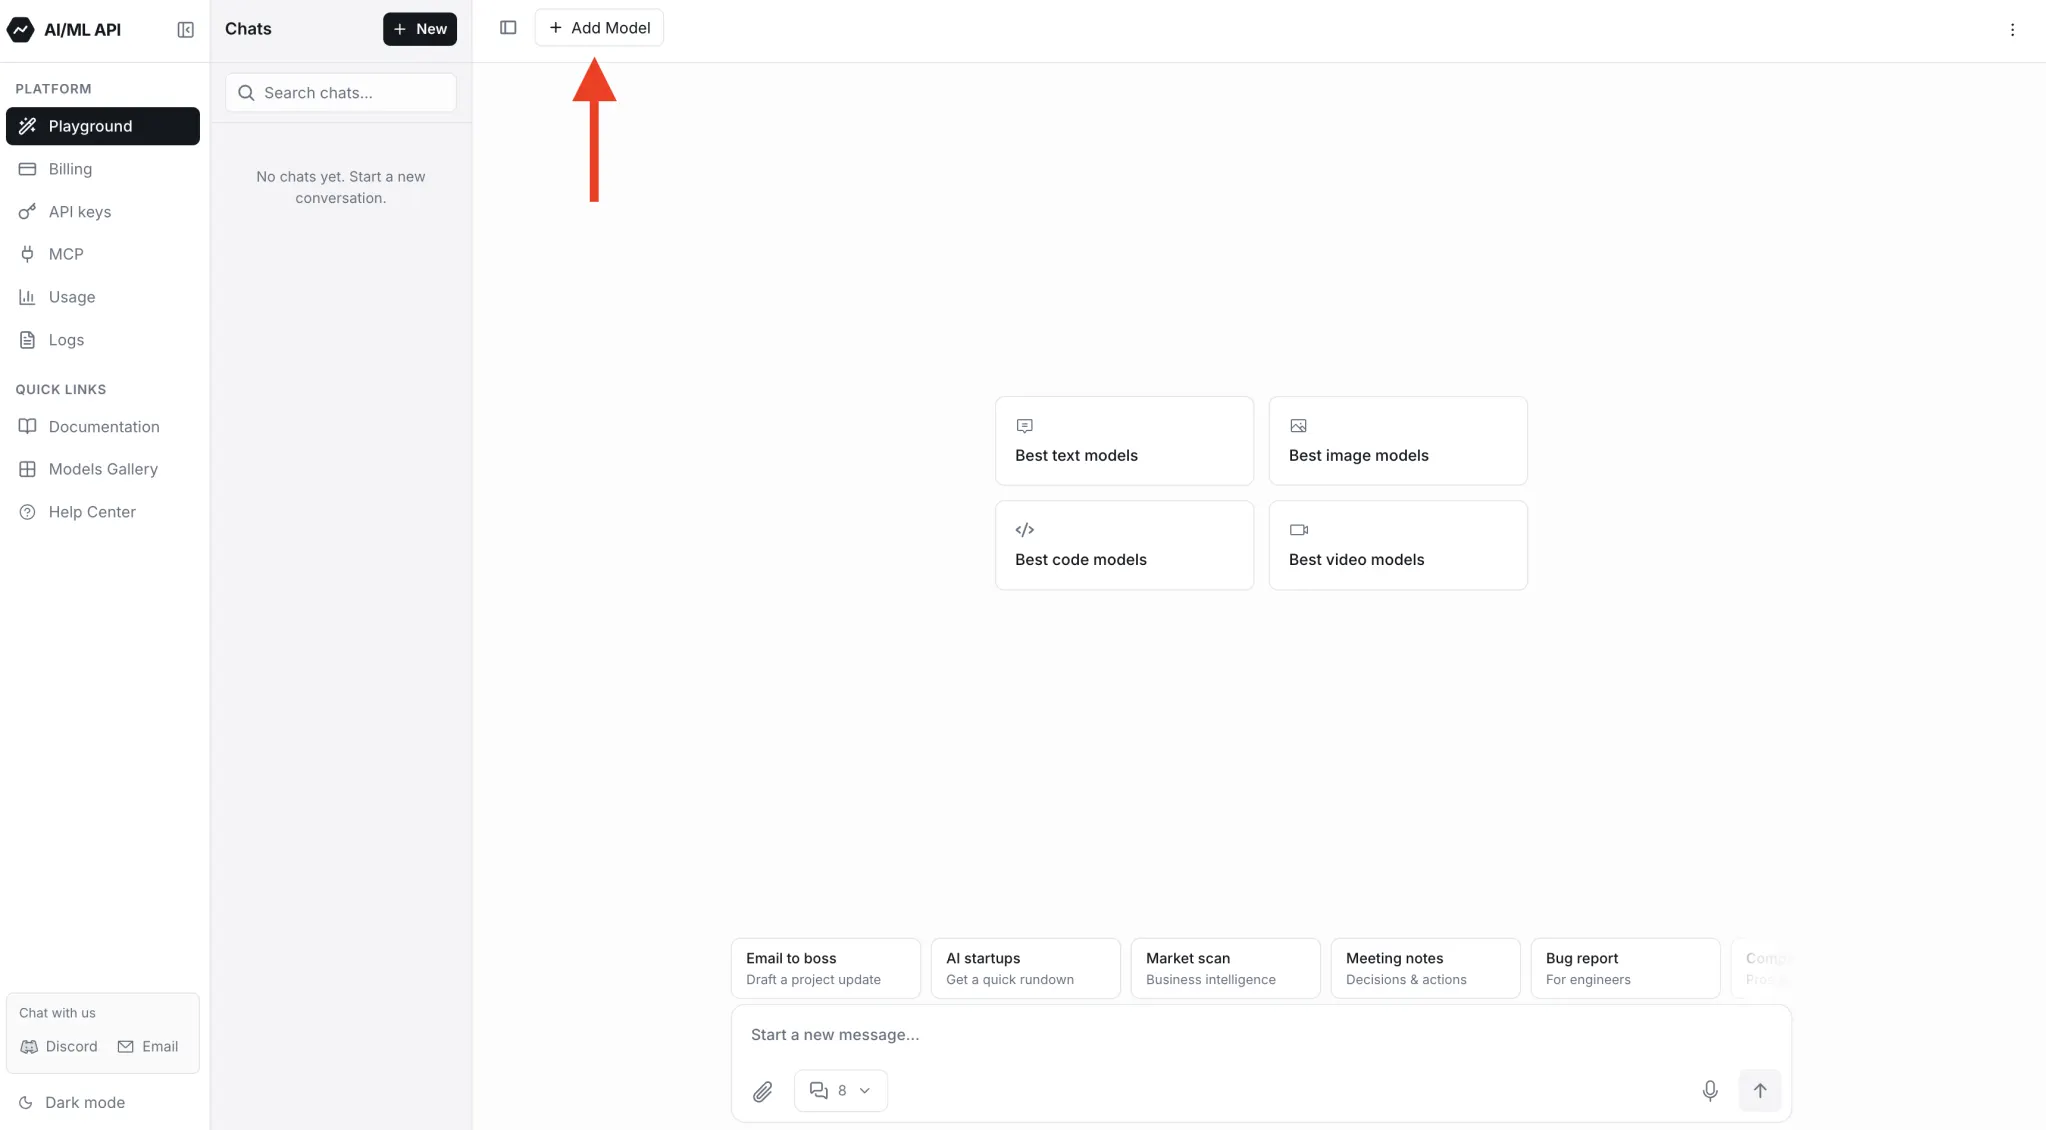
- Click Add Model at the top of the page.
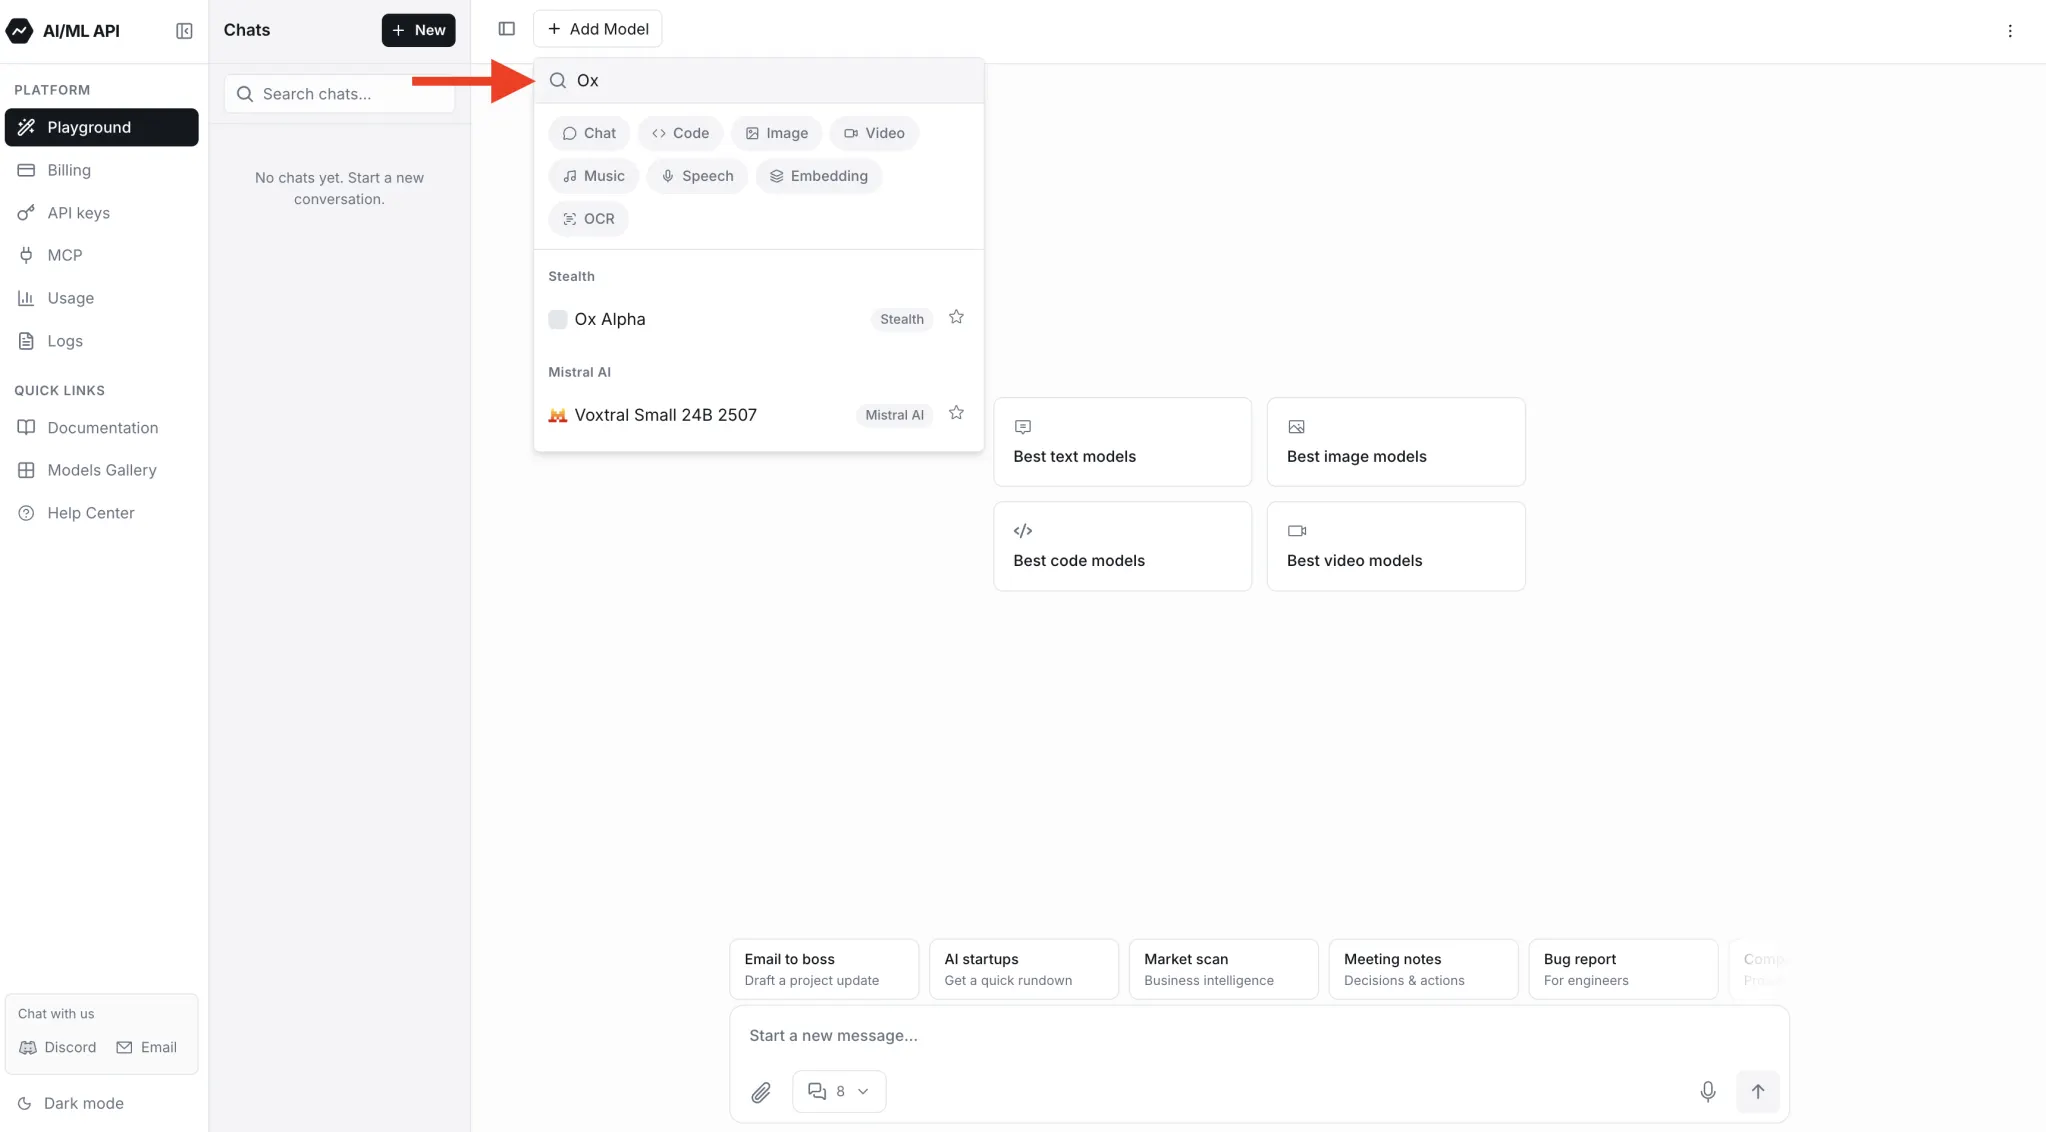
- Enter GLM in the model search box.
- Select GLM-5.3-Flash.
- Enter a prompt in the message box and send it.
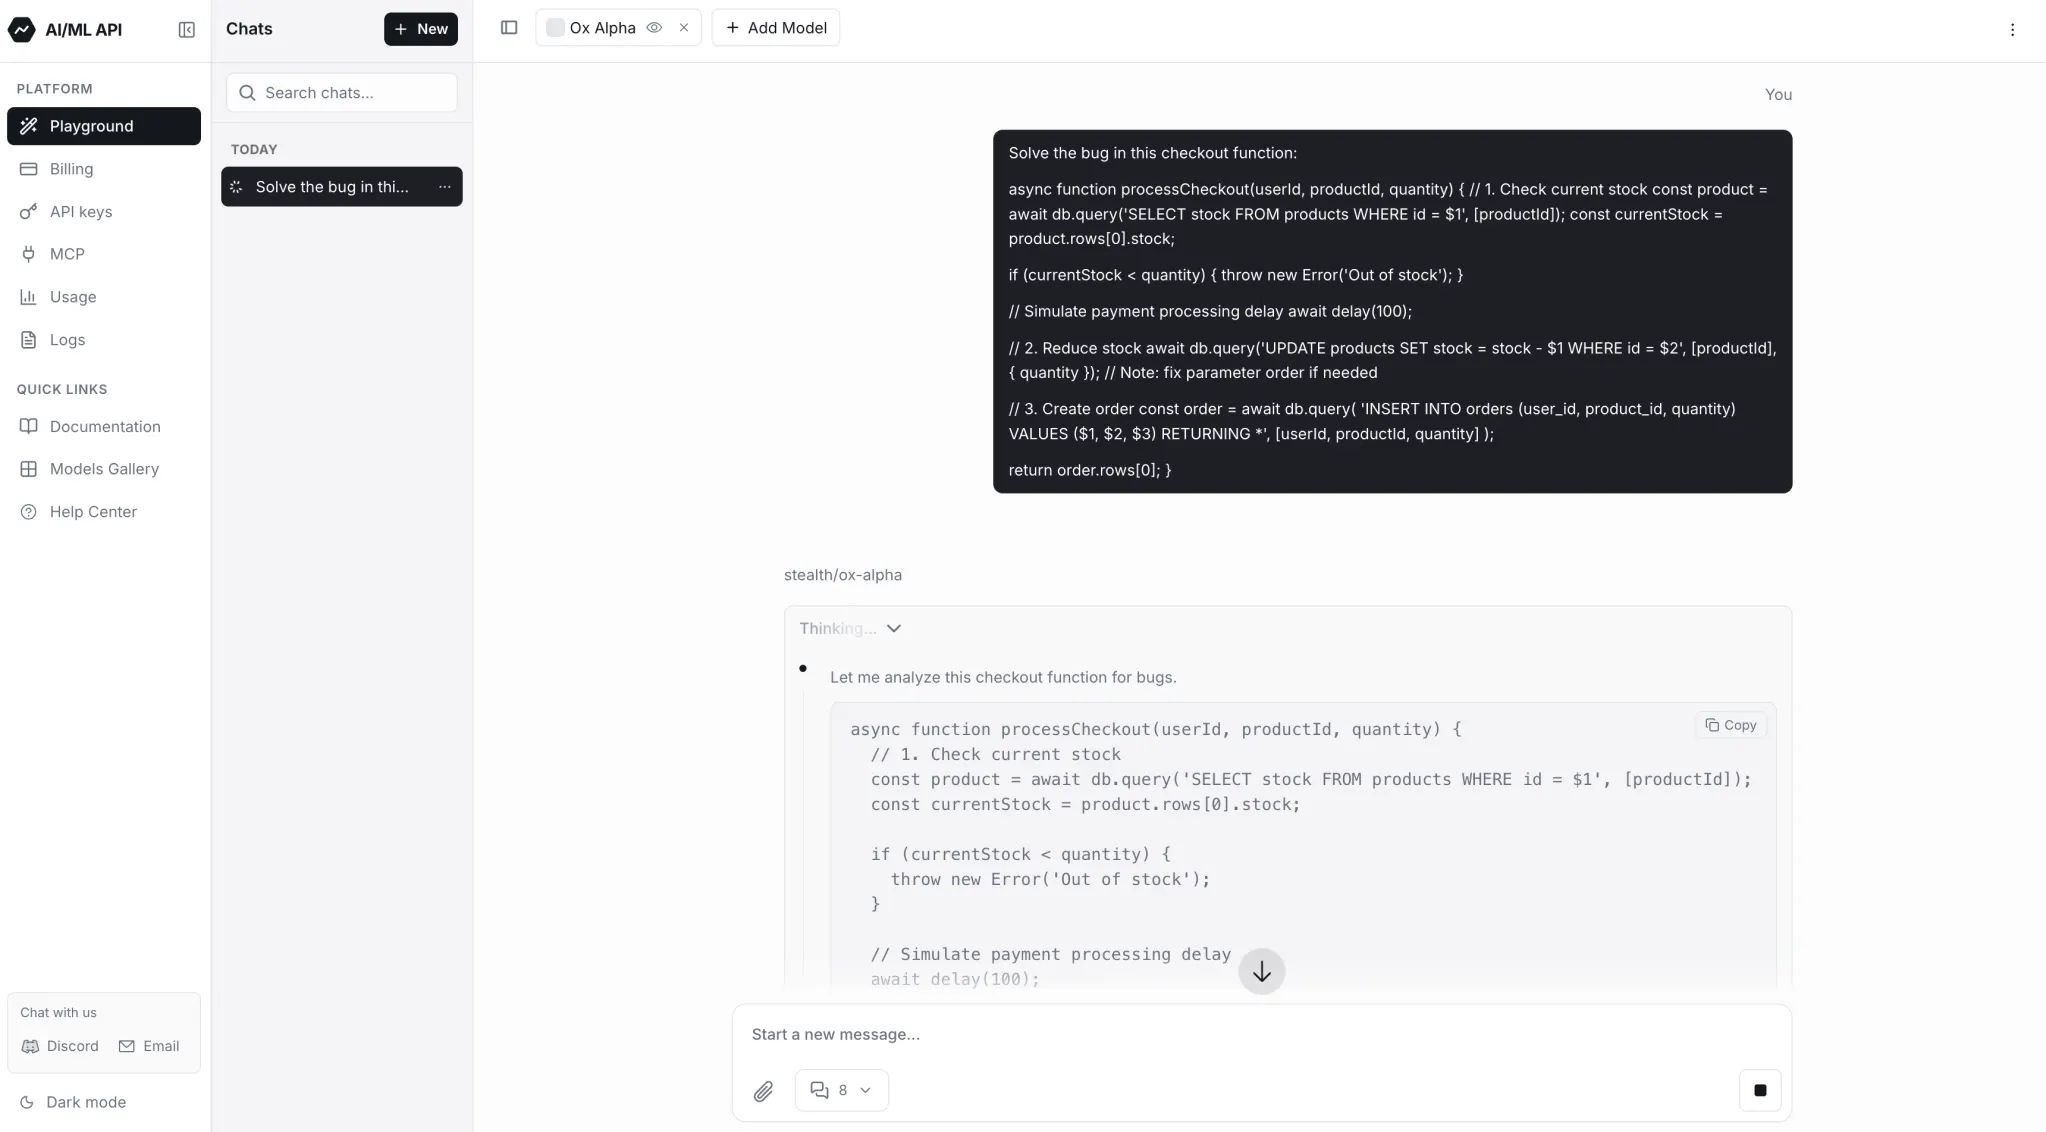
The Playground limits prompts to 5,000 characters and exposes only basic settings. Use the API for larger inputs, automated tests, tool calling, or application integration.
Option 2: Call Ox Alpha through the API
1. Create an API key
Open API keys, click Create API Key, and make sure the key is enabled. Store it in an environment variable. Do not put the key in browser code or commit it to a repository.
On macOS or Linux:
export AIMLAPI_KEY="YOUR_AIMLAPI_KEY"On Windows PowerShell:
$env:AIMLAPI_KEY="YOUR_AIMLAPI_KEY"2. Send a request
Ox Alpha uses the OpenAI-compatible Chat Completions endpoint:
POST https://api.aimlapi.com/v1/chat/completionsFor the full schema, see the GLM-5.3-Flash API reference.
Every request needs two fields:
| Field | Value |
|---|---|
model | z-ai/glm-5.3-flash |
messages | The conversation, including at least one user message |
Run this command in a terminal:
curl -L --request POST \
  --url "https://api.aimlapi.com/v1/chat/completions" \
  --header "Authorization: Bearer $AIMLAPI_KEY" \
  --header "Content-Type: application/json" \
  --data '{
    "model": "z-ai/glm-5.3-flash",
    "messages": [
      {
        "role": "user",
        "content": "Review this checkout workflow for race conditions. Explain the bug, then return a safe implementation."
      }
    ],
    "temperature": 0,
    "max_completion_tokens": 2000
  }'
You can also set temperature to control randomness and max_completion_tokens to limit the combined reasoning and answer length.
3. Check the response
A successful response contains a choices array. Read the answer from:
choices[0].message.contentAlso check choices[0].finish_reason. A value of stop means the model finished normally. A value of length means it reached max_completion_tokens; increase the limit or request a shorter answer.
FAQ
Is the model called Ox Alpha or 0x Alpha?
The model is called Ox Alpha, with the letter O, not 0x Alpha with a zero. The name causes confusion because 0x commonly marks hexadecimal numbers. The preview model ID was stealth/ox-alpha. The model is now available as GLM-5.3-Flash under the model ID z-ai/glm-5.3-flash.
Is Ox Alpha free?
No. Ox Alpha cost $0 per million input and output tokens during its stealth preview. That free preview has ended. The model is now available as GLM-5.3-Flash. On AI/ML API, it costs $0.15 per million input tokens, $0.50 per million output tokens, and $0.03 per million cached input tokens.
Does Ox Alpha retain my code?
During the preview, data handling depended on the route. OpenRouter said the provider retained prompts and completions but did not use them for training. OpenCode Zen listed zero data retention and no training. Do not send private code, secrets, personal data, or regulated information unless the policy for your chosen route allows it.
Was Ox Alpha developed by Microsoft?
No. Z.ai confirmed on August 26, 2026 that Ox Alpha is GLM-5.3-Flash. Microsoft was an early candidate. Before the reveal, the technical evidence pointed more strongly to Zhipu AI, also known as Z.ai. Ox Alpha counted all tokenizer probes exactly like GLM-5.2 and GLM-5.3. Researchers also found error messages associated with Z.ai’s infrastructure.
Is Ox Alpha better than Claude or GPT for coding?
Ox Alpha did not beat Claude or GPT across coding tests. It led an early ten-task sample with 80%. It scored 58.4% on the full DeepSWE run. The official leaderboard lists Claude Opus 5 at 74% and GPT-5.6 Sol at 73%. The larger test gave Claude and GPT the stronger results.
Bottom line
Ox Alpha is a model for coding and agentic workflows that launched in stealth. Z.ai confirmed on August 26, 2026 that it is GLM-5.3-Flash. The free stealth preview has ended. Here are the key takeaways:
Key takeaways
- Ox Alpha is best suited to coding and agentic work. Ox Alpha can analyze repositories, debug across multiple files, review large documents, use tools, and maintain context across long workflows.
- The model provides a roughly one-million-token context window, produces up to about 128K tokens, and accepts text, images, and video.
- Access is OpenAI-compatible. Use the model ID
z-ai/glm-5.3-flashwith the Chat Completions API and keep the Bearer API key in a server-side environment variable. - The free stealth preview has ended. On AI/ML API, GLM-5.3-Flash costs $0.15 per million input tokens, $0.50 per million output tokens, and $0.03 per million cached input tokens.
- Users can access GLM-5.3-Flash on AI/ML API through our OpenAI-compatible endpoint.